MONIMEGA
  • Blog
    • Politics
    • Software
    • Technology
    • Business
    • Design
    • Hardware
    • Health
    • Italy
    • Music
    • Sports
    • Strategy
    • World
  • Contatto
  • Galleria
  • Informazioni
  • Servizi
  • Regione, Occhiuto: Fascicolo sanitario elettronico è nuovo risultato. Avremo qualcosa in più rispetto altre realtà

    July 22, 2025
    Italy

    Regione Calabria

    Riceviamo e pubblichiamo

    “Oggi presentiamo un nuovo risultato che ci pone a livello delle altre regioni.

    Anzi, in relazione al fascicolo sanitario elettronico avremo qualcosa in più grazie alla chiusura della vertenza Abramo”.

    Lo ha detto il presidente della Regione, Roberto Occhiuto, intervenendo nel corso del roadshow sul tema dell’ecosistema dati sanitari: il fascicolo sanitario elettronico per modernizzare la sanità, organizzato da Regione Calabria e Azienda Zero.

    In particolare, Occhiuto ha fatto riferimento all’impiego del personale dipendente dell’azienda Abramo Customer Care nel progetto di dematerializzazione delle cartelle cliniche.

    “Un’idea – ha aggiunto il presidente – che alcuni avevano giudicato troppo visionaria.

    La Calabria sarà, invece, l’unica regione che avrà allegate al fascicolo sanitario elettronico le cartelle cliniche. Saremo una regione all’avanguardia.

    Tutto merito di Azienda Zero e Miserendino, a cui sono molto grato”.

    Nel corso dell’iniziativa sono stati illustrati i primi risultati raggiunti dalla Calabria nell’ambito del progetto del Pnrr, che prevede un investimento di oltre un miliardo di euro a livello nazionale e che destina, in particolare, 610 milioni alle regioni.

    Alla Calabria sono state assegnate risorse per 12,7 milioni di euro per il rafforzamento delle piattaforme digitali e 11 milioni per favorire la diffusione dell’uso del fascicolo sanitario elettronico.

    “È uno strumento che consente l’accesso sia agli assistiti che ai professionisti ed è uniforme su tutto il territorio regionale”, ha detto Gandolfo Miserendino, direttore generale di Azienda Zero.

    Nel fascicolo sanitario elettronico, secondo quanto é stato riferito, saranno consultabili le prescrizioni mediche dematerializzate e i referti di esami strumentali.

    “È un percorso – ha aggiunto Miserendino – che si avvia. I mesi precedenti sono serviti per portare l’alimentazione del fascicolo sanitario. Su questo aspetto, misurato a livello nazionale con specifici indicatori, siamo al 70% in media.

    Siamo, inoltre, una delle prime regioni in Italia ad effettuare il primo conferimento di cartelle cliniche.

    Nella giornata di ieri ne abbiamo trasferite cinquanta. Adesso inizierà un importante processo di dematerializzazione.

    È l’inizio di un percorso che permetterà a tutti gli assistiti di Regione Calabria di avere la propria cartella clinica al termine del ricovero”.

    Il presidente Occhiuto si è poi soffermato sull’operatività di Azienda Zero, ente di governance della sanità calabrese e frutto di una specifica riforma.

    “Azienda zero – ha detto il presidente – ci ha già permesso di conseguire i target del Pnrr sulla digitalizzazione della sanità.

    Sta accentrando tutte le procedure per le assunzioni in sanità, senza delegarle più alle aziende sanitare, e tutte le funzioni amministrative”.


    Source: Irriverentemente.

  • Mystery AMD Radeon GPU cooler spotted on Chinese forums is larger than RX 7900 XTX, with a massive heatsink and 3x 8-pin connectors — possibly the RX 7950 XTX that never was

    Mystery AMD Radeon GPU cooler spotted on Chinese forums is larger than RX 7900 XTX, with a massive heatsink and 3x 8-pin connectors — possibly the RX 7950 XTX that never was

    July 22, 2025
    Hardware

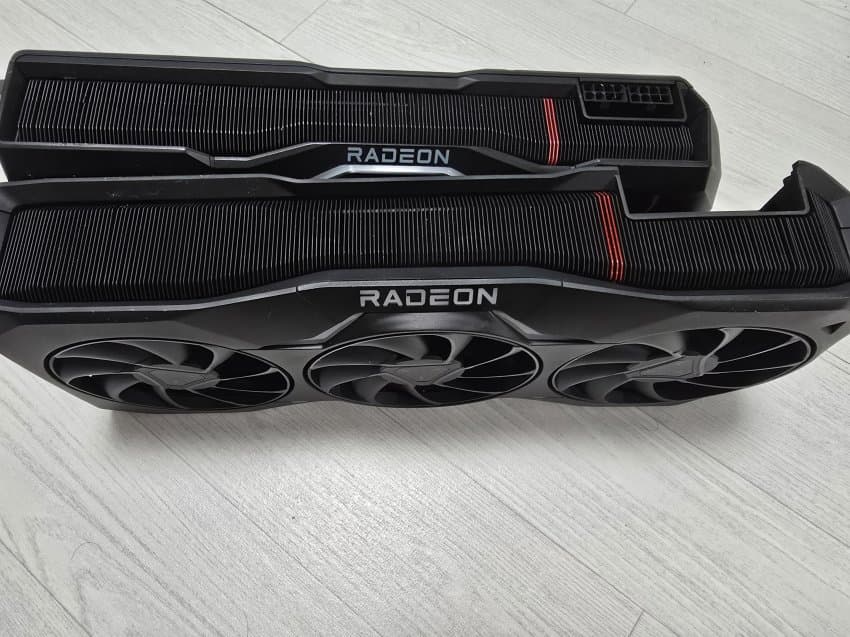
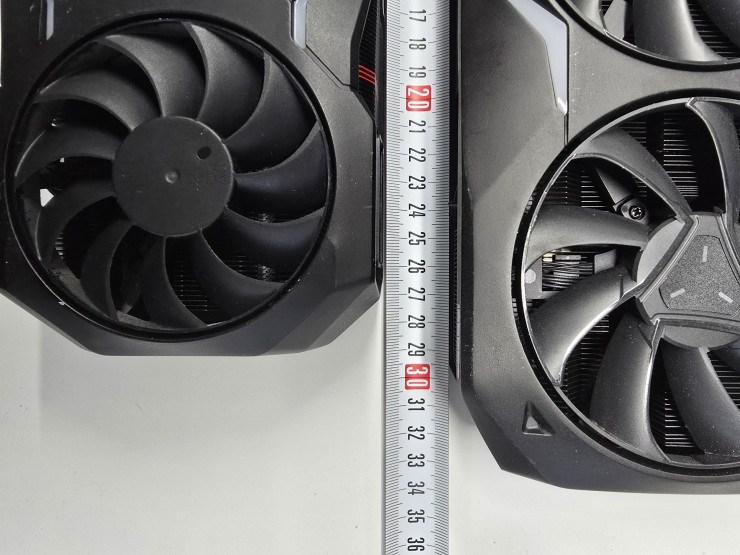
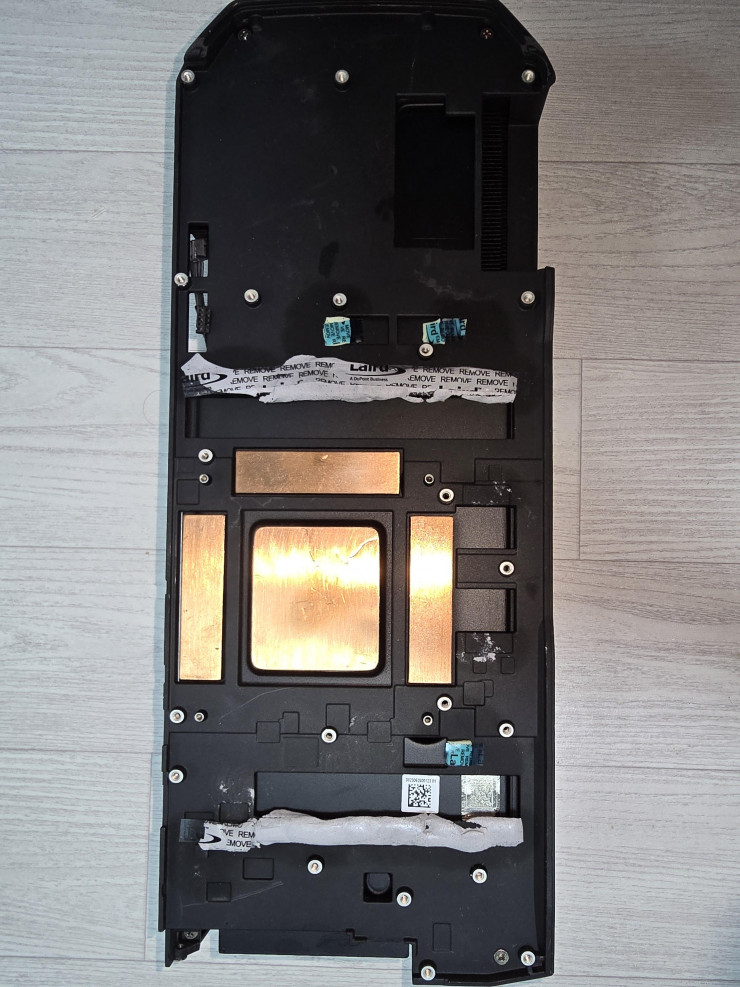
    A massive prototype cooler from AMD’s Radeon RX 7000 series has surfaced online, sparking speculation that AMD once considered a true RTX 4090-class GPU during the RDNA 3 era. The leak originated from Korean forum Quasarzone, where a user named FP32 shared images of a mysterious shroud purchased from the Chinese marketplace Xianyu. At first glance, it looks like a standard RX 7900 XTX reference cooler, but a second look reveals another story entirely. Thankfully, the user broke down everything, comparing the cooler with an actual, retail RX 7900 XTX.

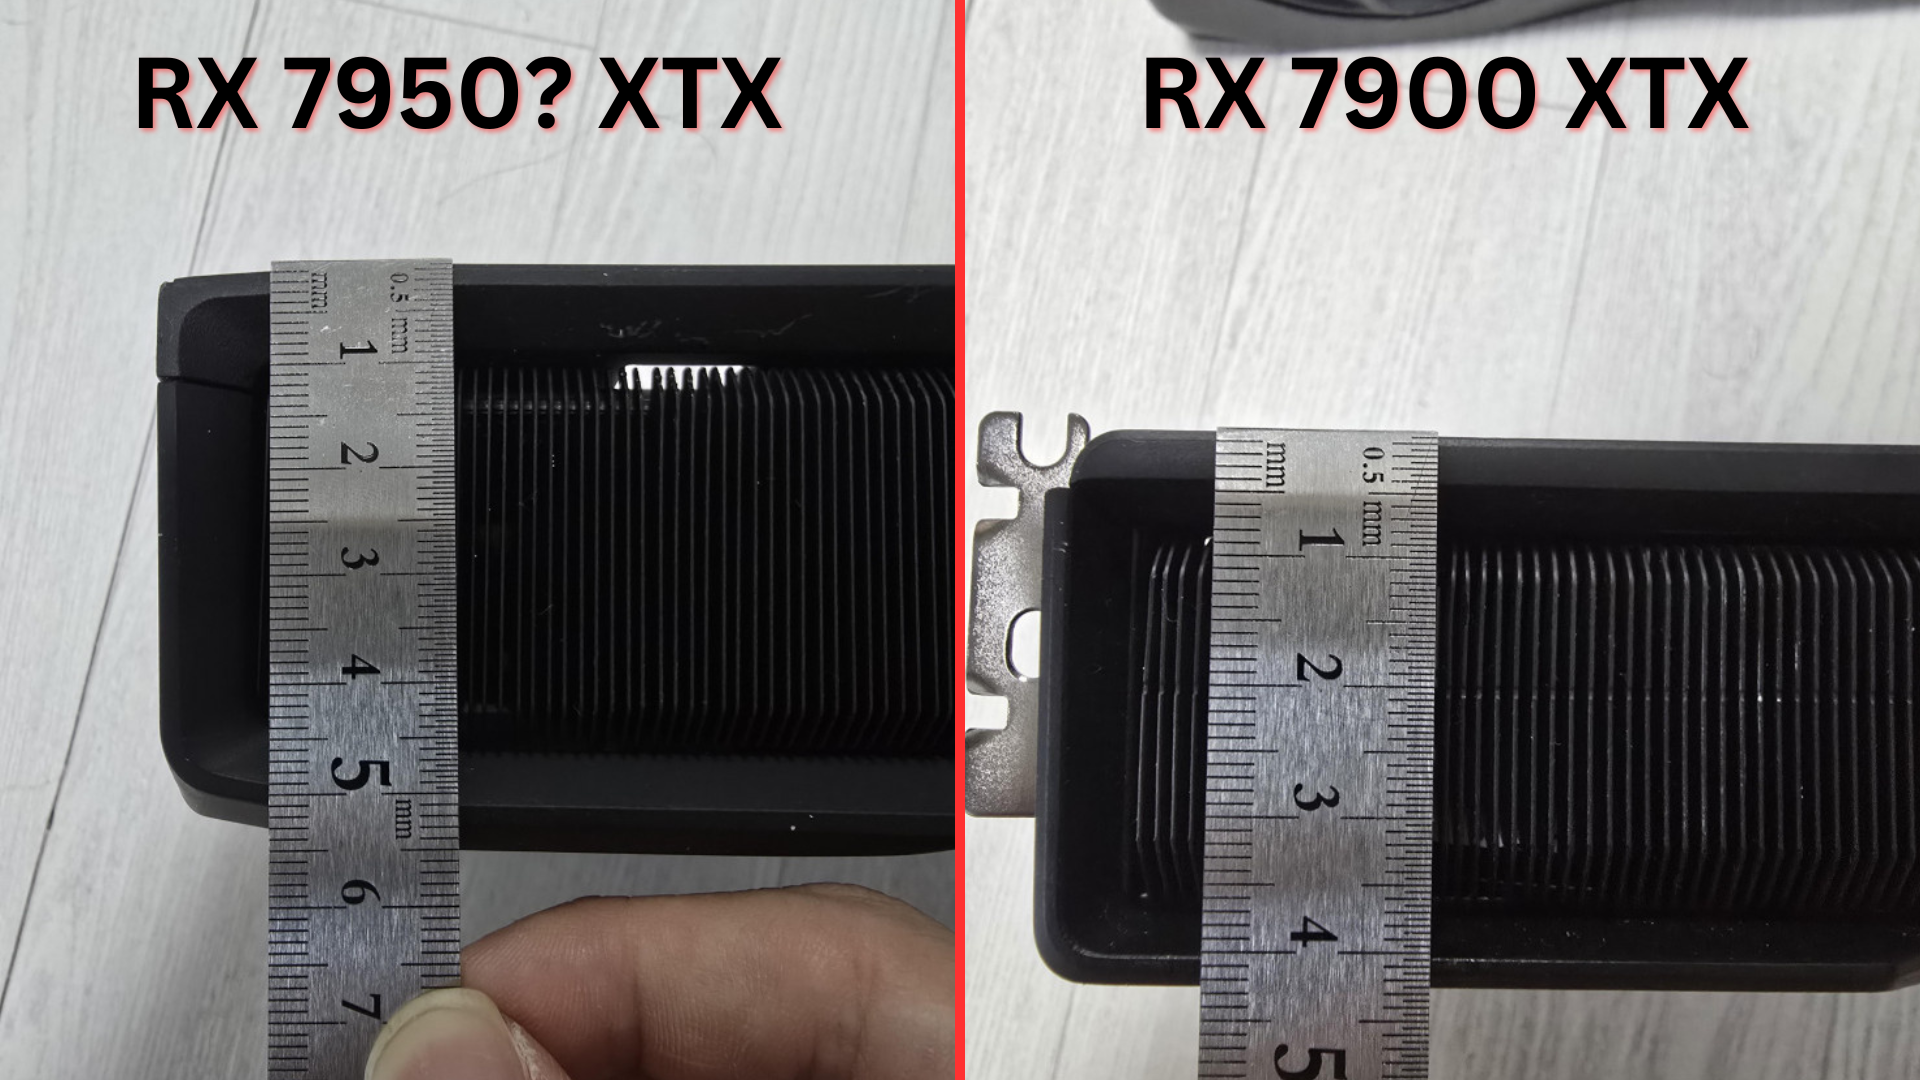
    The prototype measures almost 34 cm in length compared to 29 cm for the RX 7900 XTX, and is nearly 5.5 cm thick, taking up three slots with a triple-fan configuration. It has slightly different cutouts for LEDs as well, but it largely looks the same aesthetically.

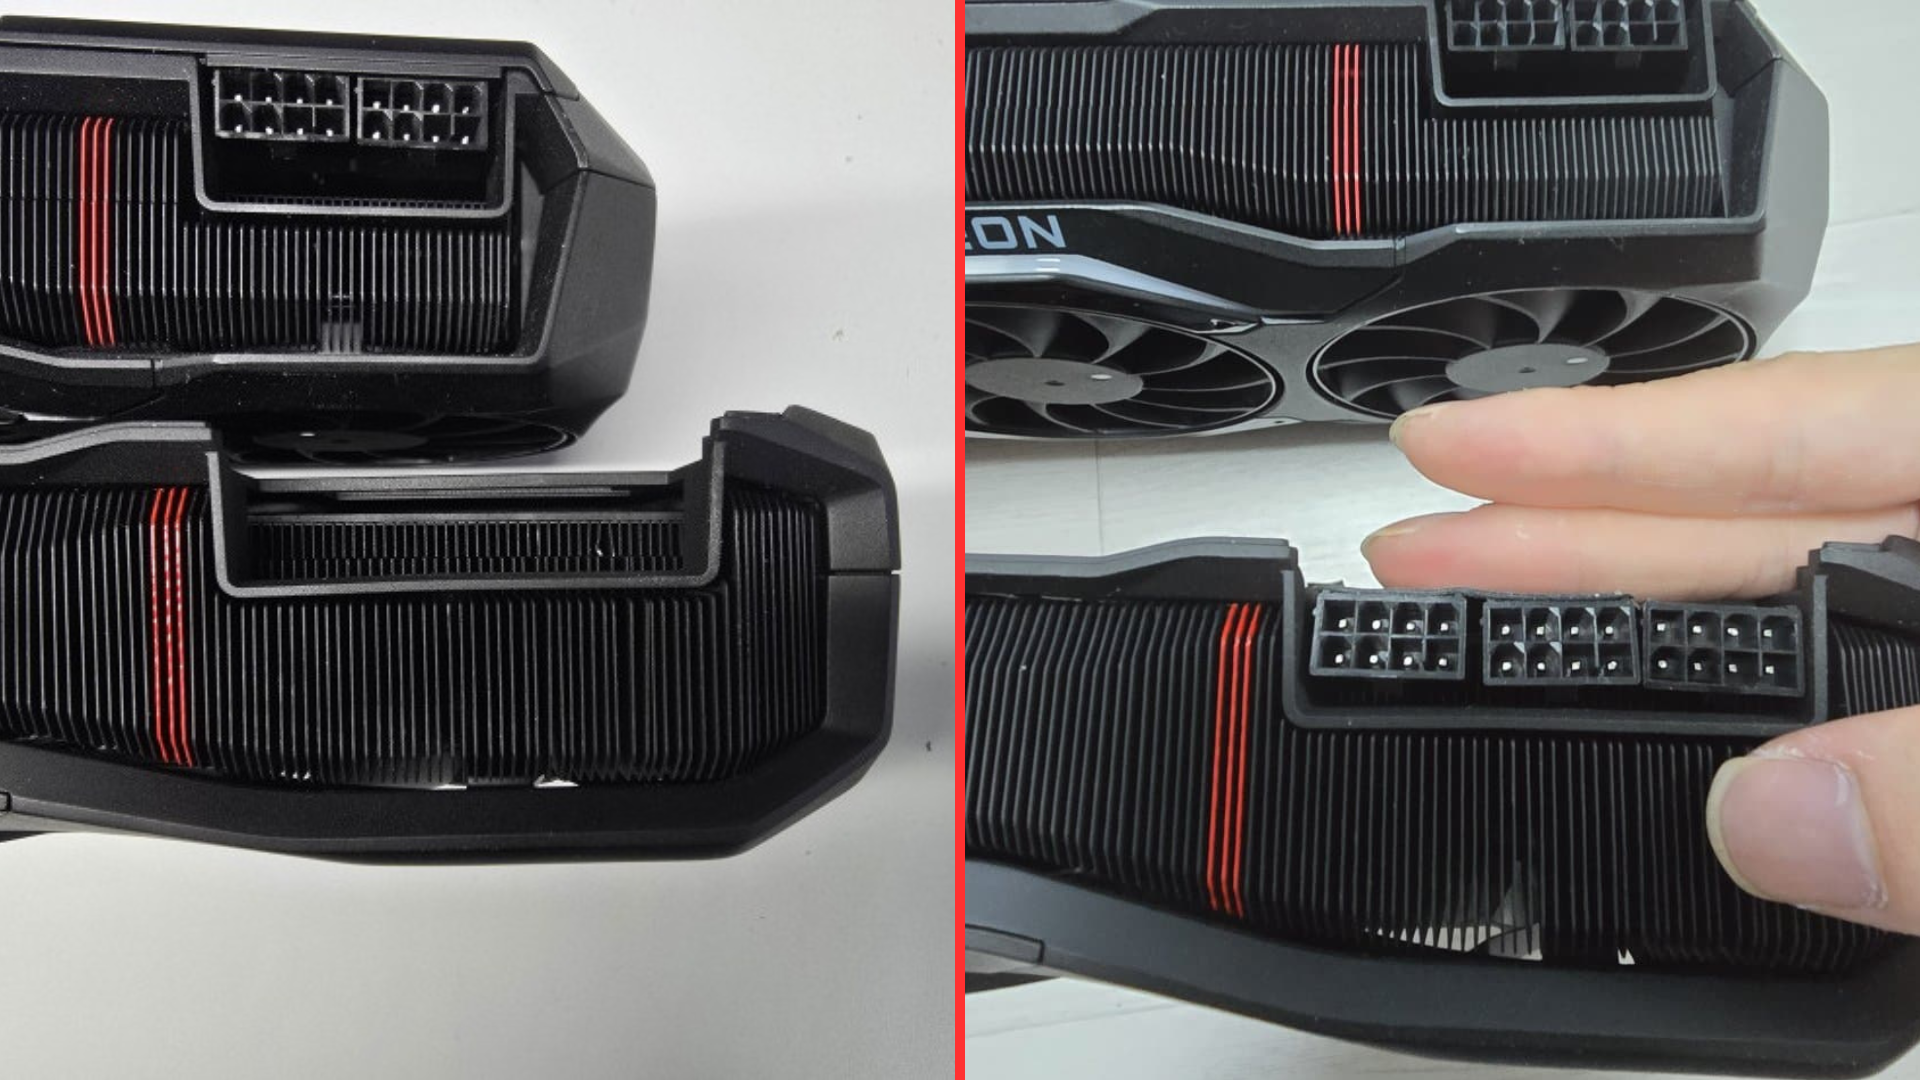
    The most eye-catching feature is its power design, with space carved out for three 8-pin connectors instead of the two seen on the 7900 XTX. This alone suggests a total board power well beyond 450W, making it more akin to Nvidia’s RTX 4090 in scale and power delivery. The heatsink itself has three painted red fins, indicating “RDNA 3,” and it’s a centimeter longer than the RX 7900 XTX reference edition.

    Image 1 of 4
    Mystery Radeon RDNA3 GPU cooler prototype
    (Image credit: FP32 on Quasarzone)
    Mystery Radeon RDNA3 GPU cooler prototype
    (Image credit: FP32 on Quasarzone)
    Mystery Radeon RDNA3 GPU cooler prototype
    (Image credit: FP32 on Quasarzone)
    Mystery Radeon RDNA3 GPU cooler prototype
    (Image credit: FP32 on Quasarzone)

    Once opened up, we see a copper baseplate and a heavy heatpipe array, clearly intended for handling higher thermals and demanding loads. The internal layout of this design is decidedly different than the 7900 XTX, further suggesting it was intended for a beefier config. Keep in mind that there was no PCB inside, so it couldn’t be connected to a PC for further testing. The cooler also lacks any I/O at the back, so we can’t (accurately) guesstimate what model this was going to house.

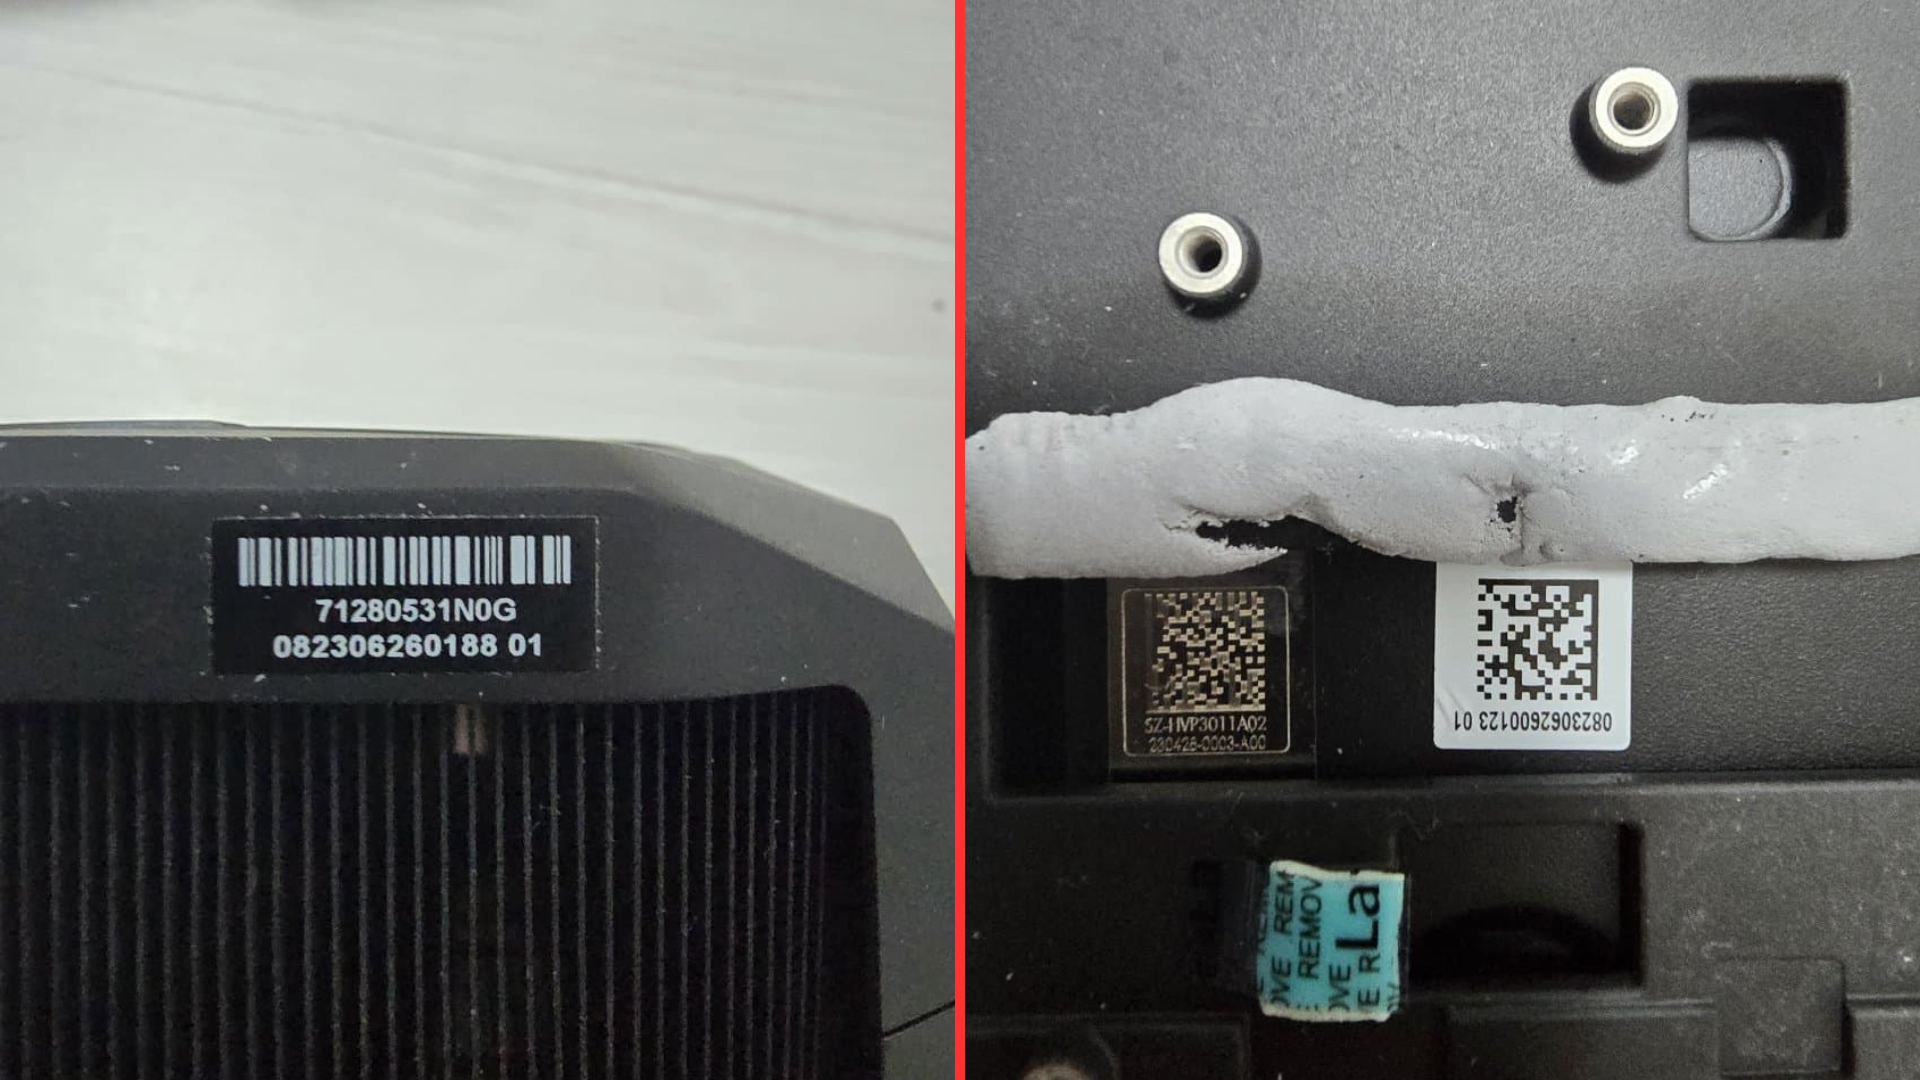
    There are a bunch of serial numbers stickered onto the shroud, but they don’t return any info when reverse-searched for; again, a dead end.

    Image 1 of 2
    Mystery Radeon RDNA3 GPU cooler prototype
    (Image credit: FP32 on Quasarzone)
    Mystery Radeon RDNA3 GPU cooler prototype
    (Image credit: FP32 on Quasarzone)

    Regardless, with the RX 7900 XTX already running a fully unlocked Navi 31 die at 96 Compute Units, this prototype may have been designed for much higher clock speeds or faster memory configurations. It’s equally possible that AMD experimented with a larger GPU variant that never made it past internal testing. Rumors of models like the RX 7950 XTX or RX 7990 XTX have circulated since 2022, but this is the first physical evidence pointing toward AMD’s exploration of a more aggressive “halo-tier” design for RDNA 3. Even a year later there was still speculation over Team Red’s unreleased cards that, in hindsight, never came to be.

    Such a GPU could’ve possibly bridged the huge gap between the RTX 80-class and 90-class cards with a middle-of-the-road option, even today. But the cooler itself is incompatible with retail designs due to its unique mounting pattern, leaving its original purpose a mystery. What’s clear is that AMD ultimately shifted focus away from the ultra-enthusiast segment, choosing to compete on efficiency and price-to-performance rather than raw power. This prototype is a reminder of what might have been if AMD had decided to go head-to-head with NVIDIA at the very top end.

    Stay On the Cutting Edge: Get the Tom’s Hardware Newsletter

    Get Tom’s Hardware’s best news and in-depth reviews, straight to your inbox.

    Hardware samples like this often surface years after launch, usually as engineering leftovers that make their way into secondary markets. The discovery of this prototype cooler, particularly with its triple-slot, triple 8-pin design, offers a rare look at AMD’s internal experiments and discarded plans, showing that even in the RDNA 3 era, a 4090-class Radeon wasn’t entirely off the table.


    Source: Latest from Tom’s Hardware.

  • OpenAI Seeks Additional Capital From Investors as Part of Its $40 Billion Round

    OpenAI Seeks Additional Capital From Investors as Part of Its $40 Billion Round

    July 22, 2025
    Technology

    capital from new and existing investors, two people familiar with the company’s plans tell WIRED. The fundraising effort is part of a $40 billion round announced in March. The round will reopen on Monday, July 28, according to one of the sources, who has direct knowledge of the fundraising effort.

    The $40 billion round announced earlier this year brought OpenAI’s valuation up to $300 billion, making it one of the most highly valued private startups in history. The round was led by Japanese investment conglomerate SoftBank, which committed to contributing 75 percent of the total funding. The initial tranche was $10 billion, with $7.5 billion from SoftBank and another $2.5 billion from a syndicate of other investors. OpenAI is currently raising the final $30 billion, with $22.5 from SoftBank and $7.5 from a syndicate of other investors.

    SoftBank’s commitment could be slashed to $10 billion if OpenAI does not restructure by the end of the year, WIRED confirmed.

    OpenAI has raised a total of $63.92 billion since the company was founded in 2015, according to PitchBook. Its backers include a wide range of institutional and individual investors, including Microsoft, Andreessen Horowitz, Sequoia Capital, Founders Fund, Thrive Capital, Coatue Management, Nvidia, and Reid Hoffman. Microsoft and OpenAI’s relationship is closely intertwined, with Microsoft providing OpenAI with massive amounts of cloud computing resources and OpenAI giving Microsoft exclusive access to its best models—though it was recently reported that their relationship has complications.

    OpenAI has also partnered with SoftBank, among others, on a four-year AI data center project in which upwards of $500 billion is projected to be invested. The Wall Street Journal reported earlier this week that the two entities have been at odds over certain aspects of the partnership, including where to build the data centers, and that OpenAI CEO Sam Altman has been making moves to sign deals for Stargate-aligned data centers without the Japanese firm.

    In a joint statement sent by Kristin Schwarz, global head of marketing and communications at SoftBank Investment Advisers, SoftBank and OpenAI said: “Stargate’s $500 billion commitment to build 10GW of new compute capacity across the United States is no longer a vision—it’s happening. We’re moving with urgency on site assessments and reimagining how data centers are designed to power advanced AI and make its benefits widely accessible. With projects already advancing in multiple states, we are moving at hyperscale and speed to deliver the AI infrastructure that will power the future and serve humanity.”

    OpenAI’s company structure has also been a point of contention and has rankled Elon Musk, who helped launch the research lab with a mission to safeguard humanity against artificial general intelligence, or AGI. After Musk left the company’s board in early 2018, OpenAI created a for-profit arm, in part to make it easier to fundraise. Last year Musk sued OpenAI for allegedly abandoning its original mission and said the company is “not just developing but is refining an AGI to maximize profits for Microsoft, rather than for the benefit of humanity.”

    In May, OpenAI proposed a new structure that keeps the nonprofit in control of the company and turns its current for-profit subsidiary into a public benefit corporation. This new nonprofit would hold shares in the PBC, and the PBC would in theory be designed to prioritize returns for shareholders while also pursuing projects with clear public benefits. SoftBank’s investment in OpenAI is contingent on this new structure being approved by attorneys general in California and in Delaware by early next year.

    Additional reporting by Kylie Robison and Zoë Schiffer.

    Update 7/22/25 3:10pm EST: This story has been updated to include a joint statement from OpenAI and SoftBank.


    Source: Wired.

  • Palmer Luckey considering entering laptop market with fully US-made model, wants to know if you'd spend 20% more for an American-made PC

    Palmer Luckey considering entering laptop market with fully US-made model, wants to know if you'd spend 20% more for an American-made PC

    July 22, 2025
    Hardware

    Palmer Luckey might have found his next area of focus: laptops.

    Luckey rose to prominence with the founding of Oculus in 2012. He sold the virtual reality company to Facebook in 2014, and after he was reportedly fired in 2017, he co-founded a military tech firm called Anduril Industries that has primarily focused on the development of autonomous systems. (Including surveillance tools as well as both aerial and underwater vehicles.)

    Anduril was followed by the announcement of a cryptocurrency-focused bank called Erebor earlier this month. (Luckey and several of Anduril’s co-founders, who also previously worked at Palantir Technologies, are unabashed in their obsession with “Lord of the Rings.” )But it seems Luckey might not be content with mil-tech and crypto.

    Would you buy a Made In America computer from Anduril for 20% more than Chinese-manufactured options from Apple?July 20, 2025

    Luckey previously asked the same question at the Reindustrialize Summit, a conference whose website said it was devoted to “convening the brightest and most motivated minds at the intersection of technology and manufacturing,” which shared a clip of Luckey discussing the subject, wherein he talks about the extensive research he has already done around building a PC in the U.S.:

    Here’s the moment where @PalmerLuckey interrupted @ashleevance at Reindustrialize to ask:”How many people in the audience would buy an American made computer if it was 20% more expensive?”The full clip is a great distillation of his thinking on the opportunity. https://t.co/aEvFdAxyBx pic.twitter.com/77qsvBJ52dJuly 20, 2025

    Luckey wouldn’t be the first to make a laptop in the U.S. (PCMag collected a list of domestic PCs, including laptops, in 2021.) But those products use components sourced from elsewhere; they’re assembled in the U.S. rather than manufactured there. That distinction matters, according to the Made in USA Standard published by the Federal Trade Commission. To quote:

    “For a product to be called Made in USA, or claimed to be of domestic origin without qualifications or limits on the claim, the product must be ‘all or virtually all’ made in the U.S. [which] means that the final assembly or processing of the product occurs in the United States, all significant processing that goes into the product occurs in the United States, and all or virtually all ingredients or components of the product are made and sourced in the United States. That is, the product should contain no — or negligible — foreign content.”

    So it would be interesting to see if Anduril could produce a laptop that meets the FTC’s standards, though it seems unlikely that sourcing exclusively American-made components would result in a mere 20% price bump, especially if performance is competitive with the recent MacBook models to which Luckey is comparing the company’s hypothetical wares.

    How much more would you be willing to pay for a laptop that was truly made in America? Let us know in the comments.

    Stay On the Cutting Edge: Get the Tom’s Hardware Newsletter

    Get Tom’s Hardware’s best news and in-depth reviews, straight to your inbox.

    Follow Tom’s Hardware on Google News to get our up-to-date news, analysis, and reviews in your feeds. Make sure to click the Follow button.


    Source: Latest from Tom’s Hardware.

  • How to Build Robust Networking Layers in Swift with OpenAPI

    How to Build Robust Networking Layers in Swift with OpenAPI

    July 22, 2025
    Software

    For many app developers, including me, writing the networking layer of an application is a familiar and tedious process. You write and test your first call and after that, it involves a repetitive cycle of tasks.

    This is how it would look in the case of Swift:

    1. You create a URLSession Instance.

    2. You create a URLRequest Object.

    3. You create the @Codable models to match the expected input and output from the server.

    You do the above steps for each API endpoint you have on your backend that your app uses. Not only is this process time-consuming and not challenging for developers, it’s also error prone.

    In the above case, if there was a minor change in the backend API – perhaps a renamed field or a new property – this would lead to the app potentially breaking. But you wouldn’t know this until you shipped it to QA or in a worse case, your consumer. This is where the OpenAPI Specification emerges as a modern, robust solution.

    In this tutorial, you’ll learn what OpenAPI is and how it can help make your development process better. After that, we’ll implement OpenAPI by creating a small SwiftUI app and using OpenAPI methodologies to interface with the JSONPlaceholder API. Let’s get started.

    Who is This Guide For?

    This guide is intended both for new developers looking for best practices and for experienced developers looking to implement or learn more about the OpenAPI Specification. Let’s get into it.

    Table of Contents

    • What is OpenAPI and Why Should You Care?

      • Benefits for Swift (iOS) Developers
    • A Practical Guide to Implementing This Solution

      • Step 1: Create a good openapi.yaml file (the specification)

      • Step 2: Set up your project

      • Step 3: Write a wrapper

      • Step 4: Call the wrapper and display the data

    • Potential Pitfalls

      • Verbose or ugly generated code

      • Large Specs and Performance Issues

      • Unsupported Spec Features

    • Conclusion: Embrace Spec-Driven Development

    What is OpenAPI and Why Should You Care?

    At its core, the OpenAPI Specification provides a standard, language-agnostic interface for describing RESTful APIs. This specification, once populated, allows both humans and computers to discover and understand the capabilities of a service without needing to access the source code or the network requests.

    The power of OpenAPI is that it acts as a formal contract between different parts of the system. This contract helps both frontend and backend programmers by removing ambiguity during design process. This also has added benefit of using code generators to generate boiler-plate code both on backend and on the client ( which we will also discuss today ).

    Traditionally when you want to create a new API in a team, either the PM, the frontend engineer, or the backend engineer takes it upon themselves to request it. Then the backend team builds it and documents it. This in turn is used by the front end team to use the API.

    Some Requester → Backend Team → Documentation → Frontend Team

    If you’re using OpenAPI, when someone makes a request for a new API, it is formalized into a specification after deliberations with both the frontend and the backend team. This then serves as the source of truth and is used to generate the backend and the frontend code without as much interdependence.

    Some Requester → All Teams → Specification → All Teams.

    This not only streamlines the process of adding new APIs, but provides a definitive source of truth for each endpoint. This also makes it so that frontend engineers and backend engineers are not misaligned about a provided parameter in the result being an Int or a String and so on. It’s all in the Spec.

    Benefits for Swift (iOS) Developers

    Adopting OpenAPI and swift-openapi-generator brings a host of tangible benefits to the Swift/App development process. It transforms how applications interact with web services in a few key ways.

    Reduced Development Time and Cost

    The most immediate improvement you will see is the significant reduction in boilerplate code you have to write. The generator automates the creation of what is called boilerplate code or ceremonial code. This is the repetitive logic for network requests, response handling, and data model definitions.

    By delegating this work, developers can work on the core features of the application which leads to faster and more interesting development cycles.

    Compile Time Type Safety

    This has been a major improvement for me personally. Instead of relying on the “strongly” typed keys for JSON parsing, we now work with strongly typed models. The generator creates native Swift struct and enum types directly from the schemas defined in the OpenAPI document. This brings the power of a strongly-typed system to the networking and parsing layer.

    For example, if the return value of an API is made optional, instead of crashing at runtime, we will fail to compile at build time. This forces us to address this issue right away.

    Improved Collaboration and Interoperability

    This makes sure that all the developers are on the same page with regard to a given endpoint. And since this specification is language agnostic, it will serve as a universal language for all teams involved in the project – mobile, web and backend.

    Other Tooling

    Once you have a specification, you can use that to power a wide variety of tools. You can generate interactive documentation, create mock servers for frontend development, and run automated tests.

    Alright hopefully you’re sold – so now how do you implement this into your project?

    A Practical Guide to Implementing This Solution

    We’ll now take a look at a practical example so you can understand how you can implement this in a project. This involves:

    • Creating an openapi.yaml file to describe the API specification.

    • Configuring and integrating swift-openapi-generator into a SwiftUI application.

    • Prototyping an app that fetches and displays a list of posts from the https://jsonplaceholder.typicode.com/

    To follow along, you will need Xcode installed and a basic understanding of Swift programming and SwiftUI for App development.

    Step 1: Create a good openapi.yaml file (the specification)

    The quality of a specification is really important because it directly determines the quality of the code produced by swift-openapi-generator. If you don’t have a good specification, you might run into several issues that developers often complain about, like confusing and long method names.

    For example, it might generate something like get_all_my_meal_recipes_hyphen_detailed. This might happen because the generator is forced to create a new name based on the API path if the identifier is not provided in the spec. So, instead of dealing with these issues one after the other, we will create a good clear specification to start with.

    Since we’re using the jsonplaceholder as our backend server, we are limited by what tweaks we can make – but it is a fantastic project that lets us mimic a backend server.

    In general, an OpenAPI.yaml file contains:

    1. OpenAPI Info and servers – This will provide the metadata about the API like the OpenAPI version, which server to point to for calls, and so on.

    2. Paths – This will provide the available endpoints. In our case, it can contain /posts as one of them. We also will have to mention the kind of endpoint (get, post, put, and so on)

    3. OperationID – This field instructs the generator to create a clear method with this name.

    4. Responses – This defines the possible outcomes of an API call. We will specify the structure of a successful 200 OK response or any other errors here.

    5. Components / Schemas – This defines all the reusable components and data models. If we have a Post schema definer here, the generator will use this to create a Post struct in Swift to match this.

    Keeping in mind all these elements, I compiled a yaml file for us to use for this tutorial:

    # openapi.yaml openapi: "3.0.3" info: title: "JSONPlaceholder API" version: "1.0.0" servers: - url: "https://jsonplaceholder.typicode.com" paths: /posts: get: summary: "Get all posts" operationId: "getPosts" responses: "200": description: "A list of posts" content: application/json: schema: type: array items: $ref: "#/components/schemas/Post" components: schemas: Post: type: object required: - userId - id - title - body properties: userId: type: integer id: type: integer title: type: string body: type: string 

    The first line here, openapi: “3.0.3”, just tells the generators and parsers that we are using version 3.0.3.

    Next, we have some more metadata – the name and version of the API. We also have the server we are calling with our APIs.

    After defining this metadata, we now define our endpoints. For the sake of this example, let’s assume that we only have one endpoint to call to get posts. We represent this by saying /posts under paths. We then specify which kind it is by specifying get:.

    We give a short description of what it does in the summary and then specify an operationId which is what we this function will be called in our generated code. We also specify exactly what structure the response will have, that is, a JSON of an array of Posts.

    We then list any components we have across our APIs like the Post. Note that we are using the Post schema in the return response structure before we define it further down. The schemas in components will determine the Model structs we will generate using this yaml file.

    Step 2: Set up your project

    Create a new SwiftUI project. For the purpose of this tutorial, we’ll use an iOS app – but you can do this with any app. Select Swift as the language and SwiftUI for the interface.

    App Creation Screen

    Basic SwiftUI App after it's created

    Add the openapi.yaml file we just created to this project. (You can also create this file in Xcode and copy, paste from the script above.)

    Adding the openapi.yaml file to our project

    Now, add the following swift packages to the project. (Note: Please read the entire section about adding packages before you proceed.)

    1. Swift OpenAPI Generator – https://github.com/apple/swift-openapi-generator – The Core Generator Plugin.

      Adding Swift OpenAPI Generator to our Project

      Making sure that no targets are selected for the OpenAPIGenerator

    2. Swift OpenAPI Runtime – https://github.com/apple/swift-openapi-runtime – This contains the common types and protocols used by the code generated by the generator plugin.

      Adding OpenAPIRuntime to our project

    3. Swift OpenAPI URLSession – https://github.com/apple/swift-openapi-urlsession – This is a transport layer that allows the generated code to use the Apple URLSession to make network requests.

      Adding OpenAPIURLSession to our Project

    One major caveat to note here when adding these packages is that The Swift OpenAPI Generator should not be added to your project target. This is because we’re only using this to generate the code, but we’re not using it in the app.

    If you get this error: swift-openapi-generator/Sources/_OpenAPIGeneratorCore/PlatformChecks.swift:21:5 _OpenAPIGeneratorCore is only to be used by swift-openapi-generator itself—your target should not link this library or the command line tool directly. – then you made this mistake.

    The easiest way to fix this is removing the package and adding it again. Or you can go to Project → Target → Build Phases → Link Binary with Libraries → Remove Swift OpenAPI Generator.

    Where to check if you encounter that error

    Now that we added these generator and runtime plugins, we need to give the generator some instructions on what to generate. You can do this with an openapi-generator-config.yaml file. For our project, use the following file. It’s really simple:

    generate: - types - client 

    This tells our generator to generate the types – the swift structs, enums, and so on from the schema section of the file, and the client – the main class which interacts with the networking logic.

    openapi-generator-config.yaml file

    Save this into an openapi-generator-config.yaml file as shown.

    And finally, we want the generator to run whenever we want to build this application/target. We can specify this in the Build Phases tab of the target. Under the “ Target → Build Phases → Run Build Tool Plug-ins” , add the OpenAPIGenerator Plugin.

    Adding the generator in the build phase

    The first time the project is built after setting this, Xcode will display a security dialog. This will let us “Trust and Enable” for this plugin. It’s a one time confirmation that gives this plugin the permission required to run during the build process.

    Trust and Enable security dialog for the generator

    As soon as you build the second time after giving these permissions, you will generate the files. You might not see any changes in the Xcode window itself. But if you’re curious to see the result, go to this folder.

    DerivedData → <ProjectName>*identifier → Build → intermediates.noindex → BuildToolPluginIntermediates → <TargetName>.output → <TargetName> → OpenAPIGenerator → GeneratedSources

    More on derived data folder here: https://gayeugur.medium.com/derived-data-2e9468c6da9b if you’re curious.

    Keep in mind that this location might vary based on Xcode version, OpenAPI version, and your project settings. But you don’t need to worry about the file location.

    You will see three files called Client.swift, Types.swift, and Server.swift.

    Generated Files

    These are the files that the our generator created and populated with the types and functions we need.

    In the next section, we discuss how to use these files to make calls to the server.

    Step 3: Write a wrapper

    While it’s certainly possible to make the calls to server using just the generated code (Client) type throughout our application, a more maintainable approach is to use a wrapper around these types. This will provide a stable, clean interface for the rest our our app to use, and it decouples feature code from the generated code.

    I can hear you thinking: “Wait a second. Isn’t the entire purpose of generating this code to avoid this boilerplate abstraction?”

    While it adds some abstraction on top of the generated code, it’s valuable to have this for number of reasons. Here are but a few of them:

    1. Better naming. The generated Post struct right now will be called Components.Schemas.Post.

    2. If you ever want to move away from the generator, an abstraction is really helpful.

    3. If you want to Mock this server call, you can do this via the abstraction.

    4. UI Optimization. You might want to flatten the structure of a model to reduce the number of computed variables in there, and so on.

    So, we want to wrap this around a file called WebService.swift:

    // WebService.swift import Foundation import OpenAPIURLSession // A clean, app-specific Post model. // This decouples views from the generated types. struct AppPost: Identifiable, Codable { let id: Int let title: String let body: String } class WebService { private let client: Client init() { // The server URL and transport are from the generated code. // `Servers.Server1.url()` corresponds to the first URL in the `servers` array of the spec. self.client = Client( serverURL: try! Servers.Server1.url(), transport: URLSessionTransport() ) } func getPosts() async throws -> [AppPost] { // Call the generated method, which was named using `operationId`. let response = try await client.getPosts(.init()) // The generated response is a type-safe enum covering all documented status codes. switch response { case.ok(let okResponse): // The body is also a type-safe enum for different content types. switch okResponse.body { case.json(let posts): // Map the generated `Components.Schemas.Post` to our clean `AppPost` model. return posts.map { post in AppPost(id: post.id, title: post.title, body: post.body) } } // The generator forces the handling of other documented responses. // Our simple spec only has a 200, so any other response is undocumented. case.undocumented(statusCode: let statusCode, _): throw URLError(.badServerResponse, userInfo: ["statusCode": statusCode]) } } } 

    Let’s go through this file to understand what we’re doing.

    First, we import OpenAPIUrlSession along with Foundation. This allows us to call the server, get a response and parse that response.

    Next, we define the new AppPost struct. This is meant to be the representation of a Post in the App. In the generated Types.Swift file, we have the generated Post structure. This is defined as:

    /// - Remark: Generated from `#/components/schemas/Post`. internal struct Post: Codable, Hashable, Sendable { /// - Remark: Generated from `#/components/schemas/Post/userId`. internal var userId: Swift.Int /// - Remark: Generated from `#/components/schemas/Post/id`. internal var id: Swift.Int /// - Remark: Generated from `#/components/schemas/Post/title`. internal var title: Swift.String /// - Remark: Generated from `#/components/schemas/Post/body`. internal var body: Swift.String /// Creates a new `Post`. /// /// - Parameters: /// - userId: /// - id: /// - title: /// - body: internal init( userId: Swift.Int, id: Swift.Int, title: Swift.String, body: Swift.String ) { self.userId = userId self.id = id self.title = title self.body = body } internal enum CodingKeys: String, CodingKey { case userId case id case title case body } } 

    As you can see, our AppPost struct is different from this generated type. We omit the userId since we do not care about it (at least for now).

    Back to the WebService class, we see a client attribute. This is a generated type variable that will let us interact with the servers. In the initializer of the WebService class, we create a new Client using the first server URL we specified in the schema and use the URLSessionTransport object for making these calls.

    We then define our methods. In this case, our getPosts() function which returns [AppPost] array.

    let response = try await client.getPosts(.init()) will call the function getPosts() on the Client object. The Client.getPosts() function here takes in an input struct called Operations.getPosts.Input which is initialized by the .init() passed here.

    This generated response is a type-safe enum covering all documented codes. (Currently only 200 in our yaml file). So, we use a simple switch to look at both these cases and further use more switch statements to get the proper response. You can see how much easier this is than to parse the response manually.

    Once we get the Components.Schemas.Post response, we map and convert it into [AppPost] array and return it.

    Now, let’s use this wrapper to display data in our app.

    Step 4: Call the wrapper and display the data

    We’re at the final step now. We’ll use the wrapper we created to display the fetched posts. We’ll also use a state variable to store our AppPost array in our ContentView view. We’ll then call getPosts() when the view is first displayed to the user.

    // ContentView.swift import SwiftUI struct ContentView: View { @State private var posts: [AppPost] = [] @State private var errorMessage: String? private let webService = WebService() var body: some View { NavigationStack { List(posts) { post in VStack(alignment:.leading, spacing: 8) { Text(post.title) .font(.headline) Text(post.body) .font(.subheadline) .foregroundColor(.secondary) } .padding(.vertical, 4) } .navigationTitle("Posts") .task { await loadPosts() } .overlay { if let errorMessage { ContentUnavailableView("Error", systemImage: "xmark.octagon", description: Text(errorMessage)) } else if posts.isEmpty { ProgressView() } } } } func loadPosts() async { self.errorMessage = nil do { self.posts = try await webService.getPosts() } catch { self.errorMessage = error.localizedDescription } } } #Preview { ContentView() } 

    You can see the dummy posts in the Preview. As you can see, all we had to do was call the webService.getPosts() to populate the variable.

    Simulator Run of the app showing the fetched posts

    You might be thinking that this is a lot of setup for a simple struct like Post for which we had to create a wrapper called AppPost anyway. But if you had ten types like this and twenty endpoints to call? You wouldn’t have to deal with a lot of repetitive, error-prone code.

    Potential Pitfalls

    Unfortunately, no process is perfect. You might still face a lot of issues with generated code and this method. I’ve listed some of them here and how to deal with them.

    Verbose or ugly generated code

    If you have very verbose or ugly generated code, the problem is almost always the missing operationId for an API path. If you don’t specify one, the generator must create a name from the path and the HTTP method with results in long unwieldy names. Adding a clear operationId will mitigate this issue.

    Large Specs and Performance Issues

    If you have a very large Spec file, generating a client for this entire specification can significantly increase the compile time. It can also result in absolutely massive Types.swift and Client.swift files.

    There is a filter option in the openapi-generator-config.yaml file that will allow the generator to include only parts of the spec that are relevant to the application to improve build times and so on. But if you want everything in an API that has hundreds of endpoints, the only way to reduce compile times is to avoid regenerating this every time and decouple this step from the regular build process.

    Unsupported Spec Features

    While the swift package, swift-openapi-generator, is robust, it does not support all the features included in the specification. I had issues with some features of the newer spec version ( 3.1.1 and had to downgrade to 3.0.3 to make it work well ).

    There are also known issues like lack of support for certain types of recursive schemas. Sometimes, the generator errors out and fails and some other times, it generates incomplete types – which can result in a few hours of debugging (I speak from experience).

    In any case, knowing the limits of this generator can be helpful in avoiding issues it might cause. Also keep in mind that it is always getting better thanks to its open source nature.

    Conclusion: Embrace Spec-Driven Development

    In this guide, you navigated the journey of adopting swift-openapi-generator – from understanding the power of API contracts to building a functional SwiftUI app. You also learned about the real life challenges of this process. While there is an initial learning curve, the benefits of this approach are profound.

    The core tenet of this approach is to foster more disciplined and more robust method for building applications. By making the OpenAPI document the single source of truth, you make sure that both the frontend and backend are perfectly in sync in perpetuity.

    Using this approach also results in more type-safe, maintainable code. The result is less time spent on writing boilerplate and debugging random integration errors and more time spent creating the app itself.

    For developers ready to explore further, please checkout the official swift-openapi-generator repository on Github here: https://github.com/apple/swift-openapi-generator.

    You can follow me on GitHub and Hashnode for my other posts and projects.


    Source: freeCodeCamp Programming Tutorials: Python, JavaScript, Git & More.
  • Six Activist Trolls Tromp Through a California Woodland to ‘Save the Humans’

    Six Activist Trolls Tromp Through a California Woodland to ‘Save the Humans’

    July 22, 2025
    Design

    Six Activist Trolls Tromp Through a California Woodland to ‘Save the Humans’

    As visitors wander through a mile-stretch of Filoli’s Natural Lands this summer, they’ll encounter a group of eager wooden characters ready to share their wisdom. Trolls: Save the Humans is a playful, yet urgent exhibition by Danish artist Thomas Dambo (previously), who’s known for creating enormous fairytale characters from reclaimed wood.

    At Filoli, Dambo has installed six creatures, each with a distinct personality and agenda. There’s the innovative “Kamma Can,” a “treasure troll” that enjoys teaching people to turn their leftover wrappers and disposable containers into vibrant creations. “Ibbi Pip: The Birdhouse Troll” is similarly concerned with transforming the environment by installing avian homes, while “Sofus Lotufs: The Listening Troll” directs our attention to the forest floor and asks us to be mindful of the changes happening all around.

    a giant wood troll with its ear to the ground
    “Sofus Lotus: The Listening Troll”

    “I’m so happy my Trolls get to spend some time amongst the giant redwoods at Filoli,” Dambo says. “I spent a day hiking in the forest, and it is a magical place where I know my Trolls will feel at home.”

    Staggering in stature and inviting in presence, the characters are activists at their core and passionate about teaching sustainability. Like much of the artist’s practice, this exhibition utilizes the charm and wonder of fairytales to convey critical messages about the climate crisis and human behavior.

    Trolls continues through November 10 in Woodside, California. Follow Dambo’s passionate personalities on Instagram.

    a close up of a wooden troll
    “Ronja Redeye: The Speaker Troll”
    a giant wood troll with its ear to the ground
    Detail of “Sofus Lotus: The Listening Troll”
    a giant wood troll placing birdhouses on trees
    “Ibbi Pip: The Birdhouse Troll”
    a giant wood troll seated in a woodland
    “Basse Buller: The Painting Troll”
    a giant wood troll with its ear to the ground
    “Sofus Lotus: The Listening Troll”

    Do stories and artists like this matter to you? Become a Colossal Member today and support independent arts publishing for as little as $7 per month. The article Six Activist Trolls Tromp Through a California Woodland to ‘Save the Humans’ appeared first on Colossal.


    Source: Colossal.

  • Anzalone wants to retire a Lion but talks 'weird'

    July 22, 2025
    Sports

    ALLEN PARK, Mich. — Lions linebacker Alex Anzalone wants to finish his playing career in Detroit but admits to being “disappointed” in how his contract negotiations have gone so far this offseason.

    Anzalone, who is dealing with a hamstring injury, has yet to practice but was spotted at the Meijer Performance Center roaming the sidelines on Day 3 of training camp in team-issued gear.

    “I’m disappointed, I’ll just say that. I’m disappointed,” Anzalone said Tuesday of his contract negotiation.

    Although the 30-year-old has expressed his desire to reach a new contract long ago as he enters the final year of his current three-year, $18.75 million contract that was signed in 2023, he doesn’t anticipate sitting out any regular season games due to those concerns.

    However, he finds the situation strange due to their history together over the past four seasons where he was a key piece of the team’s rebuild to relevancy.

    “For sure. This is a weird situation and wasn’t on my end or my agent’s end,” Anzalone said while speaking to reporters for the first time.

    Anzalone wouldn’t go into full detail about any ongoing discussions but does feel he’s underpaid relative to other linebackers in the NFL. In 2024, he started in all 10 appearances, while logging the team’s fourth-most tackles (63) — seven for loss.

    “I want to retire a Lion. I want that opportunity,” Anzalone said “That’s how I feel.”

    On Sunday, Lions head coach Dan Campbell said he refused to believe that Anzalone not practicing is a part of a “hold-in” situation due to contractual issues. And there is a chance that Anzalone could potentially return to the practice field without a new deal, but his intentions are clear as he looks to help Detroit win a Super Bowl.

    “I put so much into my time here and being a four-time captain and my teammates and the city and just living here,” Anzalone said. “You could list all the reasons but it’s just important to me. I feel like I love this place, and I want that opportunity.”

    Lions All-Pro safety Kerby Joseph is a big fan of Anzalone, and his role on defense, and says he’s supportive of “whatever he feels he needs to do is best and that’s just him.”


    Source: www.espn.com – TOP.

  • VPS vs PaaS: How to Choose a Hosting Solution

    VPS vs PaaS: How to Choose a Hosting Solution

    July 22, 2025
    Software

    If you’ve ever stared at a dozen hosting plans, not sure which one to choose, you’re not alone. Hosting isn’t one-size-fits-all, and knowing the difference between a VPS (Virtual Private Server) and a PaaS (Platform as a Service) can help you pick something that works for your project.

    Let’s break them down clearly. We’ll go through VPS and PaaS in detail in terms of scaling, pricing, control, and so on. Each handles hosting very differently, and by the end of this guide, you’ll know exactly which solution fits your workflow better.

    • What is a VPS?

    • What is a PaaS?

    • Control and Customisation

    • Setup and Deployment

    • Scaling

    • Maintenance and Updates

    • Performance

    • Security

    • Pricing

    • When to Use Each

    • Summary

    What is a VPS?

    VPS stands for Virtual Private Server. Think of it as your own slice of a physical server.

    Unlike shared hosting, where you compete for resources, a VPS gives you isolated computing power, dedicated RAM, CPU, and storage that’s all yours.

    It acts like a mini datacenter. You gain root access, allowing you to install any OS (such as Ubuntu or CentOS), run custom applications, set up cron jobs, configure firewall rules, and essentially shape the environment as you see fit. It’s flexible, affordable, and powerful, and ideal for developers who want control without the complexity of managing bare-metal hardware.

    What is a PaaS?

    PaaS stands for Platform as a Service. It’s a cloud-based environment that lets you build, deploy, and scale applications without worrying about infrastructure.

    Instead of provisioning servers or managing software stacks, you simply write your code, connect your Git repository, and hit deploy. The platform takes care of everything from building your app, routing traffic, provisioning SSL, scaling services, and monitoring health. It’s DevOps on autopilot.

    PaaS solutions are built for speed and simplicity. They support modern languages and frameworks out of the box and offer smart features like auto-scaling, built-in CI/CD, and usage-based pricing.

    Now let’s look at the main differences between the two options so you can decide which is best for your use case.

    Control and Customisation

    A VPS gives you full control. It’s your server, your rules.

    You get root access, pick your OS, install whatever software you need, and tweak system settings to your liking. VPS solutions makes this easy by letting you deploy clean server images quickly like Ubuntu, Debian, Redhat or whatever suits you. Then it’s all in your hands.

    PaaS, on the other hand, limits a bit of that flexibility in exchange for convenience. PaaS abstracts the system layer away completely and often comes with support which is handy if you need help.

    You write code, push to a Git repo, and it takes care of the rest. It supports popular languages and frameworks, but if you need a very specific runtime or library, you might hit a wall.

    If you like being in control, VPS wins here. If you’d rather avoid infrastructure altogether, PaaS is your solution.

    Setup and Deployment

    Getting a VPS up and running takes more effort. You’ll start by provisioning a server, then SSH in to install packages, configure firewalls, set up your web server, and deploy your code manually or via tools like Docker.

    With PaaS, setup is nearly instant. You connect your GitHub or GitLab account, select your repo, and click deploy. It handles building, routing, SSL certificates, and launching the app, all within minutes. No SSH, no terminal commands, no surprises.

    So if you want fast and repeatable deployments, PaaS is the smoother ride. If you’re okay spending more time upfront to craft your ideal setup, VPS gives you the flexibility.

    Scaling

    Scaling is one of the biggest advantages of PaaS. When your app traffic increases, it can spin up more containers or instances automatically.

    You don’t have to predict resource needs ahead of time. Your app scales with demand and scales back down to save money when things quiet down.

    With a VPS, scaling is more manual. You have to monitor usage and upgrade your server or configure load balancers yourself. Some developers enjoy this level of control, especially when optimising resource use. But it can be a headache during unexpected traffic spikes.

    If your app is likely to grow or experience unpredictable load, PaaS gives you peace of mind. If your traffic is steady and predictable, VPS can handle it just fine, especially if you’re comfortable managing the growth yourself.

    Maintenance and Updates

    VPS means you’re in charge of everything under the hood. That includes system updates, security patches, disk usage, and log rotation. You also need to manage backups, monitoring, and anything else that keeps your app healthy and online.

    PaaS removes that burden. The platform takes care of OS-level updates, security patches, and even restarts or auto-heals when something goes wrong. You get built-in monitoring and automatic backups, and logs are available right from the dashboard.

    If maintenance isn’t your strong suit, or just not how you want to spend your valuable time, PaaS clearly comes out ahead.

    Performance

    With a VPS, you get guaranteed resources. They offers dedicated CPU cores and RAM that only your apps use. You can fine-tune performance at every level, from Nginx config files to memory usage. But I would recommend that you read the provider’s fine print and service terms as dedicated resources are not always fully dedicated.

    PaaS solutions often run apps in shared or containerised environments. They manage performance for you and isolate workloads, but you might not have the same raw consistency as with a dedicated VPS, especially under heavy compute loads.

    For apps that demand consistent high performance, like an online streaming service, a VPS is often the better choice. For most typical web apps, PaaS delivers more than enough speed and stability.

    Security

    In a VPS, security is your responsibility. That includes setting up firewalls, securing SSH access, managing user roles, and keeping the OS up to date. VPS gives you the tools, but it’s up to you to use them correctly.

    PaaS handles most security concerns automatically, including DDoS protection. It provides HTTPS out of the box, isolates apps from each other, and keeps the platform patched and hardened. While you’re still responsible for securing your app code, you don’t have to worry about the infrastructure.

    If security isn’t your strong point, or you want to reduce risk, PaaS adds a safety net. For experienced sysadmins, VPS offers the flexibility to build your own defenses.

    Pricing

    VPS pricing may appear more affordable at first glance. A VPS server with 4 GB RAM and 80 GB SSD might only set you back $10-15 per month. But that price is fixed, whether your app is serving ten users or ten thousand. And when you outgrow that plan, scaling means resizing the server or juggling additional machines.

    PaaS platforms take a different approach. Instead of paying for fixed resources you may or may not use, you pay for what you actually consume. If your app gets minimal traffic, your costs stay low. But if usage spikes, PaaS scales your resources to match, without downtime or manual effort. You’re billed based on activity, not guesswork.

    This makes PaaS a better long-term deal for most modern apps. You’re not locked into static hardware. You don’t have to overpay just to be “safe.” And as your app scales, your infrastructure scales with it automatically.

    But keep in mind that since PaaS platforms scale automatically based on demand, a sudden spike in traffic can lead to unexpectedly high costs. To avoid surprise bills, make sure to set up pricing alerts and usage thresholds. Most PaaS providers offer these features to help you stay in control of your budget.

    When to Use Each

    Use a VPS if you need complete control, want to host multiple apps on one server, or have special requirements around software, performance, or system-level configuration.

    Hetzner is a great choice when you want a solid server at a good price and are comfortable managing it yourself. It offers powerful virtual servers with full root access, making it a favorite among developers who want total control. If you’re comfortable managing your own infrastructure, Hetzner gives you the tools and flexibility to build exactly what you need.

    Choose PaaS if you want to move fast, avoid infrastructure headaches, and focus purely on coding. PaaS lets you deploy and scale apps with minimal effort, which makes it ideal for teams that want to spend more time building and growing their business than managing.

    Sevalla is a modern PaaS built for speed and simplicity. It handles everything from deployments to scaling, so you can focus entirely on writing code. With smart usage-based pricing and built-in automation, Sevalla is ideal for developers who want to move fast without managing servers or infrastructure.

    Summary

    There’s no one-size-fits-all answer when choosing between VPS and PaaS. It depends on your priorities, whether you care more about control or convenience, price or speed, flexibility or simplicity.

    A VPS gives you a clean slate and full power under the hood. It’s ideal for experienced developers and sysadmins who want to build their environment from the ground up.

    A PaaS offering gives you the tools to deploy fast, scale effortlessly, and skip the DevOps. It’s perfect if you’d rather write code than manage servers.

    Hope you enjoyed this article. Connect with me on LinkedIn or visit my website.


    Source: freeCodeCamp Programming Tutorials: Python, JavaScript, Git & More.
  • Helpful Built-in Functions in C++ that All Devs Should Know

    Helpful Built-in Functions in C++ that All Devs Should Know

    July 22, 2025
    Software

    Built-in functions in C++ are those functions that are part of the C++ standard libraries. These functions are designed to provide common and essential functionality that is often required in programming.

    In this article, we will look at some of the most commonly used built-in functions in C++ so you can start using them in your code.

    What we’ll cover:

    1. The sqrt() Function

    2. The pow() Function

    3. The sort() Function

    4. The find() Function

    5. The binarysearch() Function

    6. The max() Function

    7. The min() Function

    8. The swap() Function

    9. The toupper() Function

    10. The tolower() Function

    You use the sqrt() function to determine the square root of the value of type double. It is defined inside the <cmath> header file.

    Syntax:

    sqrt (n) 

    Parameter: This function takes only one parameter of type double which is a number we want to find the square root of.

    Return Type: The square root of the value of type double.

    Example Code

    Let’s look at an example so you can see how this function works:

    // C++ program to see the use of sqrt() function #include <cmath>  #include <iostream>  using namespace std; int main() { double x = 100; double answer; // Use the sqrt() function to calculate the square root of the number answer = sqrt(x); // Print the result  cout << answer << endl; return 0; } 

    Output:

    10

    The pow() Function

    You use the pow() function to find the value of the given number raised to some power. This function is also defined inside the <cmath> header file.

    Syntax:

    double pow(double x, double y); 

    Parameters:

    • x: The base number.

    • y: The exponential power.

    Return Type: value of x raised to the power y.

    Example Code:

    Let’s look at an example to see how this works:

    // C++ program to see the use of the pow() function #include <cmath> #include <iostream> using namespace std; int main() { // Declare an integer variable 'base'  int base = 5; // Declare an integer variable 'exponent'  int exponent = 3; // pow(5, 3) means 5^3 which is 5*5*5 = 125 // Use the pow() function to calculate base raised to the power of exponent int answer = pow(base, exponent); // output the result cout << answer << endl; } 

    Output:

    125

    The sort() Function

    The sort() function is part of STL’s <algorithm> header. It is a function template that you can use to sort the random access containers, such as vectors, arrays, and so on.

    Syntax:

    sort (arr , arr + n, comparator) 

    Parameters:

    • arr: The pointer or iterator to the first element of the array.

    • arr + n: The pointer to the imaginary element next to the last element of the array.

    • comparator: The unary predicate function that is used to sort the value in some specific order. The default value of this sorts the array in ascending order.

    Return Value: This function does not return any value.

    Example Code:

    Let’s look at an example:

    #include <iostream>  #include <algorithm> // Header file that includes the sort() function using namespace std; int main() { // Declare and initialize an integer array with unsorted elements int arr[] = { 13, 15, 12, 14, 11, 16, 18, 17 }; // Calculate the number of elements in the array int n = sizeof(arr) / sizeof(arr[0]); // Use the built-in sort() function from the algorithm library sort(arr, arr + n); // Print the sorted array using a loop for (int i = 0; i < n; ++i) cout << arr[i] << " "; return 0; } 

    Output:

    11 12 13 14 15 16 17 18

    The find() Function

    The find() function is also part of the STL <algorithm> library. You use this function to find a value in the given range. You can use it with both sorted and unsorted datasets as it implements a linear search algorithm.

    Syntax:

    find(startIterator, endIterator, key) 

    Parameters:

    • startIterator: Iterates to the beginning of the range.

    • endIterator: Iterates to the end of the range.

    • key: The value to be searched.

    Return Value: If the element is found, then the iterator is set to the element. Otherwise, it iterates to the end.

    Example Code:

    Let’s look at an example to better understand how it works:

    // C++ program to see the the use of the find() function #include <algorithm> // Required for the find() function #include <iostream>  #include <vector>  using namespace std; int main() { // Initialize a vector  vector<int> dataset{ 12, 28, 16, 7, 33, 43 }; // Use the find() function to search for the value 7 auto index = find(dataset.begin(), dataset.end(), 7); // Check if the element was found if (index != dataset.end()) { // If found, print the position (index) by subtracting the starting iterator cout << "The element is found at the " << index - dataset.begin() << "nd index"; } else { // If not found cout << "Element not found"; } return 0; } 

    Output:

    The element is found at the 3rd index

    The binary_search() Function

    The binary_search() function is also used to find an element in the range – but this function implements binary search instead of linear search as compared to the find() function. It’s also faster than the find() function, but you can only use it on sorted datasets with random access. It’s defined inside the <algorithm> header file.

    Syntax:

    binary_search (starting_pointer , ending_pointer , target); 

    Parameters:

    • starting_pointer: Pointer to the start of the range.

    • ending_pointer: Pointer to the element after the end of the range.

    • target: Value to be searched in the dataset.

    Return Value:

    • Returns true if the target is found.

    • Else return false.

    Example Code:

    Let’s check out an example to see how it works:

    // C++ program for the binary_search() function #include <algorithm>  #include <iostream>  #include <vector>  using namespace std; int main() { // Initialize a sorted vector of integers vector<int> arr = { 56, 57, 58, 59, 60, 61, 62 }; // binary_search() works only on sorted containers if (binary_search(arr.begin(), arr.end(), 62)) { // If found, print that the element is present cout << 62 << " is present in the vector."; } else { // If not found, print that the element is not present cout << 16 << " is not present in the vector"; } cout << endl; } 

    Output:

    62 is present in the vector.

    The max() Function

    You can use the std::max() function to compare two numbers and find the bigger one between them. It’s also defined inside the <algorithm> header file.

    Syntax:

    max (a , b) 

    Parameters:

    • a: First number

    • b: Second number

    Return Value:

    • This function returns the larger number between the two numbers a and b.

    • If the two numbers are equal, it returns the first number.

    Example Code:

    Here’s an example:

    // max() function #include <algorithm>  #include <iostream>  using namespace std; int main() { // Declare two integer variables int a = 8 ; int b = 10 ; // Use the max() function to find the larger number between a and b int maximum = max(a, b); // Display the result with a meaningful message cout << "The maximum of " << a << " and " << b << " is: " << maximum << endl; return 0; } 

    Output:

    The maximum of 8 and 10 is: 10

    The min() Function

    You can use the std::min() function to compare two numbers and find the smaller of the two. It’s also defined inside the <algorithm> header file.

    Syntax:

    min (a , b) 

    Parameters:

    • a: First number

    • b: Second number

    Return Value:

    • This function returns the smaller number between the two numbers a and b.

    • If the two numbers are equal, it returns the first number.

    Example Code:

    Here’s an example:

    // use of the min() function #include <algorithm> // For the built-in min() function #include <iostream>  using namespace std; int main() { // Declare two integer variables to store user input int a = 4 ; int b = 8 ; // Use the min() function to find the smaller  int smallest = min(a, b); // Display the result  cout << "The smaller number between " << a << " and " << b << " is: " << smallest << endl; return 0; } 

    Output:

    The smaller number between 4 and 8 is: 4

    The swap() Function

    The std::swap() function lets you swap two values. It’s defined inside <algorithm> header file.

    Syntax:

    swap(a , b); 

    Parameters:

    • a: First number

    • b: Second number

    Return Value: This function does not return any value.

    Example:

    Here’s how it works:

    // use of the swap() function #include <algorithm> // For the built-in swap() function #include <iostream>  using namespace std; int main() { int firstNumber = 8 ; int secondNumber = 9 ; // Use the built-in swap() function to exchange values swap(firstNumber, secondNumber); // Display values after swapping cout << "After the swap:" << endl; cout << firstNumber << " " << secondNumber << endl; return 0; } 

    Output:

    After the swap:

    9 8

    The tolower() Function

    You can use the tolower() function to convert a given alphabet character to lowercase. It’s defined inside the <cctype> header.

    Syntax:

    tolower (c); 

    Parameter(s):

    • c: The character to be converted.

    Return Value:

    • Lowercase of the character c.

    • Returns c if c is not a letter.

    Example Code:

    Here’s how it works:

    // C++ program // use of tolower() function #include <cctype>  #include <iostream>  using namespace std; int main() { // Declare and initialize a string with uppercase characters string str = "FRECODECAMP"; for (auto& a : str) { a = tolower(a); } // Print the modified string  cout << str; return 0; } 

    Output:

    freecodecamp

    The toupper() Function

    You can use the toupper() function to convert the given alphabet character to uppercase. It’s defined inside the <cctype> header.

    Syntax:

    toupper (c); 

    Parameters:

    • c: The character to be converted.

    Return Value

    • Uppercase of the character c.

    • Returns c if c is not a letter.

    Example Code:

    Here’s how it works:

    // use of toupper() function #include <cctype>  #include <iostream>  using namespace std; int main() { // Declare and initialize a string  string str = "freecodecamp"; for (auto& a : str) { a = toupper(a); } // Output the converted uppercase string cout << str; return 0; } 

    Output:

    FREECODECAMP

    Conclusion

    Inbuilt functions are helpful tools in competitive programming and in common programming tasks. These help in improving code readability and enhance the efficiency of code. In the above article, we discussed some very useful common inbuilt functions. Some common inbuilt functions are max(), min(), sort(), and sqrt(), etc. By using these inbuilt libraries, we can reduce boilerplate code and speed up the process of software development. These help in writing more concise, reliable, and maintainable C++ programs.

    If you enjoyed this article, you can check out more of my work here:
    Ayush Mishra’s Author Profile on TutorialsPoint

    And I’ve written some other tutorials about math and programming:

    How to Find the Area of a Square using Python?

    How to Calculate the Area of a Circle using C++?


    Source: freeCodeCamp Programming Tutorials: Python, JavaScript, Git & More.

  • Many Lung Cancers Are Now in Nonsmokers. Scientists Want to Know Why.

    July 22, 2025
    Health

    The face of lung cancer — once older men with a history of smoking — has changed.


    Source: NYT > Well.

Previous Page
1 … 878 879 880 881 882 … 911
Next Page
MONIMEGA
  • Instagram
  • Facebook
  • Twitter
Gestisci Consenso
Per fornire le migliori esperienze, utilizziamo tecnologie come i cookie per memorizzare e/o accedere alle informazioni del dispositivo. Il consenso a queste tecnologie ci permetterà di elaborare dati come il comportamento di navigazione o ID unici su questo sito. Non acconsentire o ritirare il consenso può influire negativamente su alcune caratteristiche e funzioni.
Funzionale Always active
L'archiviazione tecnica o l'accesso sono strettamente necessari al fine legittimo di consentire l'uso di un servizio specifico esplicitamente richiesto dall'abbonato o dall'utente, o al solo scopo di effettuare la trasmissione di una comunicazione su una rete di comunicazione elettronica.
Preferenze
L'archiviazione tecnica o l'accesso sono necessari per lo scopo legittimo di memorizzare le preferenze che non sono richieste dall'abbonato o dall'utente.
Statistiche
L'archiviazione tecnica o l'accesso che viene utilizzato esclusivamente per scopi statistici. L'archiviazione tecnica o l'accesso che viene utilizzato esclusivamente per scopi statistici anonimi. Senza un mandato di comparizione, una conformità volontaria da parte del vostro Fornitore di Servizi Internet, o ulteriori registrazioni da parte di terzi, le informazioni memorizzate o recuperate per questo scopo da sole non possono di solito essere utilizzate per l'identificazione.
Marketing
L'archiviazione tecnica o l'accesso sono necessari per creare profili di utenti per inviare pubblicità, o per tracciare l'utente su un sito web o su diversi siti web per scopi di marketing simili.
  • Manage options
  • Manage services
  • Manage {vendor_count} vendors
  • Read more about these purposes
Visualizza le preferenze
  • {title}
  • {title}
  • {title}