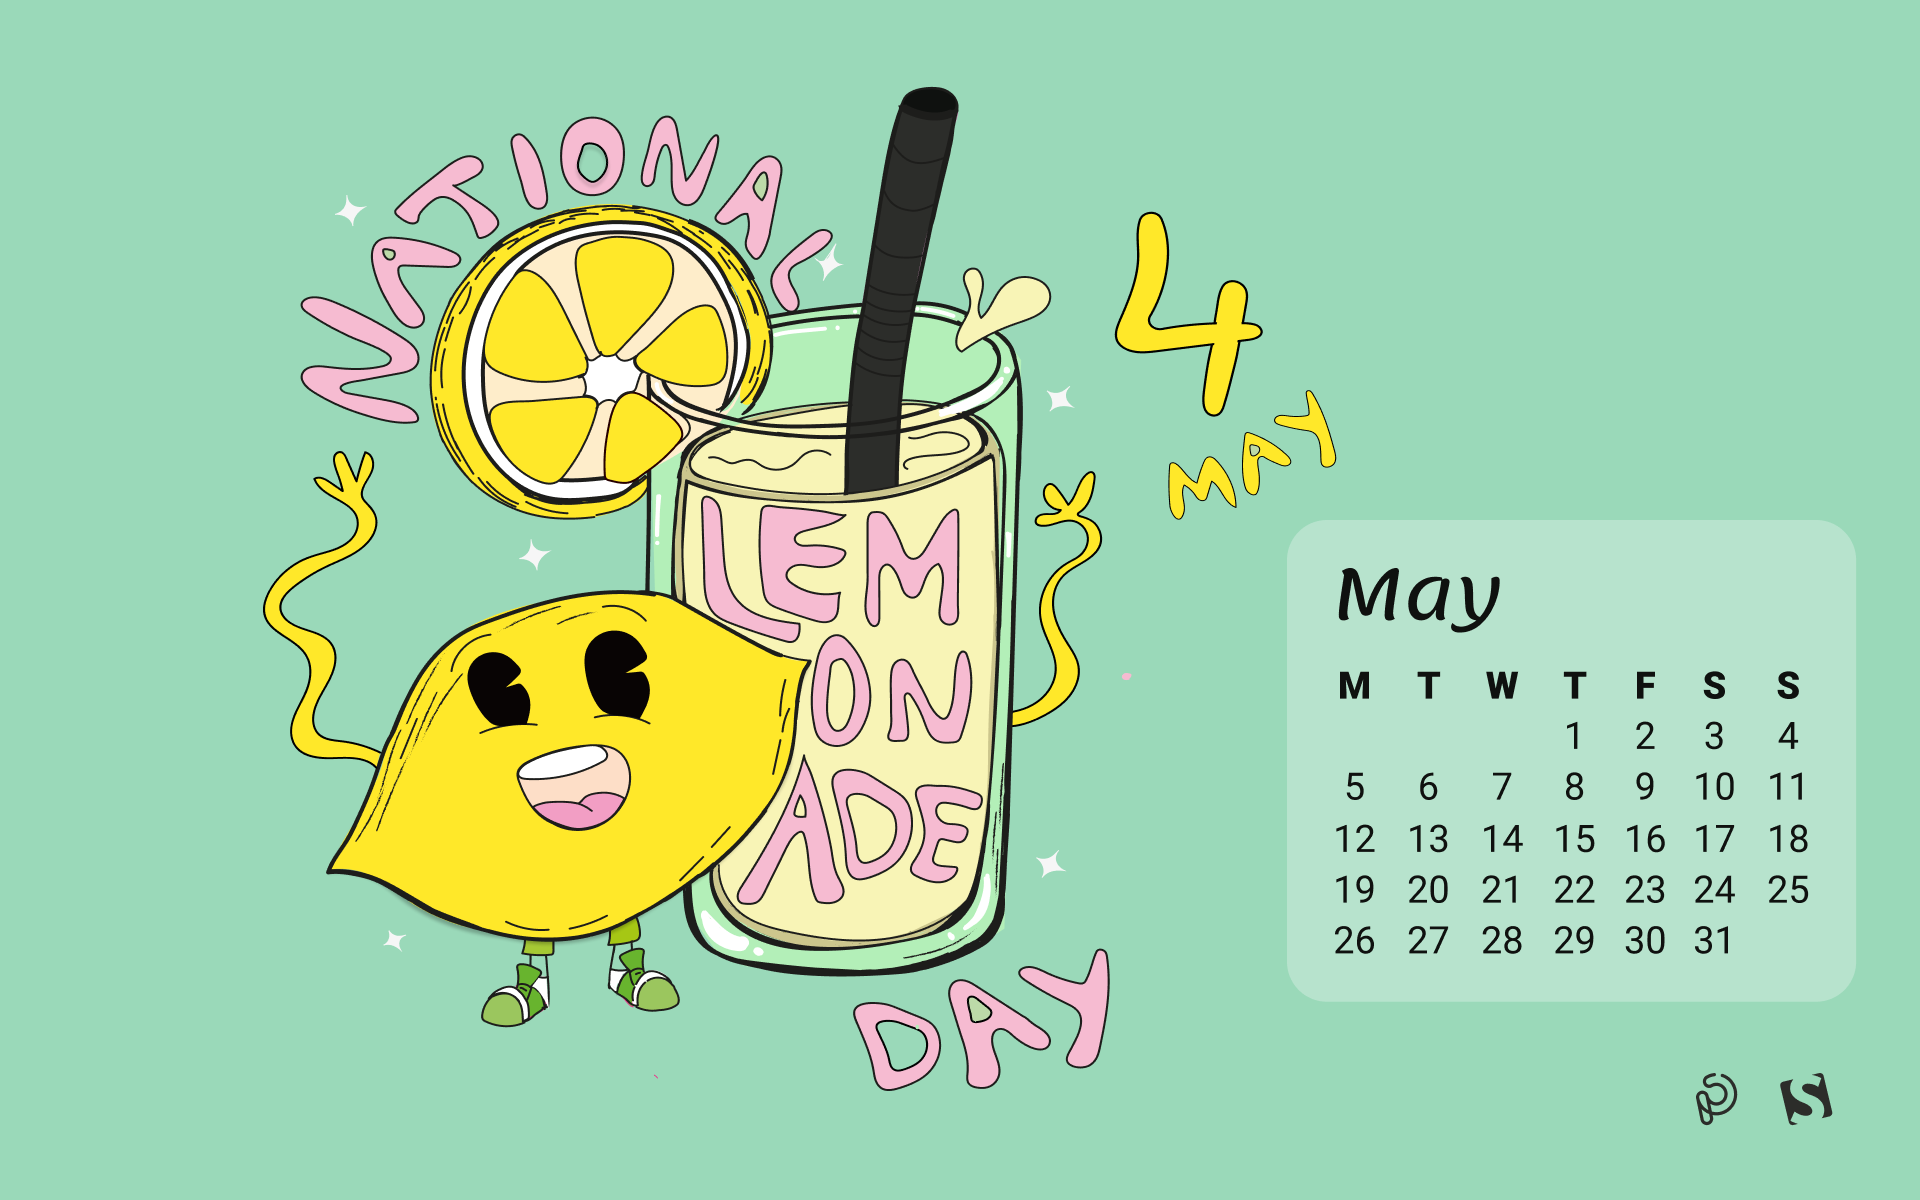
MONIMEGA
  • Blog
    • Politics
    • Software
    • Technology
    • Business
    • Design
    • Hardware
    • Health
    • Italy
    • Music
    • Sports
    • Strategy
    • World
  • Contatto
  • Galleria
  • Informazioni
  • Servizi
  • WCAG 3.0’s Proposed Scoring Model: A Shift In Accessibility Evaluation

    WCAG 3.0’s Proposed Scoring Model: A Shift In Accessibility Evaluation

    May 2, 2025
    Software

    Since their introduction in 1999, the Web Content Accessibility Guidelines (WCAG) have shaped how we design and develop inclusive digital products. The WCAG 2.x series, released in 2008, introduced clear technical criteria judged in a binary way: either a success criterion is met or not. While this model has supported regulatory clarity and auditability, its “all-or-nothing” nature often fails to reflect the nuance of actual user experience (UX).

    Over time, that disconnect between technical conformance and lived usability has become harder to ignore. People engage with digital systems in complex, often nonlinear ways: navigating multistep flows, dynamic content, and interactive states. In these scenarios, checking whether an element passes a rule doesn’t always answer the main question: can someone actually use it?

    WCAG 3.0 is still in draft, but is evolving — and it represents a fundamental rethinking of how we evaluate accessibility. Rather than asking whether a requirement is technically met, it asks how well users with disabilities can complete meaningful tasks. Its new outcome-based model introduces a flexible scoring system that prioritizes usability over compliance, shifting focus toward the quality of access rather than the mere presence of features.

    Draft Status: Ambitious, But Still Evolving

    WCAG 3.0 was first introduced as a public working draft by the World Wide Web Consortium (W3C) Accessibility Guidelines Working Group in early 2021. The draft is still under active development and is not expected to reach W3C Recommendation status for several years, if not decades, by some accounts. This extended timeline reflects both the complexity of the task and the ambition behind it:

    WCAG 3.0 isn’t just an update — it’s a paradigm shift.

    Unlike WCAG 2.x, which focused primarily on web pages, WCAG 3.0 aims to cover a much broader ecosystem, including applications, tools, connected devices, and emerging interfaces like voice interaction and extended reality. It also rebrands itself as the W3C Accessibility Guidelines (while the WCAG acronym remains the same), signaling that accessibility is no longer a niche concern — it’s a baseline expectation across the digital world.

    Importantly, WCAG 3.0 will not immediately replace 2.x. Both standards will coexist, and conformance to WCAG 2.2 will continue to be valid and necessary for some time, especially in legal and policy contexts.

    This expansion isn’t just technical.

    WCAG 3.0 reflects a deeper philosophical shift: accessibility is moving from a model of compliance toward a model of effectiveness.

    Rules alone can’t capture whether a system truly works for someone. That’s why WCAG 3.0 leans into flexibility and future-proofing, aiming to support evolving technologies and real-world use over time. It formalizes a principle long understood by practitioners:

    Inclusive design isn’t about passing a test; it’s about enabling people.

    A New Structure: From Success Criteria To Outcomes And Methods

    WCAG 2.x is structured around four foundational principles — Perceivable, Operable, Understandable, and Robust (aka POUR) — and testable success criteria organized into three conformance levels (A, AA, AAA). While technically precise, these criteria often emphasize implementation over impact.

    WCAG 3.0 reorients this structure toward user needs and real outcomes. Its hierarchy is built on:

    • Guidelines: High-level accessibility goals tied to specific user needs.
    • Outcomes: Testable, user-centered statements (e.g., “Users have alternatives for time-based media”).
    • Methods: Technology-specific or agnostic techniques that help achieve the outcomes, including code examples and test instructions.
    • How-To Guides: Narrative documentation that provides practical advice, user context, and design considerations.

    This shift is more than organizational. It reflects a deeper commitment to aligning technical implementation with UX. Outcomes speak the language of capability, which is about what users should be able to do (rather than just technical presence).

    Crucially, outcomes are also where conformance scoring begins to take shape. For example, imagine a checkout flow on an e-commerce website. Under WCAG 2.x, if even one field in the checkout form lacks a label, the process may fail AA conformance entirely. However, under WCAG 3.0, that same flow might be evaluated across multiple outcomes (such as keyboard navigation, form labeling, focus management, and error handling), with each outcome receiving a separate score. If most areas score well but the error messaging is poor, the overall rating might be “Good” instead of “Excellent”, prompting targeted improvements without negating the entire flow’s accessibility.

    From Binary Checks To Graded Scores

    Rather than relying on pass or fail outcomes, WCAG 3.0 introduces a scoring model that reflects how well accessibility is supported. This shift allows teams to recognize partial successes and prioritize real improvements.

    How Scoring Works

    Each outcome in WCAG 3.0 is evaluated through one or more atomic tests. These can include the following:

    • Binary tests: “Yes” and “no” outcomes (e.g., does every image have alternative text?)
    • Percentage-based tests: Coverage-based scoring (e.g., what percentage of form fields have labels?)
    • Qualitative tests: Rated judgments based on criteria (e.g., how descriptive is the alternative text?)

    The result of these tests produces a score for each outcome, often normalized on a 0-4 or 0-5 scale, with labels like Poor, Fair, Good, and Excellent. These scores are then aggregated across functional categories (vision, mobility, cognition, etc.) and user flows.

    This allows teams to measure progress, not just compliance. A product that improves from “Fair” to “Good” over time shows real evolution — a concept that doesn’t exist in WCAG 2.x.

    Critical Errors: A Balancing Mechanism

    To ensure that severity still matters, WCAG 3.0 introduces critical errors, which are high-impact accessibility failures that can override an otherwise positive score.

    For example, consider a checkout flow. Under WCAG 2.x, a single missing label might cause the entire flow to fail conformance. WCAG 3.0, however, evaluates multiple outcomes — like form labeling, keyboard access, and error handling — each with its own score. Minor issues, such as unclear error messages or a missing label on an optional field, might lower the rating from “Excellent” to “Good”, without invalidating the entire experience.

    But if a user cannot complete a core action, like submitting the form, making a purchase, or logging in, that constitutes a critical error. These failures directly block task completion and significantly reduce the overall score, regardless of how polished the rest of the experience is.

    On the other hand, problems with non-essential features — like uploading a profile picture or changing a theme color — are considered lower-impact and won’t weigh as heavily in the evaluation.

    Conformance Levels: Bronze, Silver, Gold

    In place of categorizing conformance in tiers of Level A, Level AA, and Level AAA, WCAG 3.0 proposes three different conformance tiers:

    • Bronze: The new minimum. It is comparable to WCAG 2.2 Level AA, but based on scoring and foundational outcomes. The requirements are considered achievable via automated and guided manual testing.
    • Silver: This is a higher standard, requiring broader coverage, higher scores, and usability validation from people with disabilities.
    • Gold: The highest tier. Represents exemplary accessibility, likely requiring inclusive design processes, innovation, and extensive user involvement.

    Unlike in WCAG 2.2, where Level AAA is often seen as aspirational and inconsistent, these levels are intended to incentivize progression. They can also be scoped in the sense that teams can claim conformance for a checkout flow, mobile app, or specific feature, allowing iterative improvement.

    What You Should Do Now

    While WCAG 3.0 is still being developed, its direction is clear. That said, it’s important to acknowledge that the guidelines are not expected to be finalized in a few years. Here’s how teams can prepare:

    • Continue pursuing WCAG 2.2 Level AA. It remains the most robust, recognized standard.
    • Familiarize yourself with WCAG 3.0 drafts, especially the outcomes and scoring model.
    • Start thinking in outcomes. Focus on what users need to accomplish, not just what features are present.
    • Embed accessibility into workflows. Shift left. Don’t test at the end — design and build with access in mind.
    • Involve users with disabilities early and regularly.

    These practices won’t just make your product more inclusive; they’ll position your team to excel under WCAG 3.0.

    Potential Downsides

    Even though WCAG 3.0 presents a bold step toward more holistic accessibility, several structural risks deserve early attention, especially for organizations navigating regulation, scaling design systems, or building sustainable accessibility practices. Importantly, many of these risks are interconnected: challenges in one area may amplify issues in others.

    Subjective Scoring

    The move from binary pass or fail criteria to scored evaluations introduces room for subjective interpretation. Without standardized calibration, the same user flow might receive different scores depending on the evaluator. This makes comparability and repeatability harder, particularly in procurement or multi-vendor environments. A simple alternative text might be rated as “adequate” by one team and “unclear” by another.

    Reduced Compliance Clarity

    That same subjectivity leads to a second concern: the erosion of clear compliance thresholds. Scored evaluations replace the binary clarity of “compliant” or “not” with a more flexible, but less definitive, outcome. This could complicate legal enforcement, contractual definitions, and audit reporting. In practice, a product might earn a “Good” rating while still presenting critical usability gaps for certain users, creating a disconnect between score and actual access.

    Legal and Policy Misalignment

    As clarity around compliance blurs, so does alignment with existing legal frameworks. Many current laws explicitly reference WCAG 2.x and its A, AA, and AAA levels (e.g. Section 508 of the Rehabilitation Act of 1973, European Accessibility Act, The Public Sector Bodies (Websites and Mobile Applications) (No. 2) Accessibility Regulations 2018).

    Until WCAG 3.0 is formally mapped to those standards, its use in regulated contexts may introduce risk. Teams operating in healthcare, finance, or public sectors will likely need to maintain dual conformance strategies in the interim, increasing cost and complexity.

    Risk Of Minimum Viable Accessibility

    Perhaps most concerning, this ambiguity can set the stage for a “minimum viable accessibility” mindset. Scored models risk encouraging “Bronze is good enough” thinking, particularly in deadline-driven environments. A team might deprioritize improvements once they reach a passing grade, even if essential barriers remain.

    For example, a mobile app with strong keyboard support but missing audio transcripts could still achieve a passing tier, leaving some users excluded.

    Conclusion

    WCAG 3.0 marks a new era in accessibility — one that better reflects the diversity and complexity of real users. By shifting from checklists to scored evaluations and from rigid technical compliance to practical usability, it encourages teams to prioritize real-world impact over theoretical perfection.

    As one might say, “It’s not about the score. It’s about who can use the product.” In my own experience, I’ve seen teams pour hours into fixing minor color contrast issues while overlooking broken keyboard navigation, leaving screen reader users unable to complete essential tasks. WCAG 3.0’s focus on outcomes reminds us that accessibility is fundamentally about functionality and inclusion.

    At the same time, WCAG 3.0’s proposed scoring models introduce new responsibilities. Without clear calibration, stronger enforcement patterns, and a cultural shift away from “good enough,” we risk losing the very clarity that made WCAG 2.x enforceable and actionable. The promise of flexibility only works if we use it to aim higher, not to settle earlier.

    For teams across design, development, and product leadership, this shift is a chance to rethink what success means. Accessibility isn’t about ticking boxes — it’s about enabling people.

    By preparing now, being mindful of the risks, and focusing on user outcomes, we don’t just get ahead of WCAG 3.0 — we build digital experiences that are truly usable, sustainable, and inclusive.

    Further Reading On SmashingMag

    • “A Roundup Of WCAG 2.2 Explainers,” Geoff Graham
    • “Getting To The Bottom Of Minimum WCAG-Conformant Interactive Element Size,” Eric Bailey
    • “How To Make A Strong Case For Accessibility,” Vitaly Friedman
    • “A Designer’s Accessibility Advocacy Toolkit,” Yichan Wang

    Source: Articles on Smashing Magazine — For Web Designers And Developers.
  • Building TMT Mirror Visualization with LLM

    April 30, 2025
    Software

    Creating a user interface that visualizes a real-world structure — like the Thirty Meter Telescope’s mirror — might seem like a task that demands deep knowledge of geometry, D3.js, and SVG graphics. But with a Large Language Model (LLM) like Claude or ChatGPT, you don’t need to know everything upfront.

    This article documents a journey in building a complex, interactive UI with no prior experience in D3.js or UI development in general. The work was done as part of building a prototype for an operational user interface for the telescope’s primary mirror, designed to show real-time status of mirror segments. It highlights how LLMs help you “get on with it”, giving you a working prototype even when you’re unfamiliar with the underlying tech. More importantly, it shows how iterative prompting — refining your requests step-by-step — leads not only to the right code but also to a clearer understanding of what you’re trying to build.

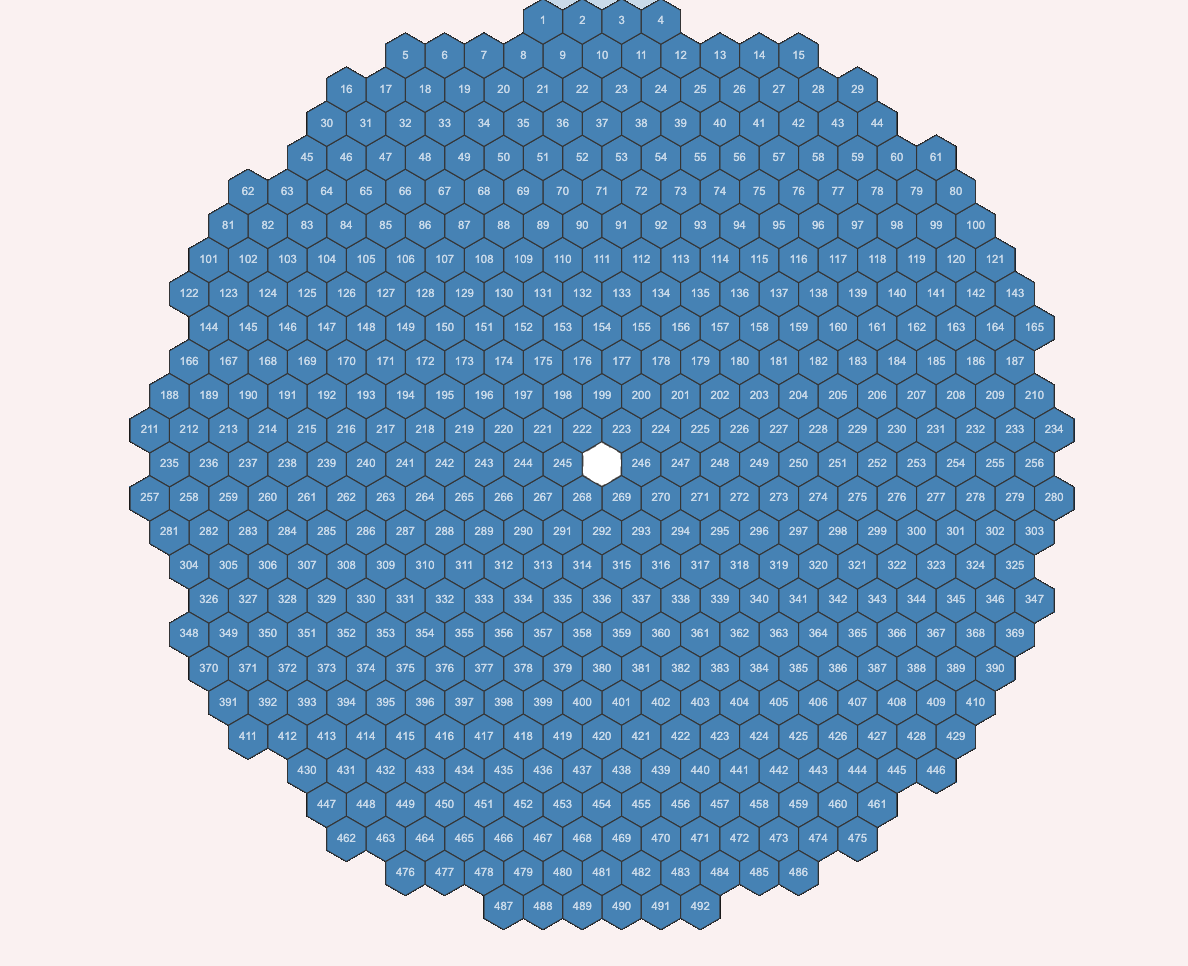
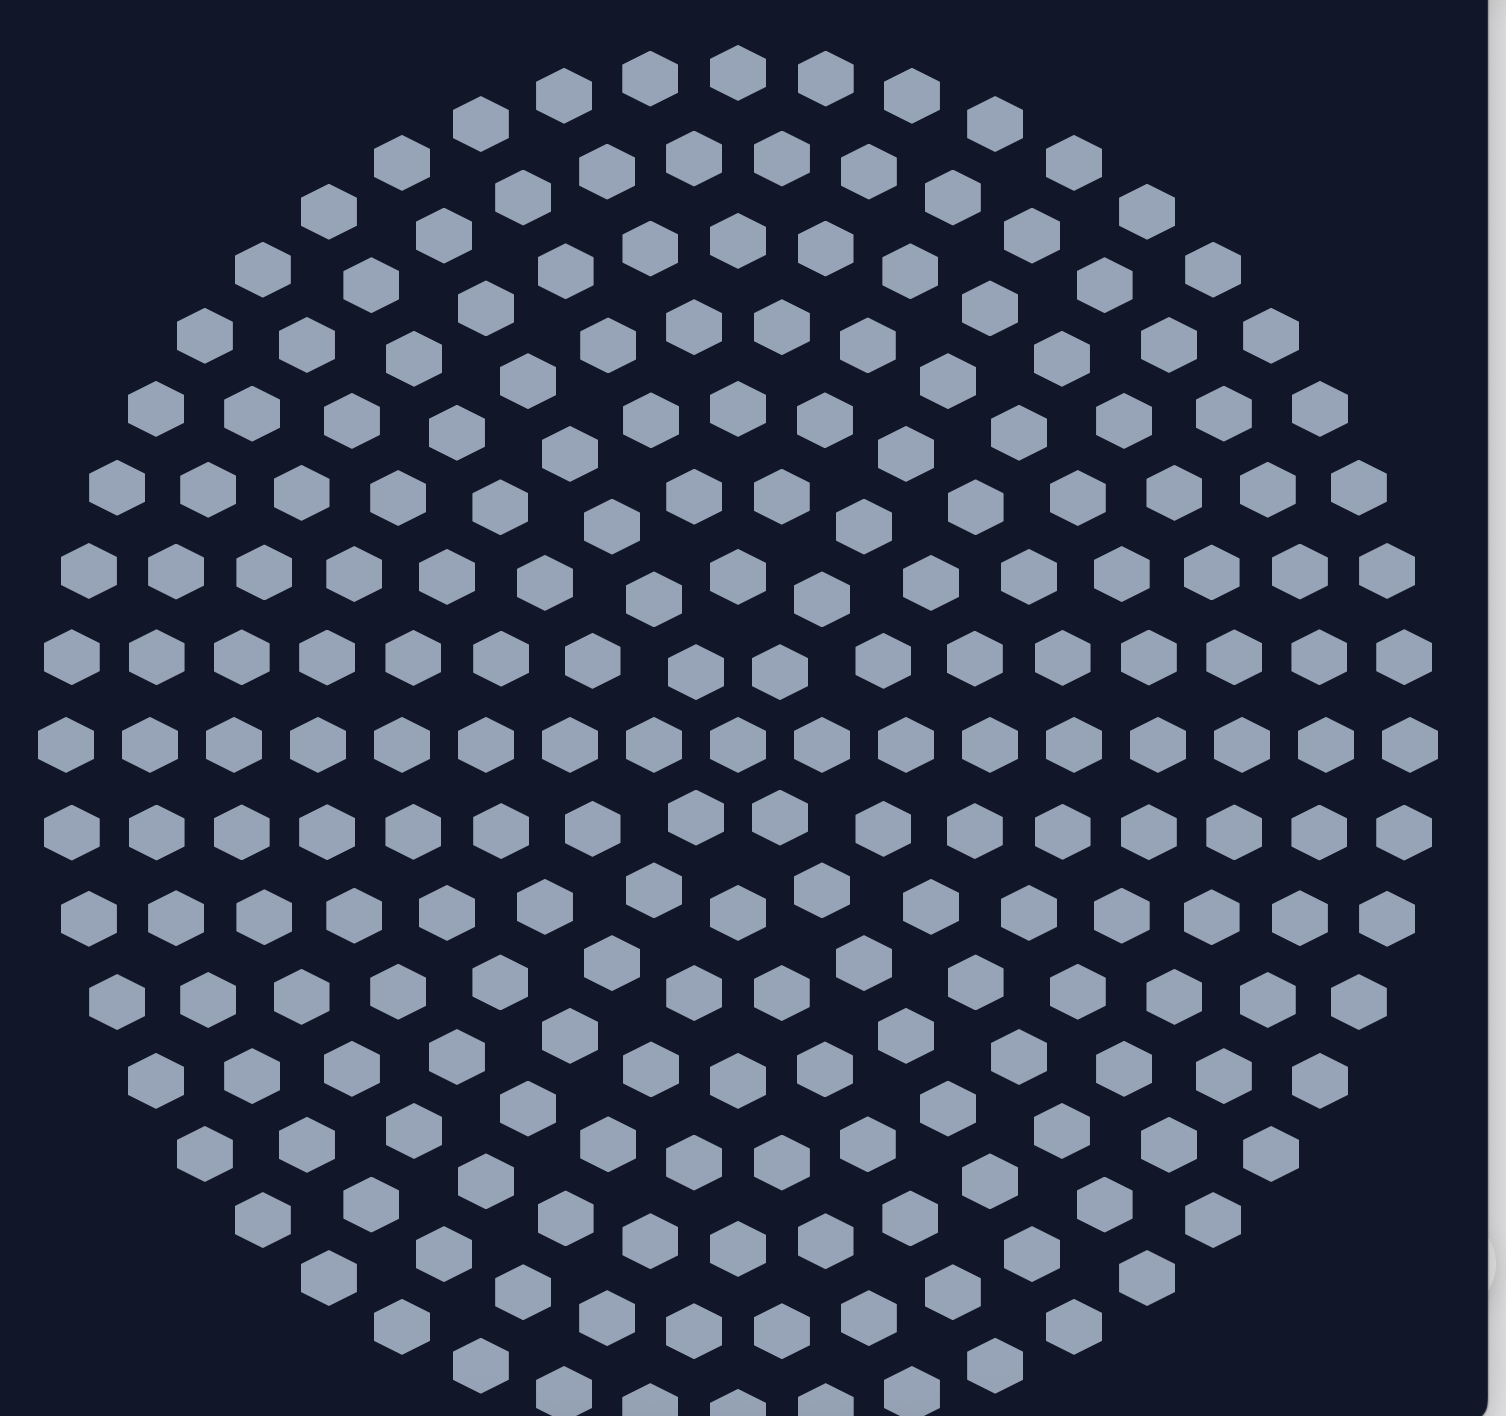
    We wanted to create an HTML-based visualization of the Thirty Meter Telescope’s primary mirror, composed of 492 hexagonal segments arranged symmetrically in a circular pattern.

    We began with a high-level prompt that described the structure, but soon realized that to reach my goal, I’d need to guide the AI step by step.

    Step 1: The Initial Prompt

    “I want to create an HTML view of the Thirty Meter Telescope’s honeycomb mirror. Try to generate an HTML and CSS based UI for this mirror, which consists of 492 hexagonal segments arranged in a circular pattern. Overall structure is of a honeycomb. The structure should be symmetric. For example the number of hexagons in the first row should be same in the last row. The number of hexagons in the second row should be same as the one in the second last row, etc.”

    Claude gave it a shot — but the result wasn’t what I had in mind. The layout was blocky and not quite symmetric. That’s when I decided to take a step-by-step approach.

    Initial attempt showing blocky, non-symmetric layout

    Step 2: Drawing One Hexagon

    “This is not what I want… Let’s do it step by step.”

    “Let’s draw one hexagon with flat edge vertical. The hexagon should have all sides of same length.”

    “Let’s use d3.js and draw svg.”

    “Let’s draw only one hexagon with d3.”

    Claude generated clean D3 code to draw a single hexagon with the correct orientation and geometry. It worked — and gave me confidence in the building blocks.

    Lesson: Start small. Confirm the foundation works before scaling complexity.

    Single hexagon with flat edge vertical

    Step 3: Adding a Second Hexagon

    “Nice… Now let’s add one more hexagon next to this one. It should share vertical edge with the first hexagon.”

    Claude adjusted the coordinates, placing the second hexagon adjacent to the first by aligning their vertical edges. The layout logic was beginning to emerge.

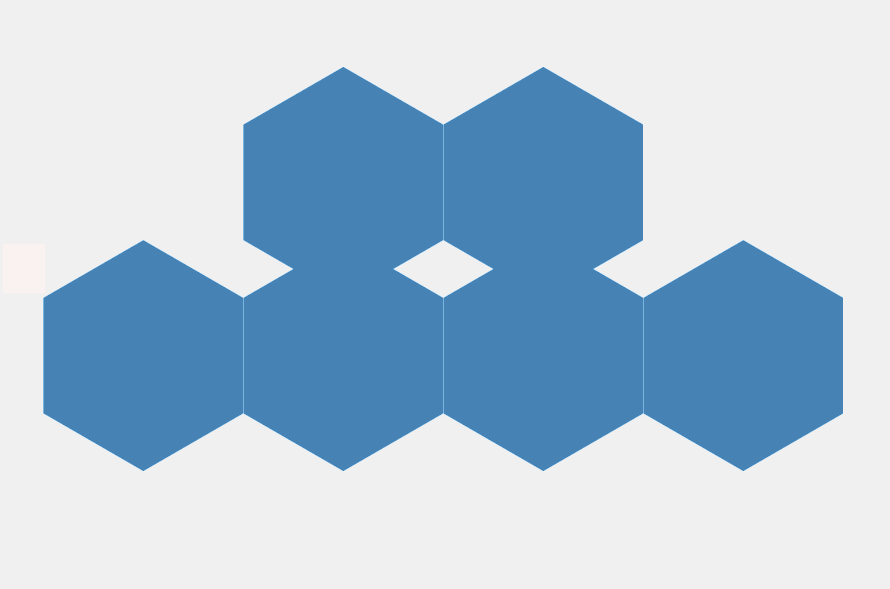
    Two hexagons sharing a vertical edge

    Step 4: Creating the Second Row

    “Now let’s add one more row.

    The hexagons in the second row share vertical edges with each other similar to the first row.

    The top slanting edges of the hexagons in the second row should be shared with the bottom slanting edges of the hexagons in the first row.

    The number of hexagons in the second row should be such that the first row appears centrally positioned with the second row.”

    Initial attempts failed to properly align the slanting edges.

    “Oops… this does not share the slanting edges with the previous row.”
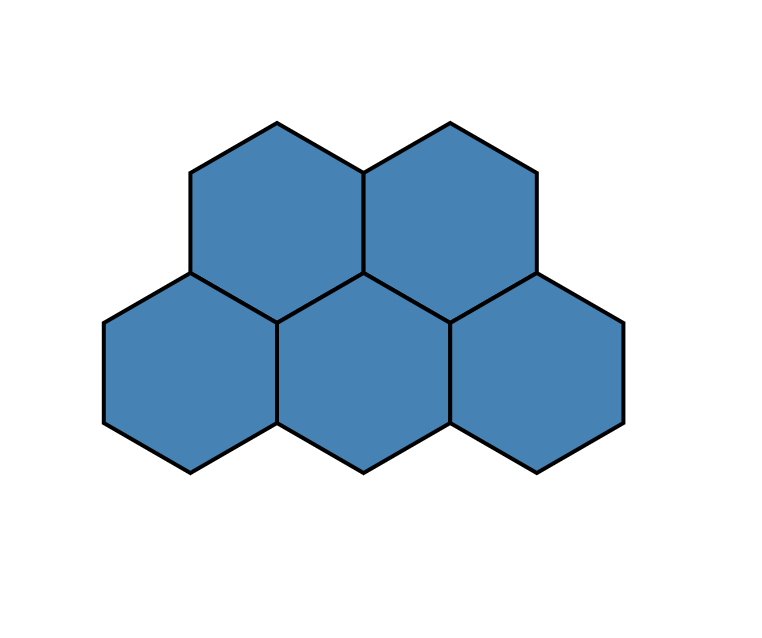
    Two rows of hexagons

    But eventually, after clarifying spacing and offset logic, Claude got it right.

    Two rows of hexagons with proper edge alignment

    Lesson: Geometry-based layouts often require multiple iterations with careful visual inspection.

    Step 5: Expanding into a Symmetric Structure

    “Now we need to create bigger structure with more hexagons arranged in more rows such that: The overall structure appears circular like honeycomb. The number of hexagons in the rows goes on increasing and then goes on decreasing to form a perfectly symmetric structure. The total number of hexagons needs to be 492 to match the TMT telescope. We can have an empty hexagon (showing empty space) exactly at the center of the circle.”

    Claude used a ring-based layout approach to simulate circular symmetry. But at first:

    “This is not circular but looks more like a hexagonal overall view…”

    Then I suggested:

    “Try with only 6 hexagons in the first and last row.”

    This change improved symmetry and helped achieve a visually circular layout. The number of hexagons per row increased and then decreased — exactly as desired.

    Step 6: Tuning the Central Opening

    “This is better but we need a smaller opening at the center.The black space at the center is too big. It should be at most 1 or a few hexagons.”

    By reducing the empty space and rebalancing the inner rings, we finally got a well-packed, circular structure with a small central gap — matching the TMT design.

    Lesson: Use domain-specific constraints (like total count = 492) as guideposts for layout parameters.

    Step 7: Adding Numbering and Tooltips

    “We want to have a number on each hexagonal segment. They should be numbered sequentially. The first in the first row should be 1 and the last in the last row should be 492. When we show the hexagonal segment information on mouseover, we should show the number as well.”

    Claude initially assigned numbers based on ring index, not row order.

    “You are generating numbers based on position in the ring… But the numbering should be row-based. So we should somehow map the rings to the row. For example, Ring 13 segment number 483 is in row 1 and should be numbered 1, etc. Can you suggest a way to map segments from rings to rows this way?”

    Once this mapping was implemented, everything fell into place:

    • A circular layout of 492 numbered segments
    • A small central gap
    • Tooltips showing segment metadata
    • Visual symmetry from outer to inner rings
    Final structure with numbered segments and tooltips

    Reflections

    This experience taught me several key lessons:

    1. LLMs help you get on with it: Even with zero knowledge of D3.js or SVG geometry, I could start building immediately. The AI scaffolded the coding, and I learned through the process.
    2. Prompting is iterative: My first prompt wasn’t wrong — it just wasn’t specific enough. By reviewing the output at each step, clarified what I really wanted and refined my asks accordingly.
    3. LLMs unlock learning through building: In the end, I didn’t just get a working UI. I got an understandable codebase and a hands-on entry point into a new technology. Building first and learning from it.

    Conclusion

    What started as a vague design idea turned into a functioning, symmetric, interactive visualization of the Thirty Meter Telescope’s mirror — built collaboratively with an LLM.

    This experience reaffirmed that prompt-driven development isn’t just about generating code — it’s about thinking through design, clarifying intent, and building your way into understanding.

    If you’ve ever wanted to explore a new technology, build a UI, or tackle a domain-specific visualization — don’t wait to learn it all first.

    Start building with an LLM. You’ll learn along the way.


    Source: Martin Fowler.

  • Make Every Day Count (May 2025 Wallpapers Edition)

    Make Every Day Count (May 2025 Wallpapers Edition)

    April 30, 2025
    Software

    Sometimes, it doesn’t take a lot to get inspired. A short bike ride to soak in the sun, a coffee break with a friend, or listening to your favorite song might be just what you need to spark some fresh ideas on a busy day. And if that doesn’t do the trick, we have a little extra inspiration boost for you: desktop wallpapers!

    For this post, artists and designers from across the globe once again challenged their creative skills and designed desktop wallpapers to cater for some fresh inspiration this May — just like it has been a monthly tradition here at Smashing Magazine for more than 14 years already. You’ll find their artworks compiled below, along with a selection of May favorites from our wallpapers archives that are just too good to be forgotten. A big thank-you to everyone who shared their designs with us this month — this post wouldn’t be possible without your wonderful support!

    If you too would like to get featured in one of our upcoming wallpapers posts, please don’t hesitate to submit your design. We can’t wait to see what you’ll come up with! Happy May!

    • You can click on every image to see a larger preview.
    • We respect and carefully consider the ideas and motivation behind each and every artist’s work. This is why we give all artists the full freedom to explore their creativity and express emotions and experience through their works. This is also why the themes of the wallpapers weren’t anyhow influenced by us but rather designed from scratch by the artists themselves.

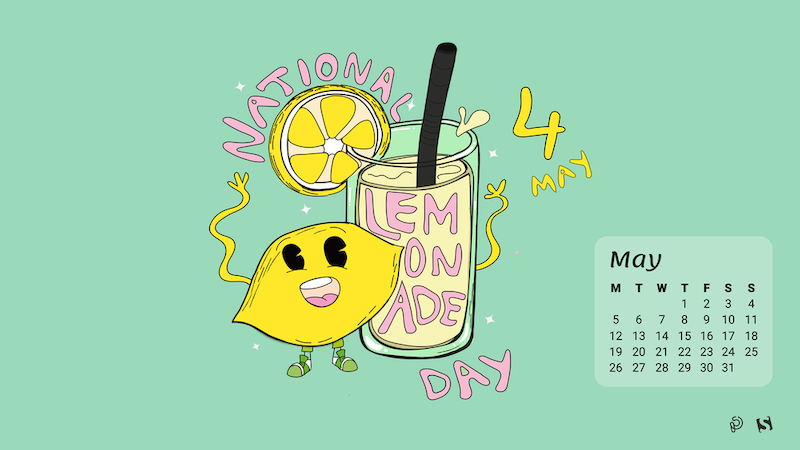
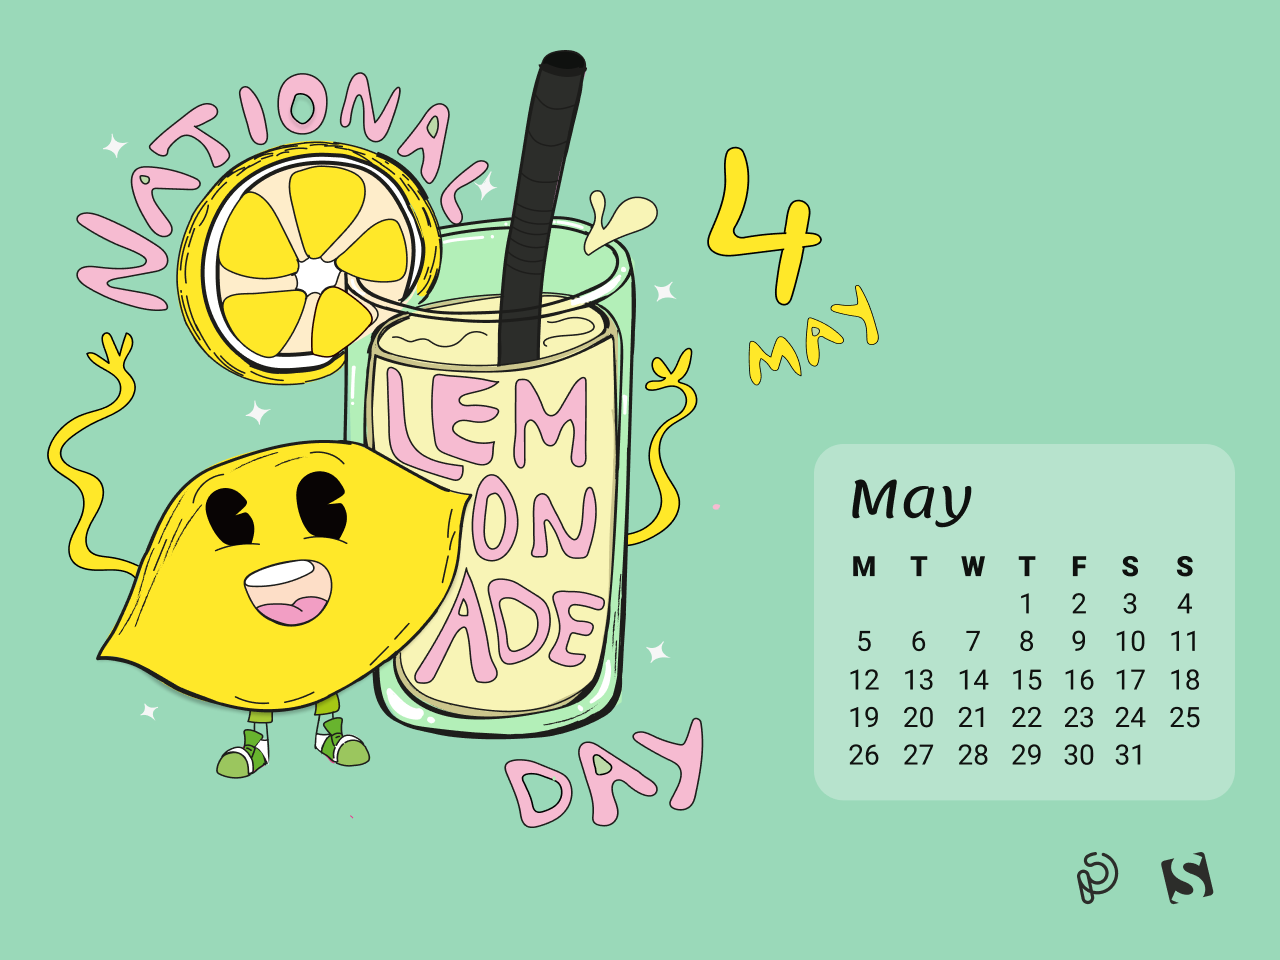
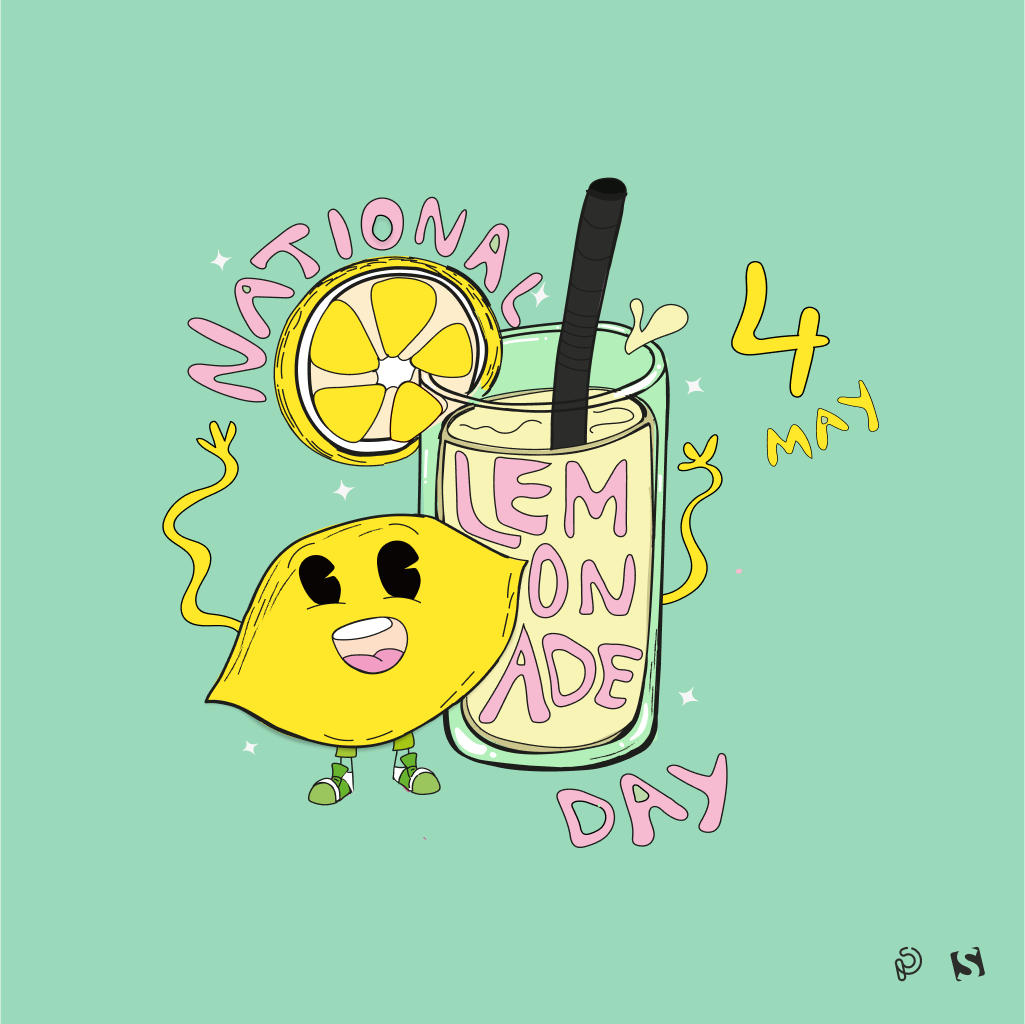
    Squeeze The Day

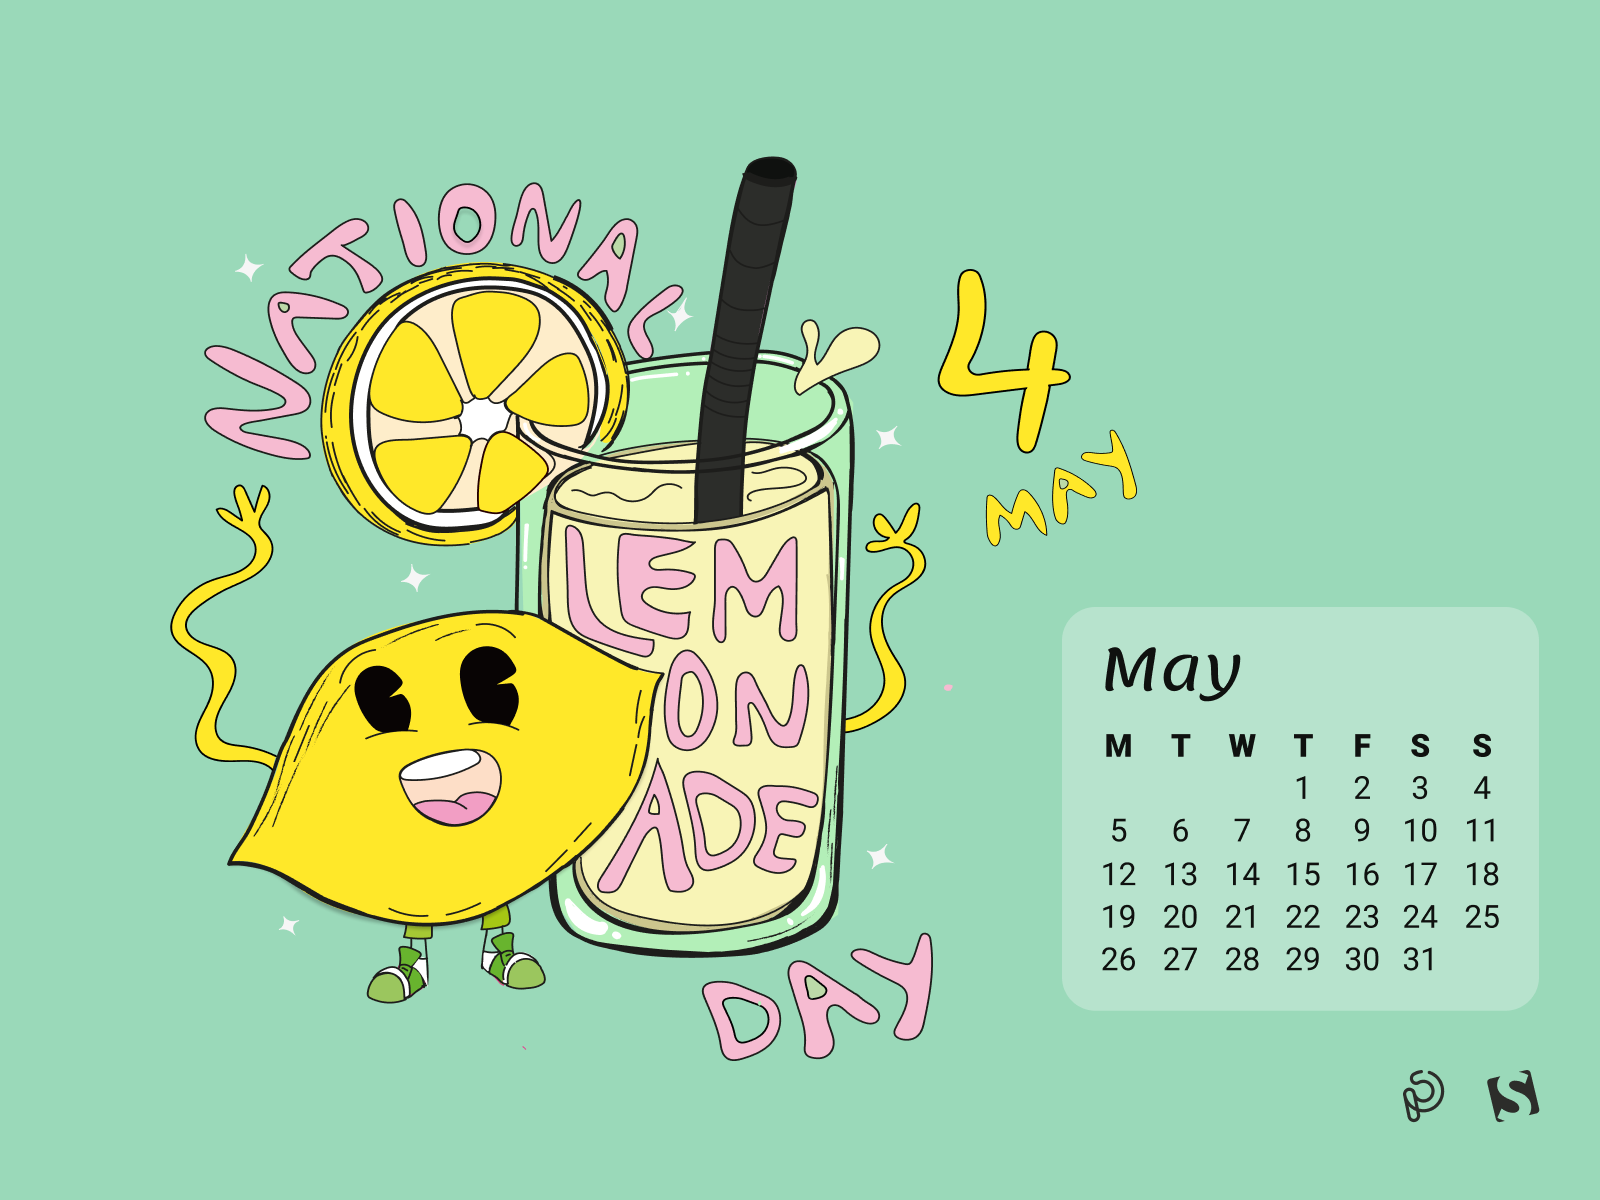
    “Happy National Lemonade Day! Whether you like it sweet, tart, sparkling, or spiked — today’s the perfect excuse to pour yourself a glass of sunshine. Support a local lemonade stand, whip up your own zesty creation, or just soak in the summer vibes. However you sip it, make it refreshing, bold, and bright. Cheers to lemons and all the lemonade moments life brings!” — Designed by PopArt Studio from Serbia.

    • preview
    • with calendar: 320×480, 640×480, 800×480, 800×600, 1024×768, 1024×1024, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1400×1050, 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440
    • without calendar: 320×480, 640×480, 800×480, 800×600, 1024×768, 1024×1024, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1400×1050, 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440

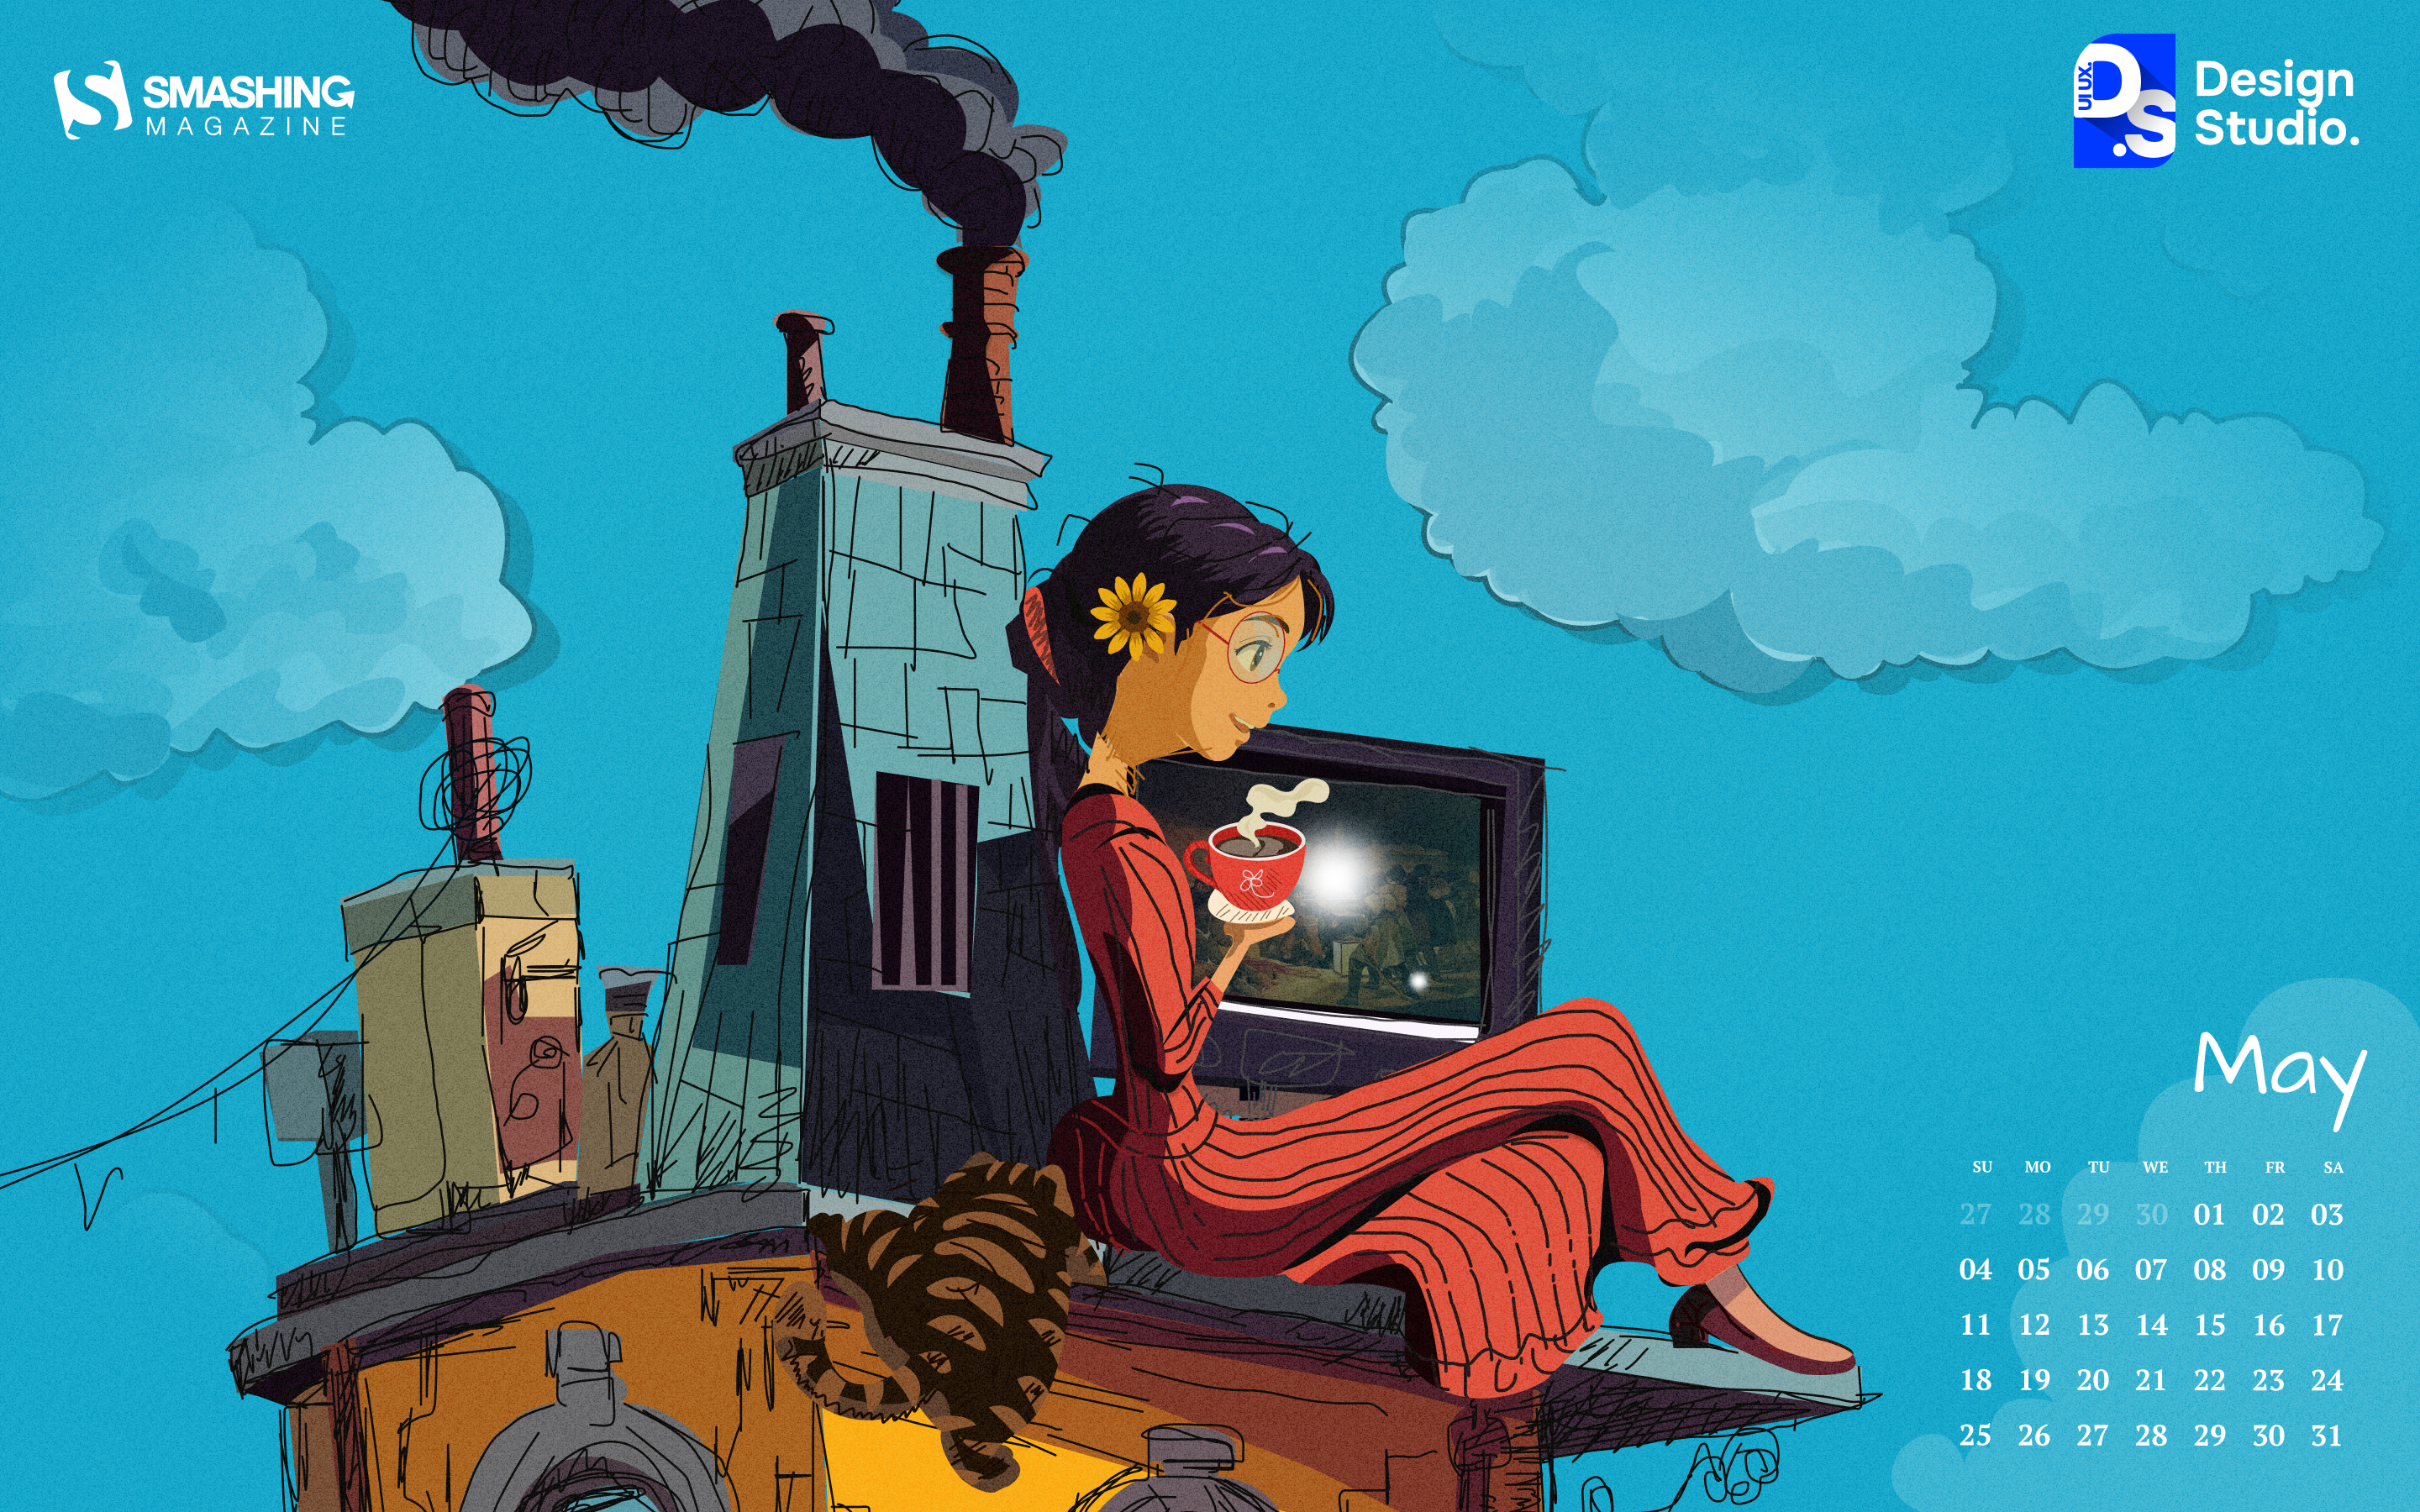
    My Crazy Thoughts

    “In this illustration, I want to express myself, just as I am, with all my upside-down, crazy thoughts. There are little things that make me happy: I love sitting quietly by the window and watching the rain. I enjoy watching the changes in the sky, the colors, and the clouds. It feels like every cloud says something to me, reminding me how important it is to give myself time. Nature always speaks to us through colors, shapes, and space. But nowadays, people are too busy — buying time, spending hours on movies and OTT platforms — always trying to prove themselves to others.
 We have forgotten how to simply be with ourselves, to connect with nature.” — Designed by Design Studio from India.

    • preview
    • with calendar: 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440
    • without calendar: 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440

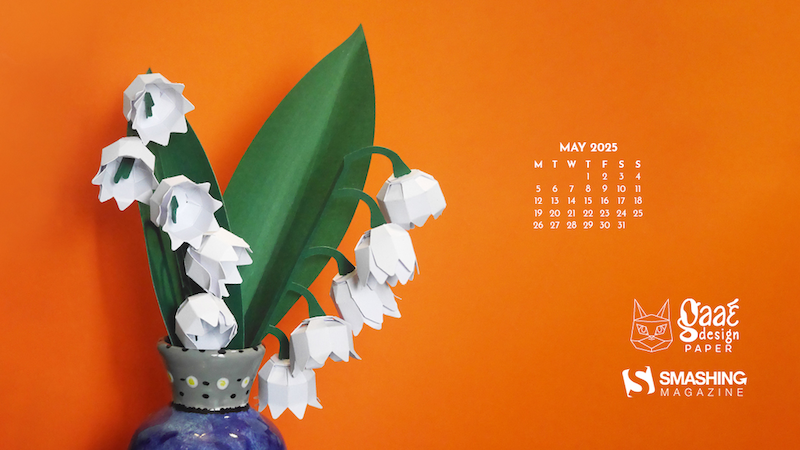
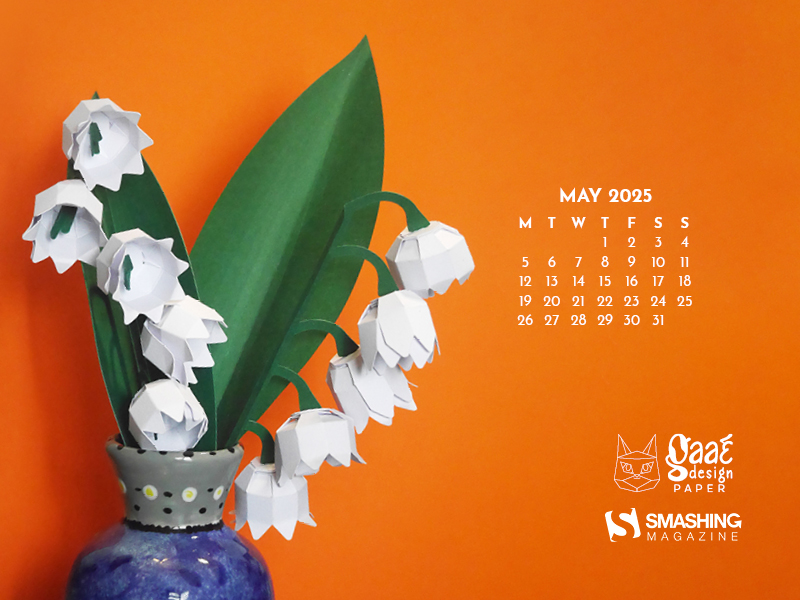
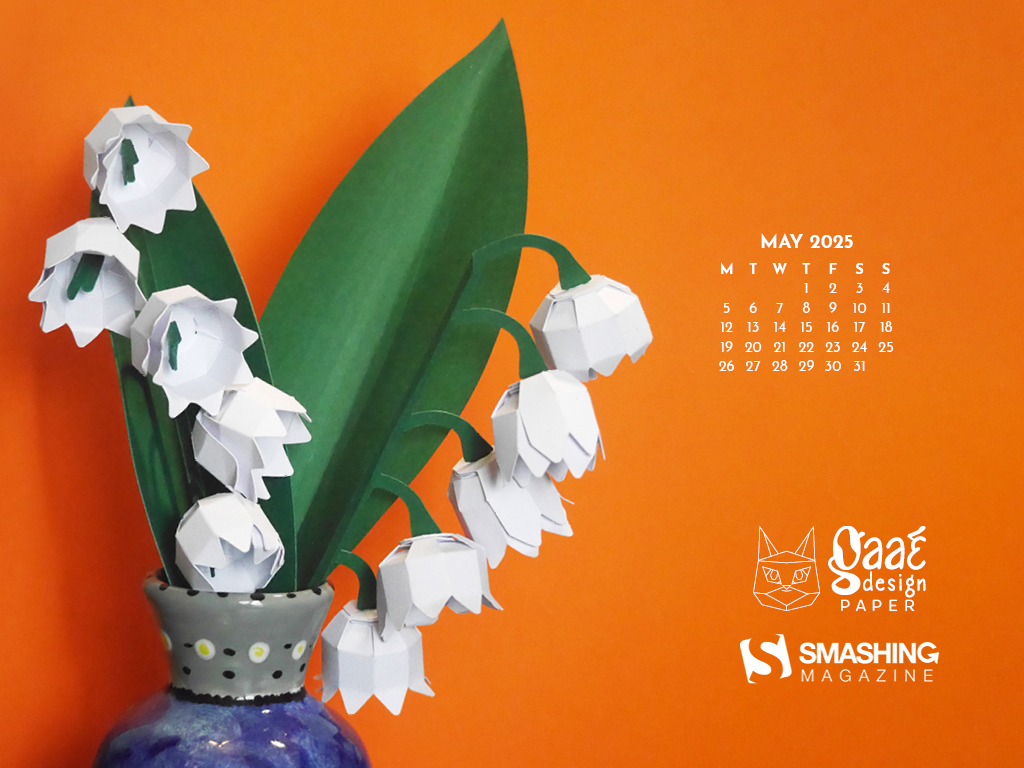
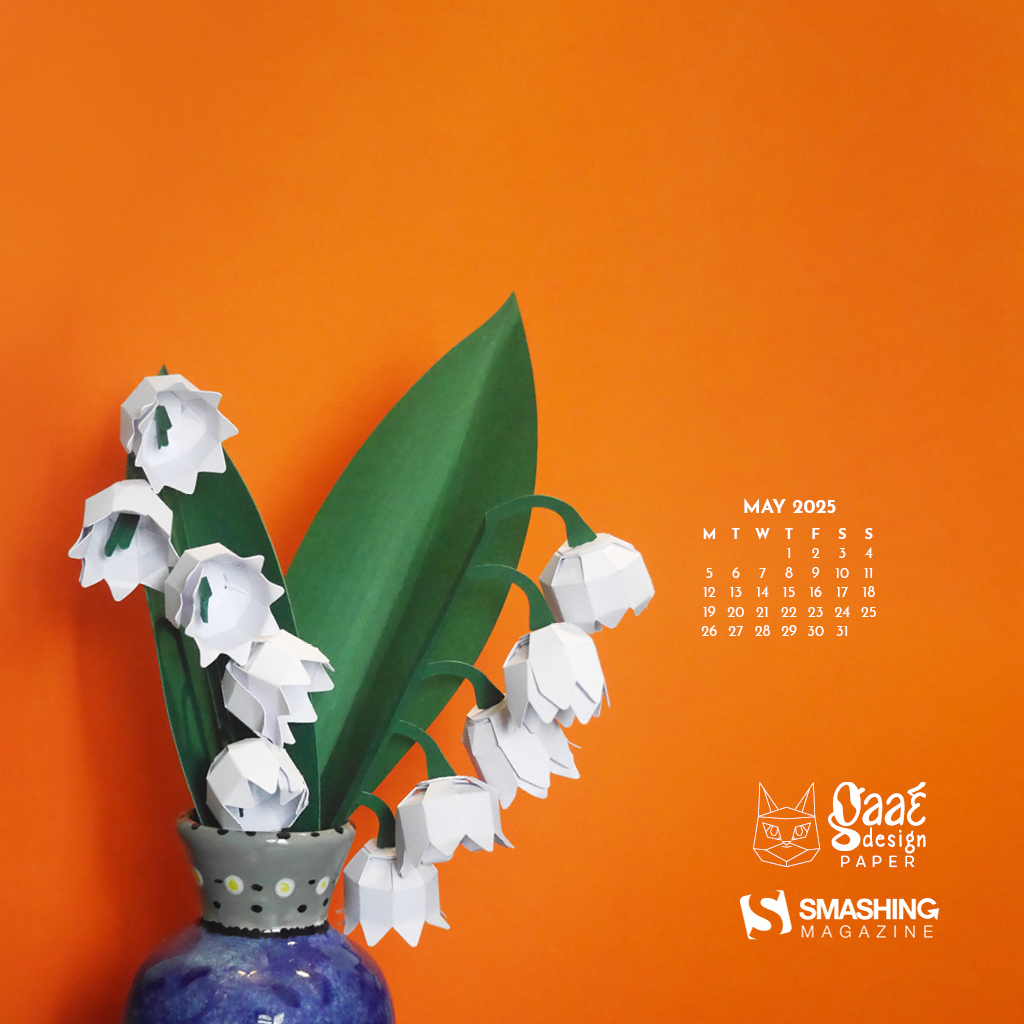
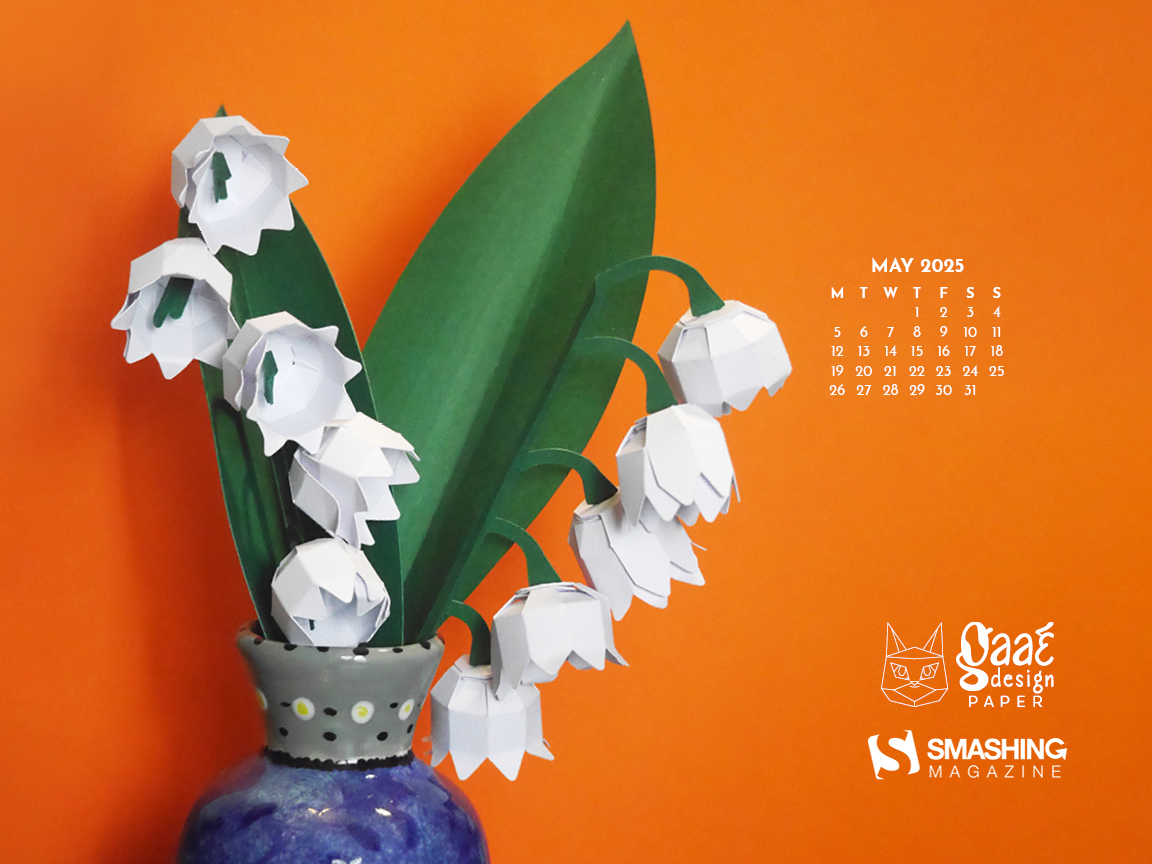
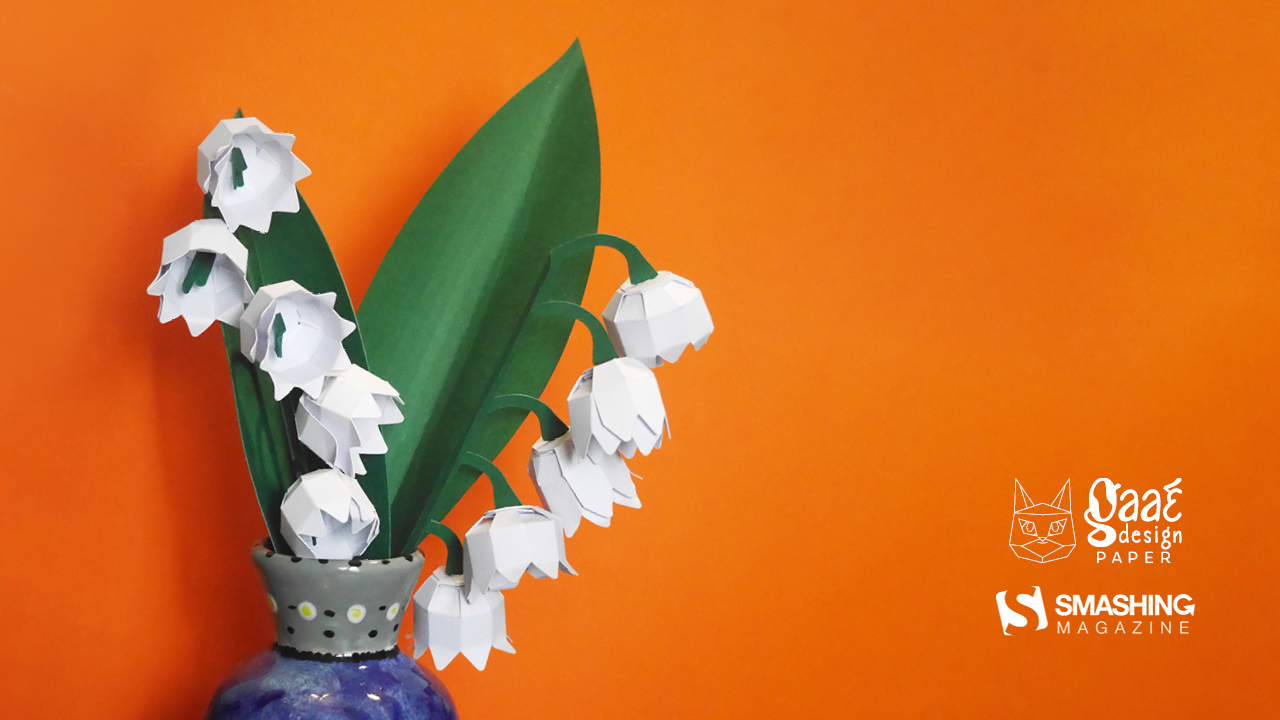
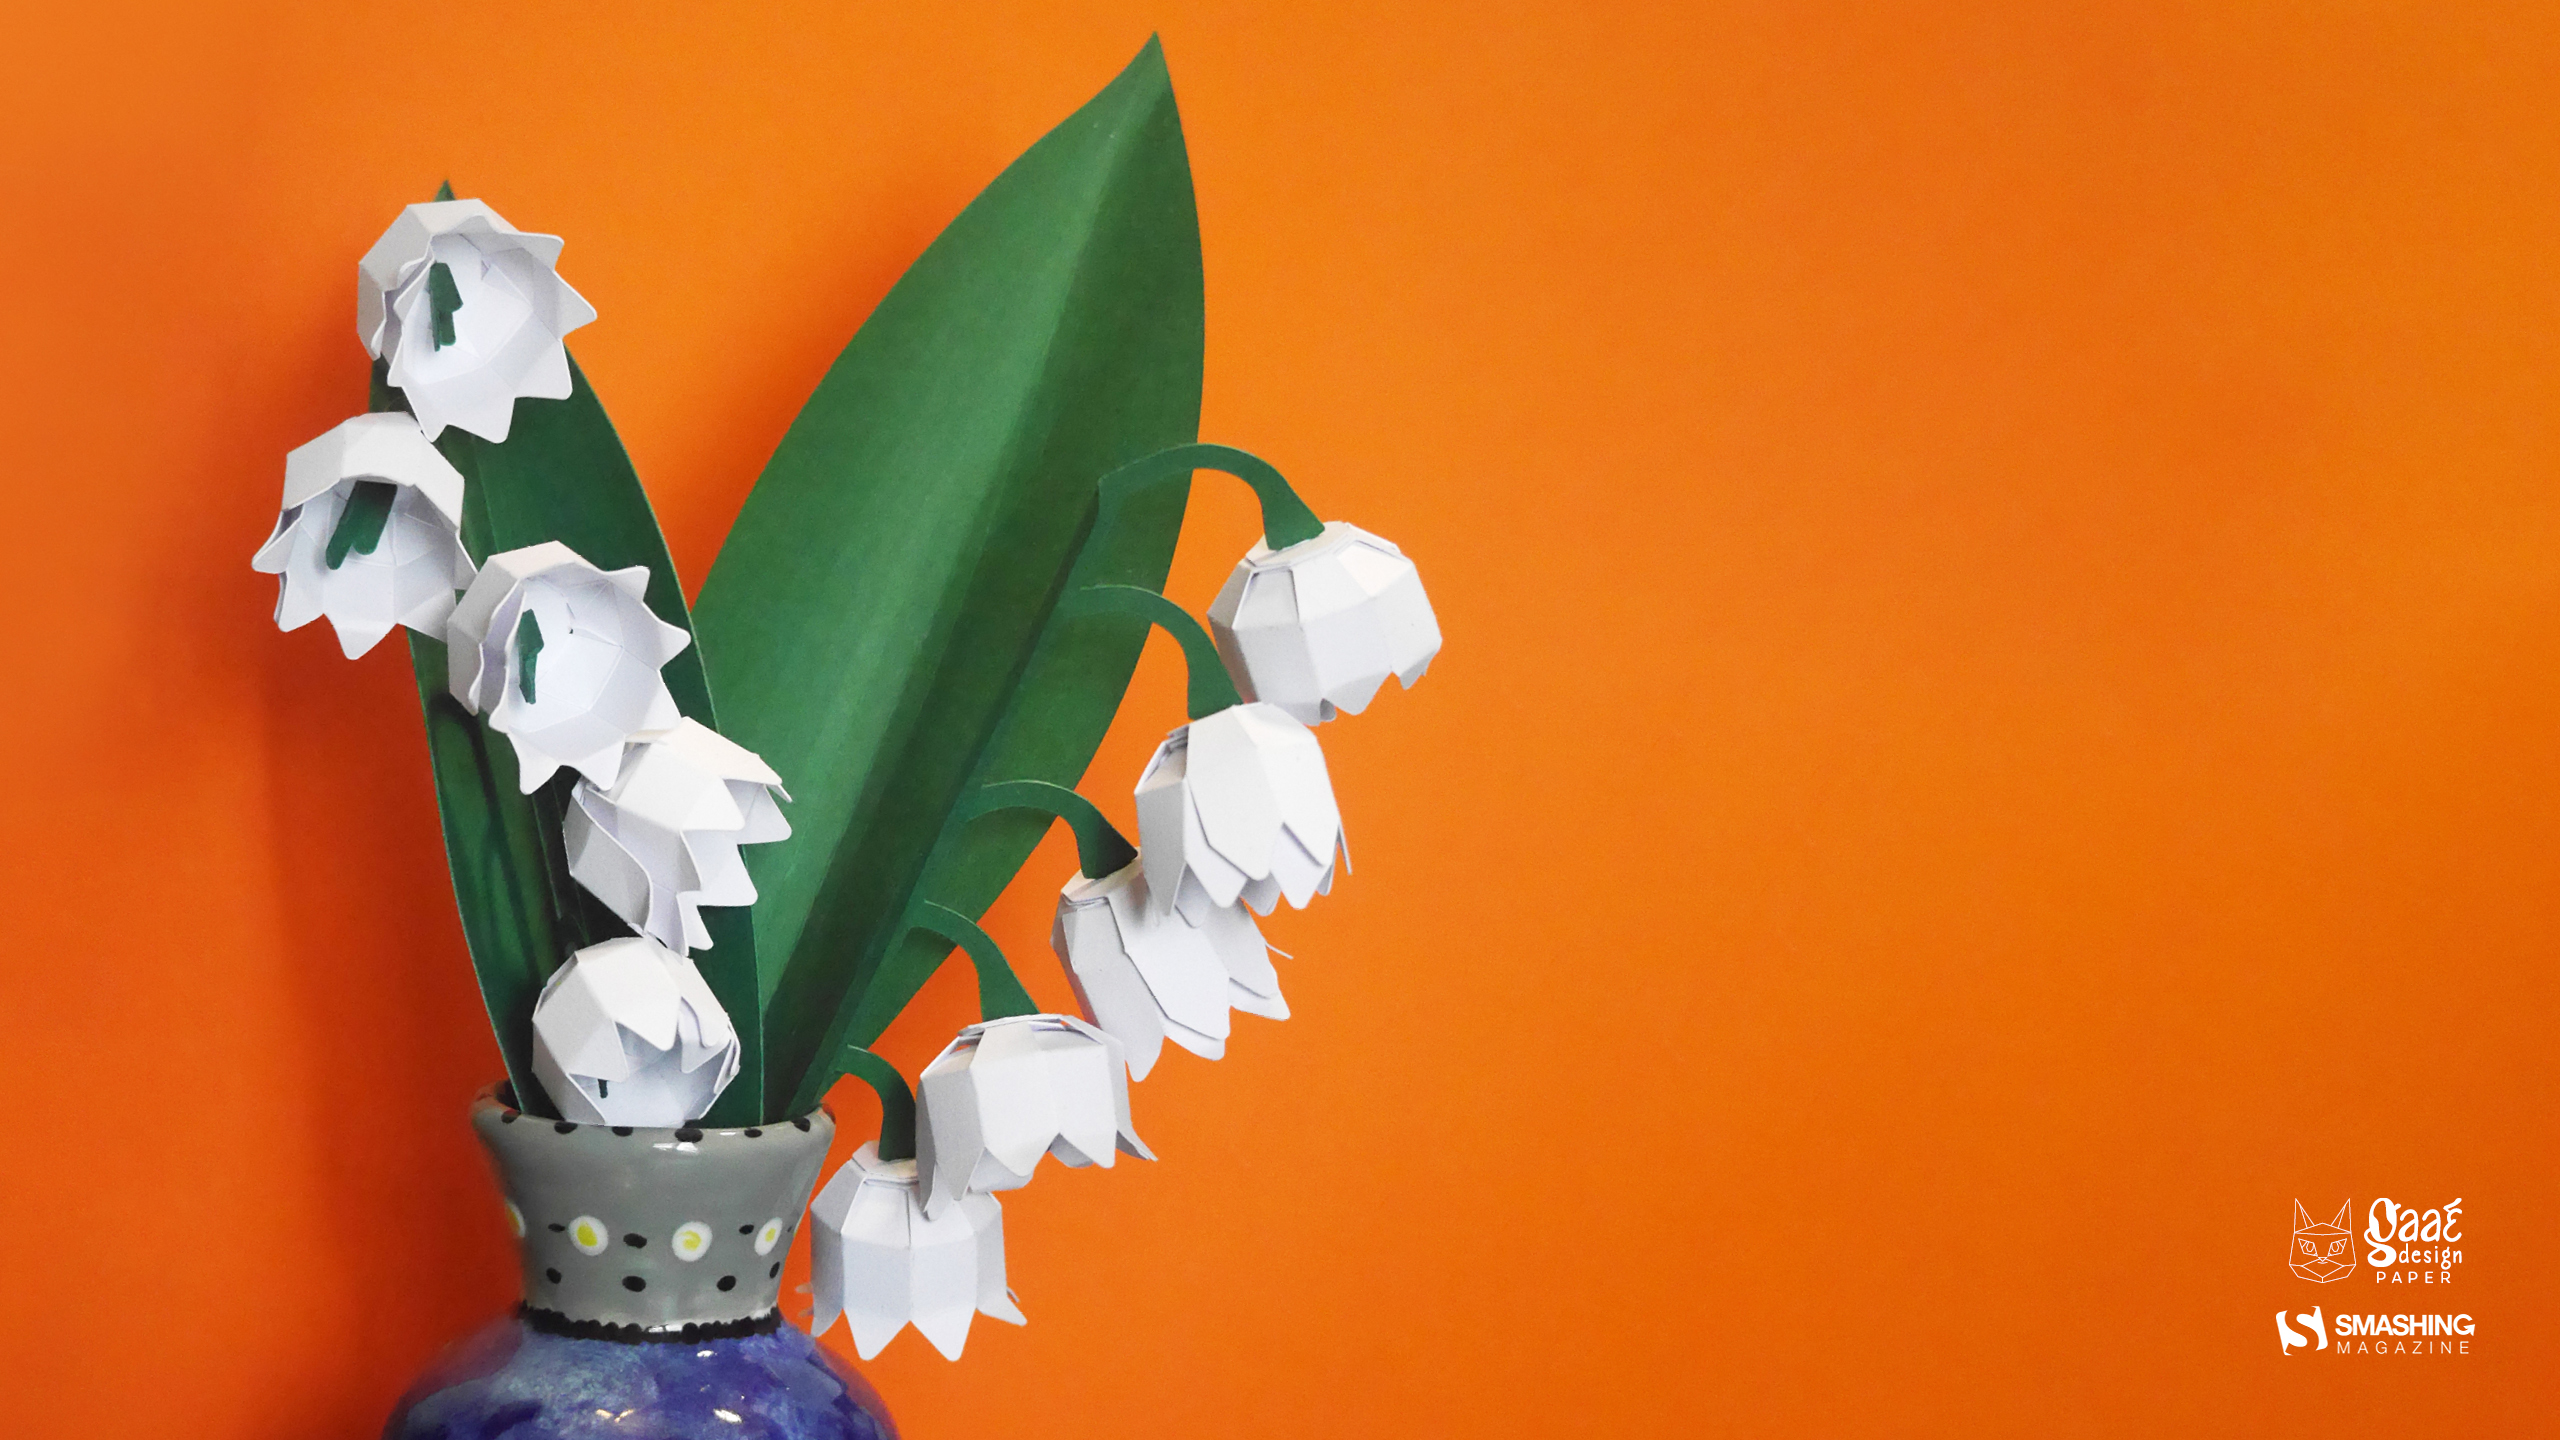
    Lily Of The Valley

    “In May, a very particular flower blooms, adorning the fields with little white bells. Associated with the first of May in France (‘la fête du travail’), the Lily of the Valley (‘muguet’ in French) is a very recognizable plant, and this one is entirely made of paper in the traditional papercraft art, without any glue, respecting nature in every way.” — Designed by Caroline Boire from France.

    • preview
    • with calendar: 320×480, 640×480, 800×480, 800×600, 1024×768, 1024×1024, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1400×1050, 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440
    • without calendar: 320×480, 640×480, 800×480, 800×600, 1024×768, 1024×1024, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1400×1050, 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440

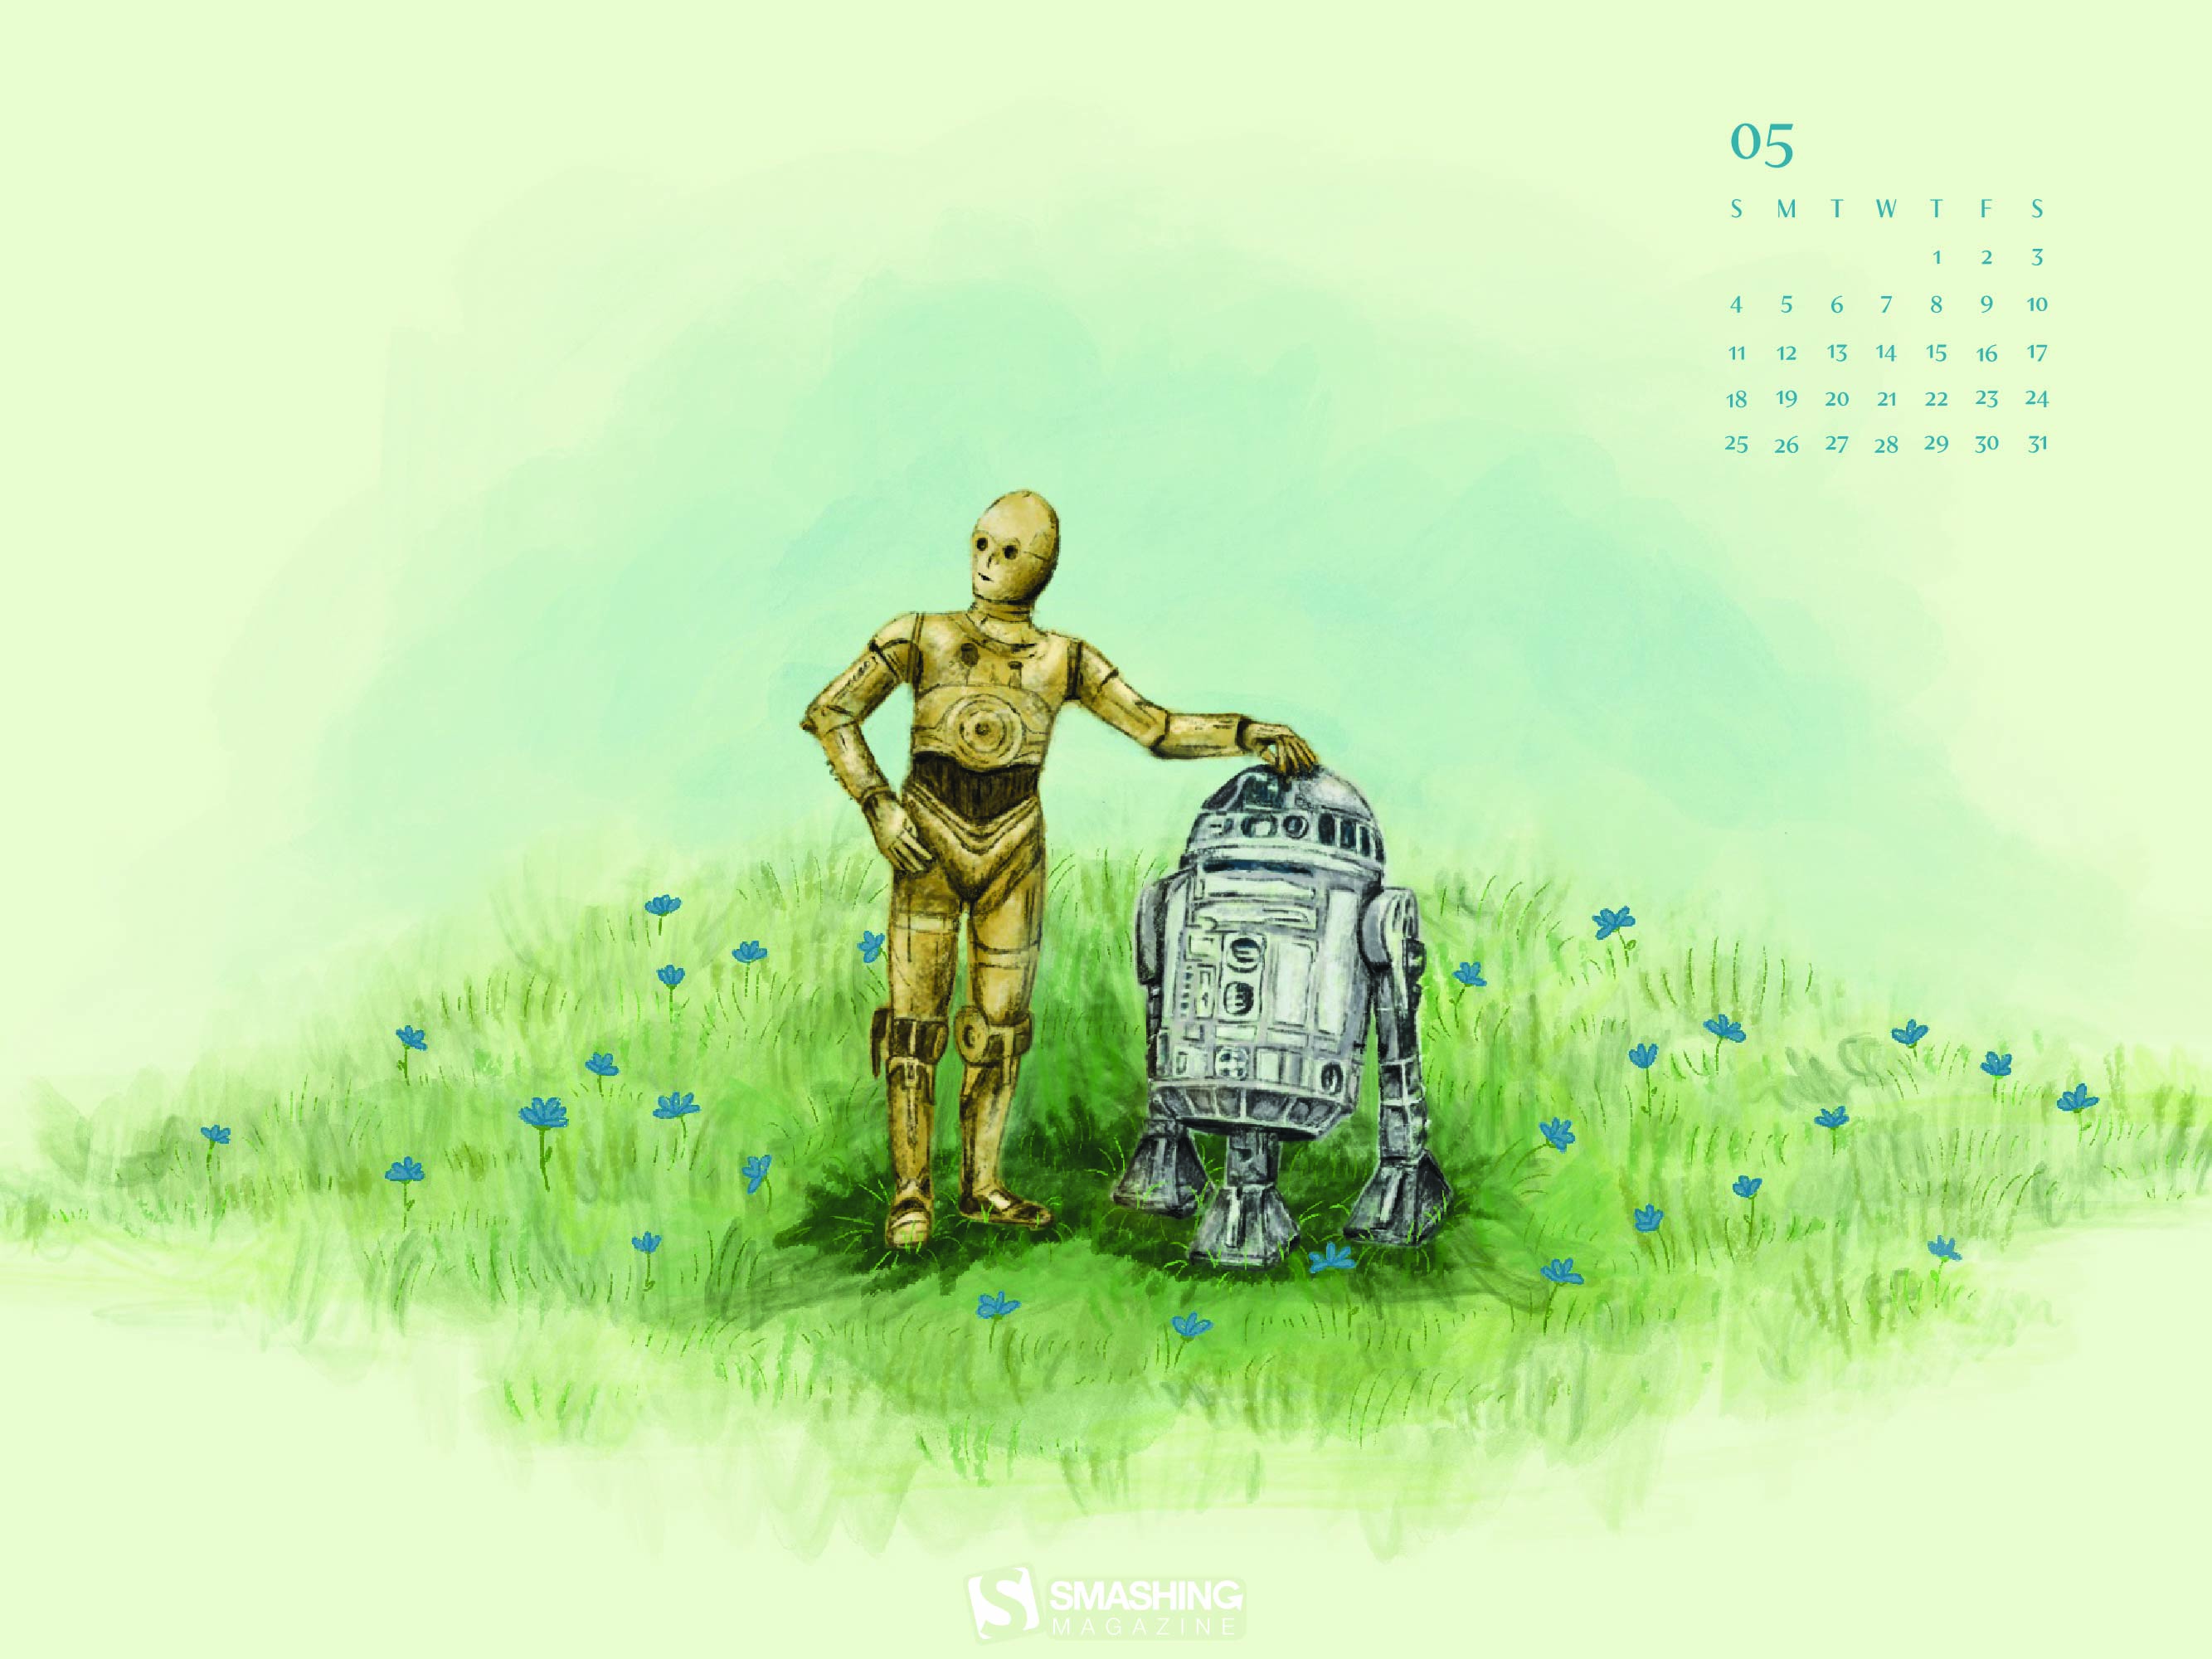
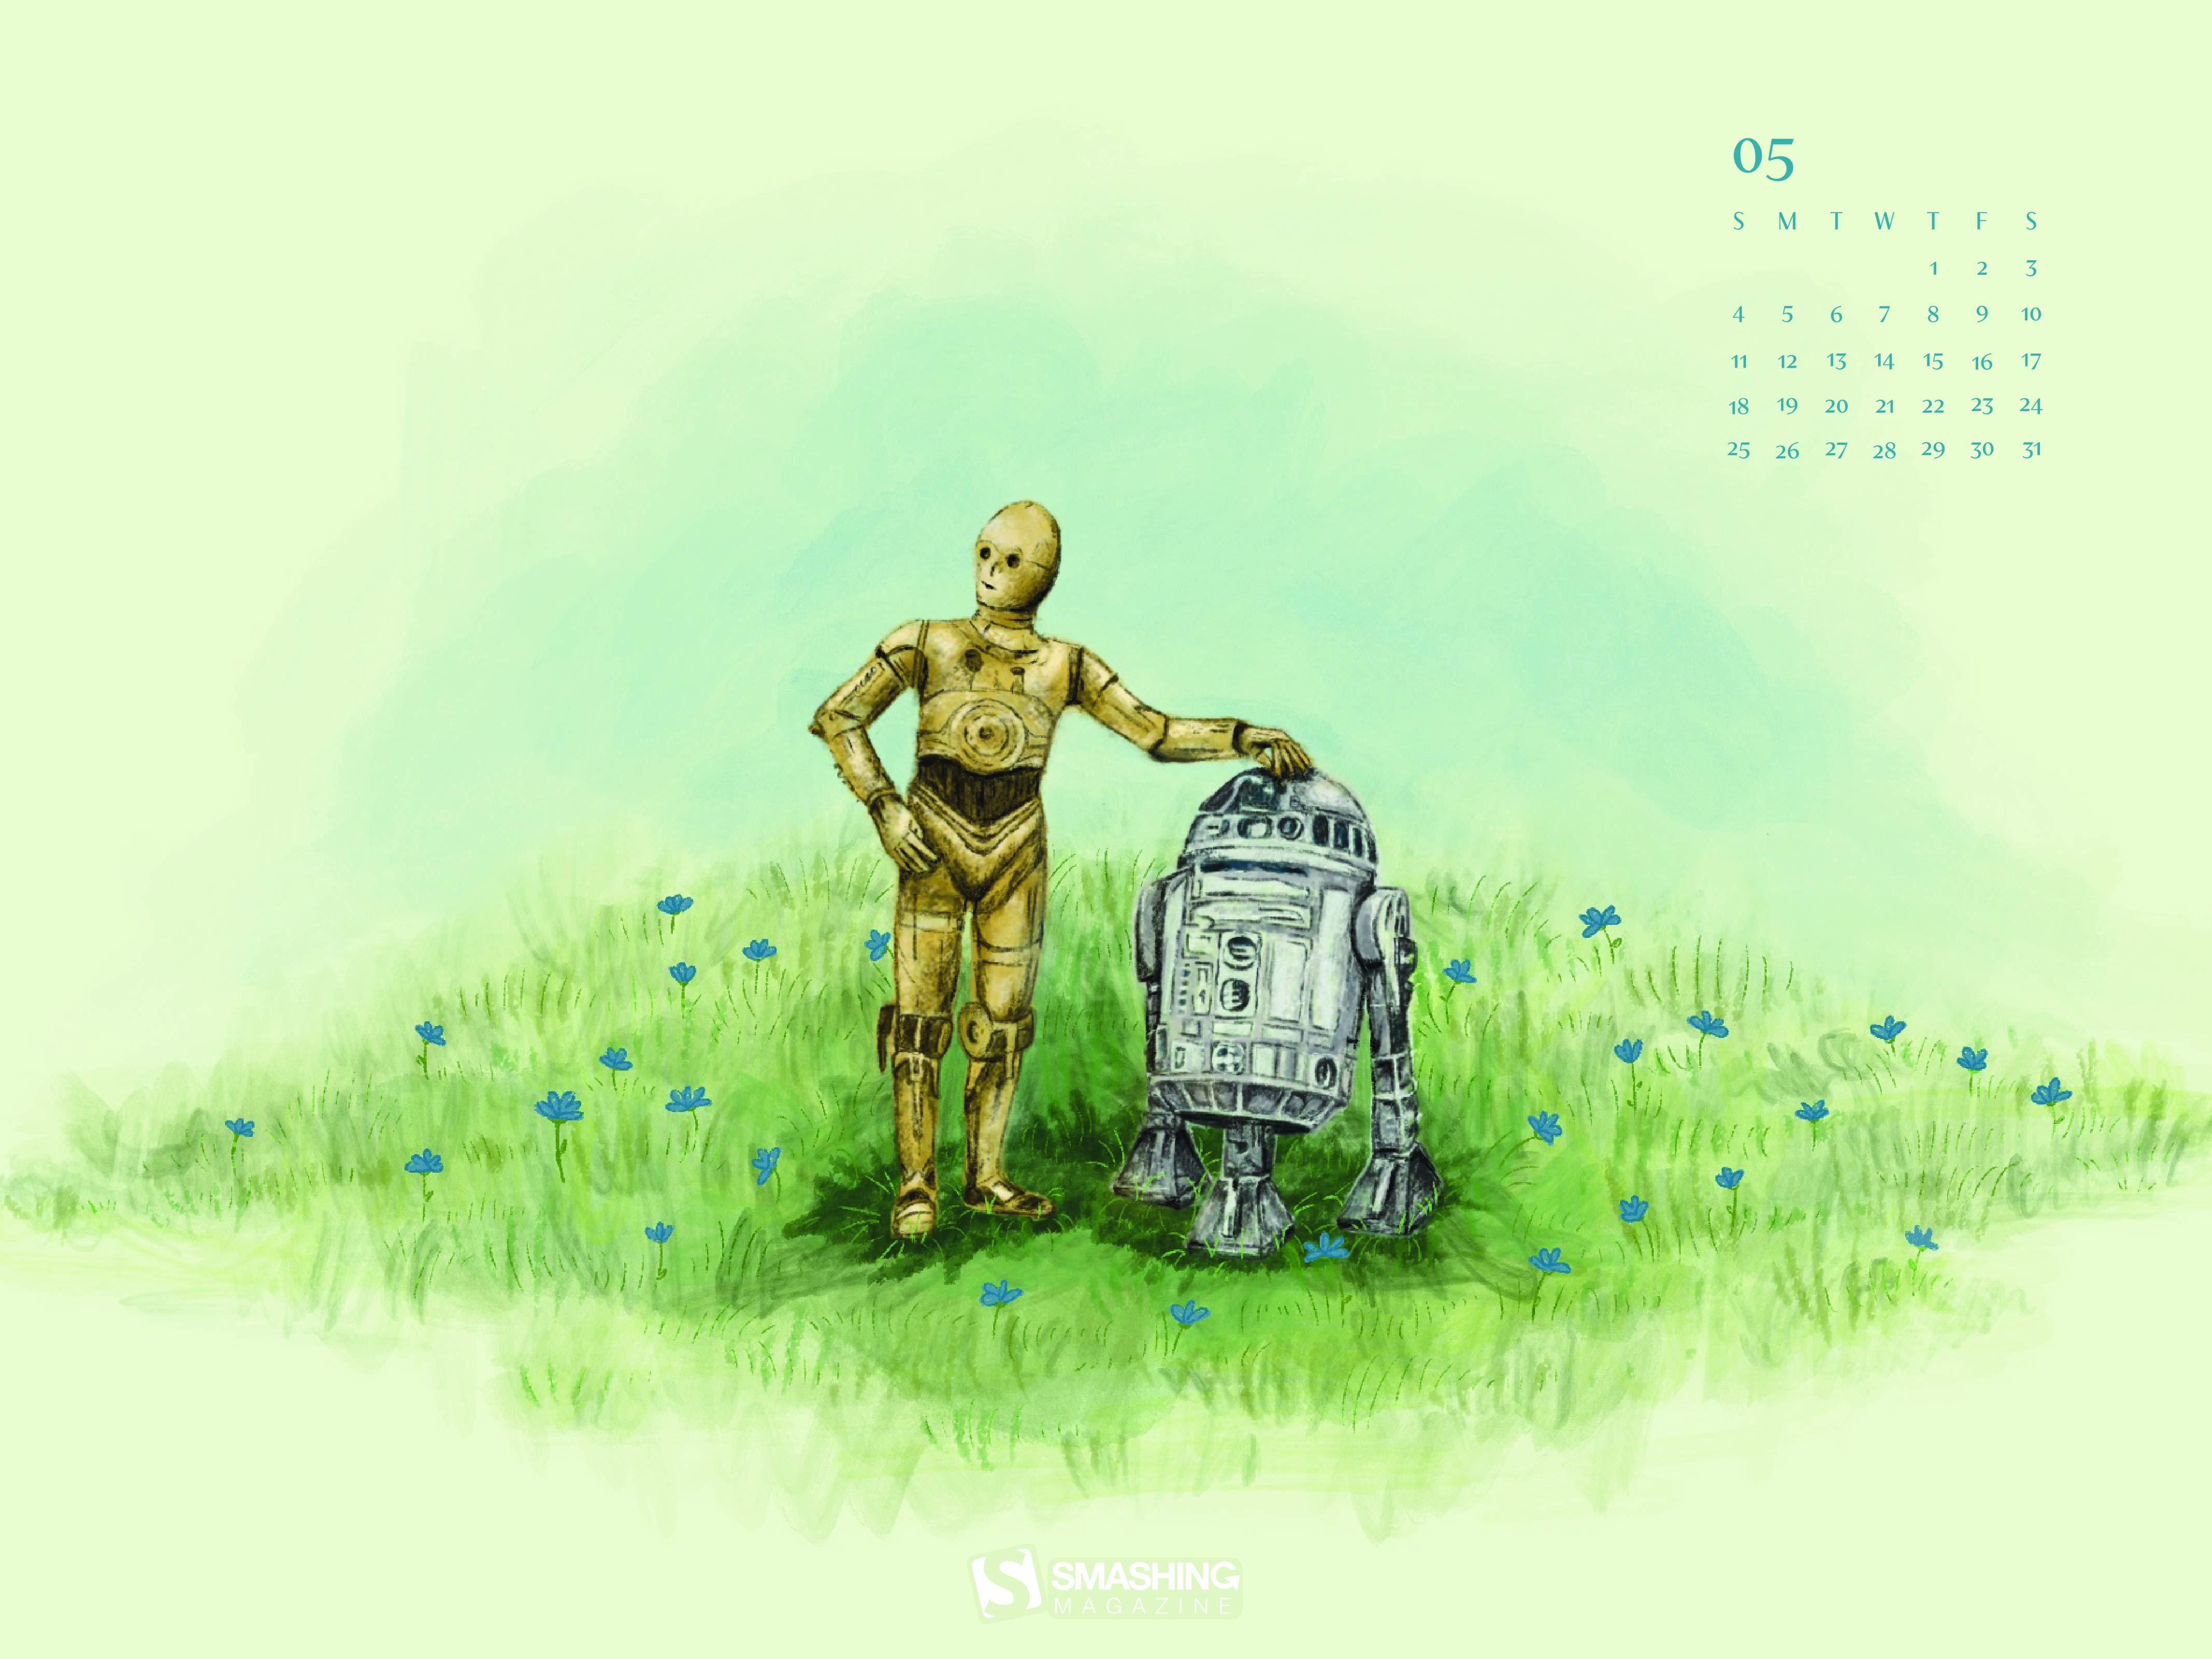
    May The Fourth Be With You

    “I love Star Wars and spring! I chose to combine those aesthetics to create a minimal wallpaper design for those who wanted a sweet memory of C3PO and R2D2. Culturally, I believe Star Wars is huge both nationally and internationally and teaches loads of good lessons, so what better theme to pull from! I also enjoy hand-drawn elements, so I drew this image with charcoal brushes in Procreate and then dropped it in as a jpeg.” — Designed by Chloe Mills from Texas, United States.

    • preview
    • with calendar: 640×480, 1024×768, 1152×864, 1280×800, 1280×1024, 1440×900, 1680×1200, 1920×1200, 2560×1440
    • without calendar: 640×480, 1024×768, 1152×864, 1280×800, 1280×1024, 1440×900, 1680×1200, 1920×1200, 2560×1440

    Ladies And Gentlemen

    Designed by Ricardo Gimenes from Spain.

    • preview
    • with calendar: 640×480, 800×480, 800×600, 1024×768, 1024×1024, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1366×768, 1400×1050, 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440, 3840×2160
    • without calendar: 640×480, 800×480, 800×600, 1024×768, 1024×1024, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1366×768, 1400×1050, 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440, 3840×2160

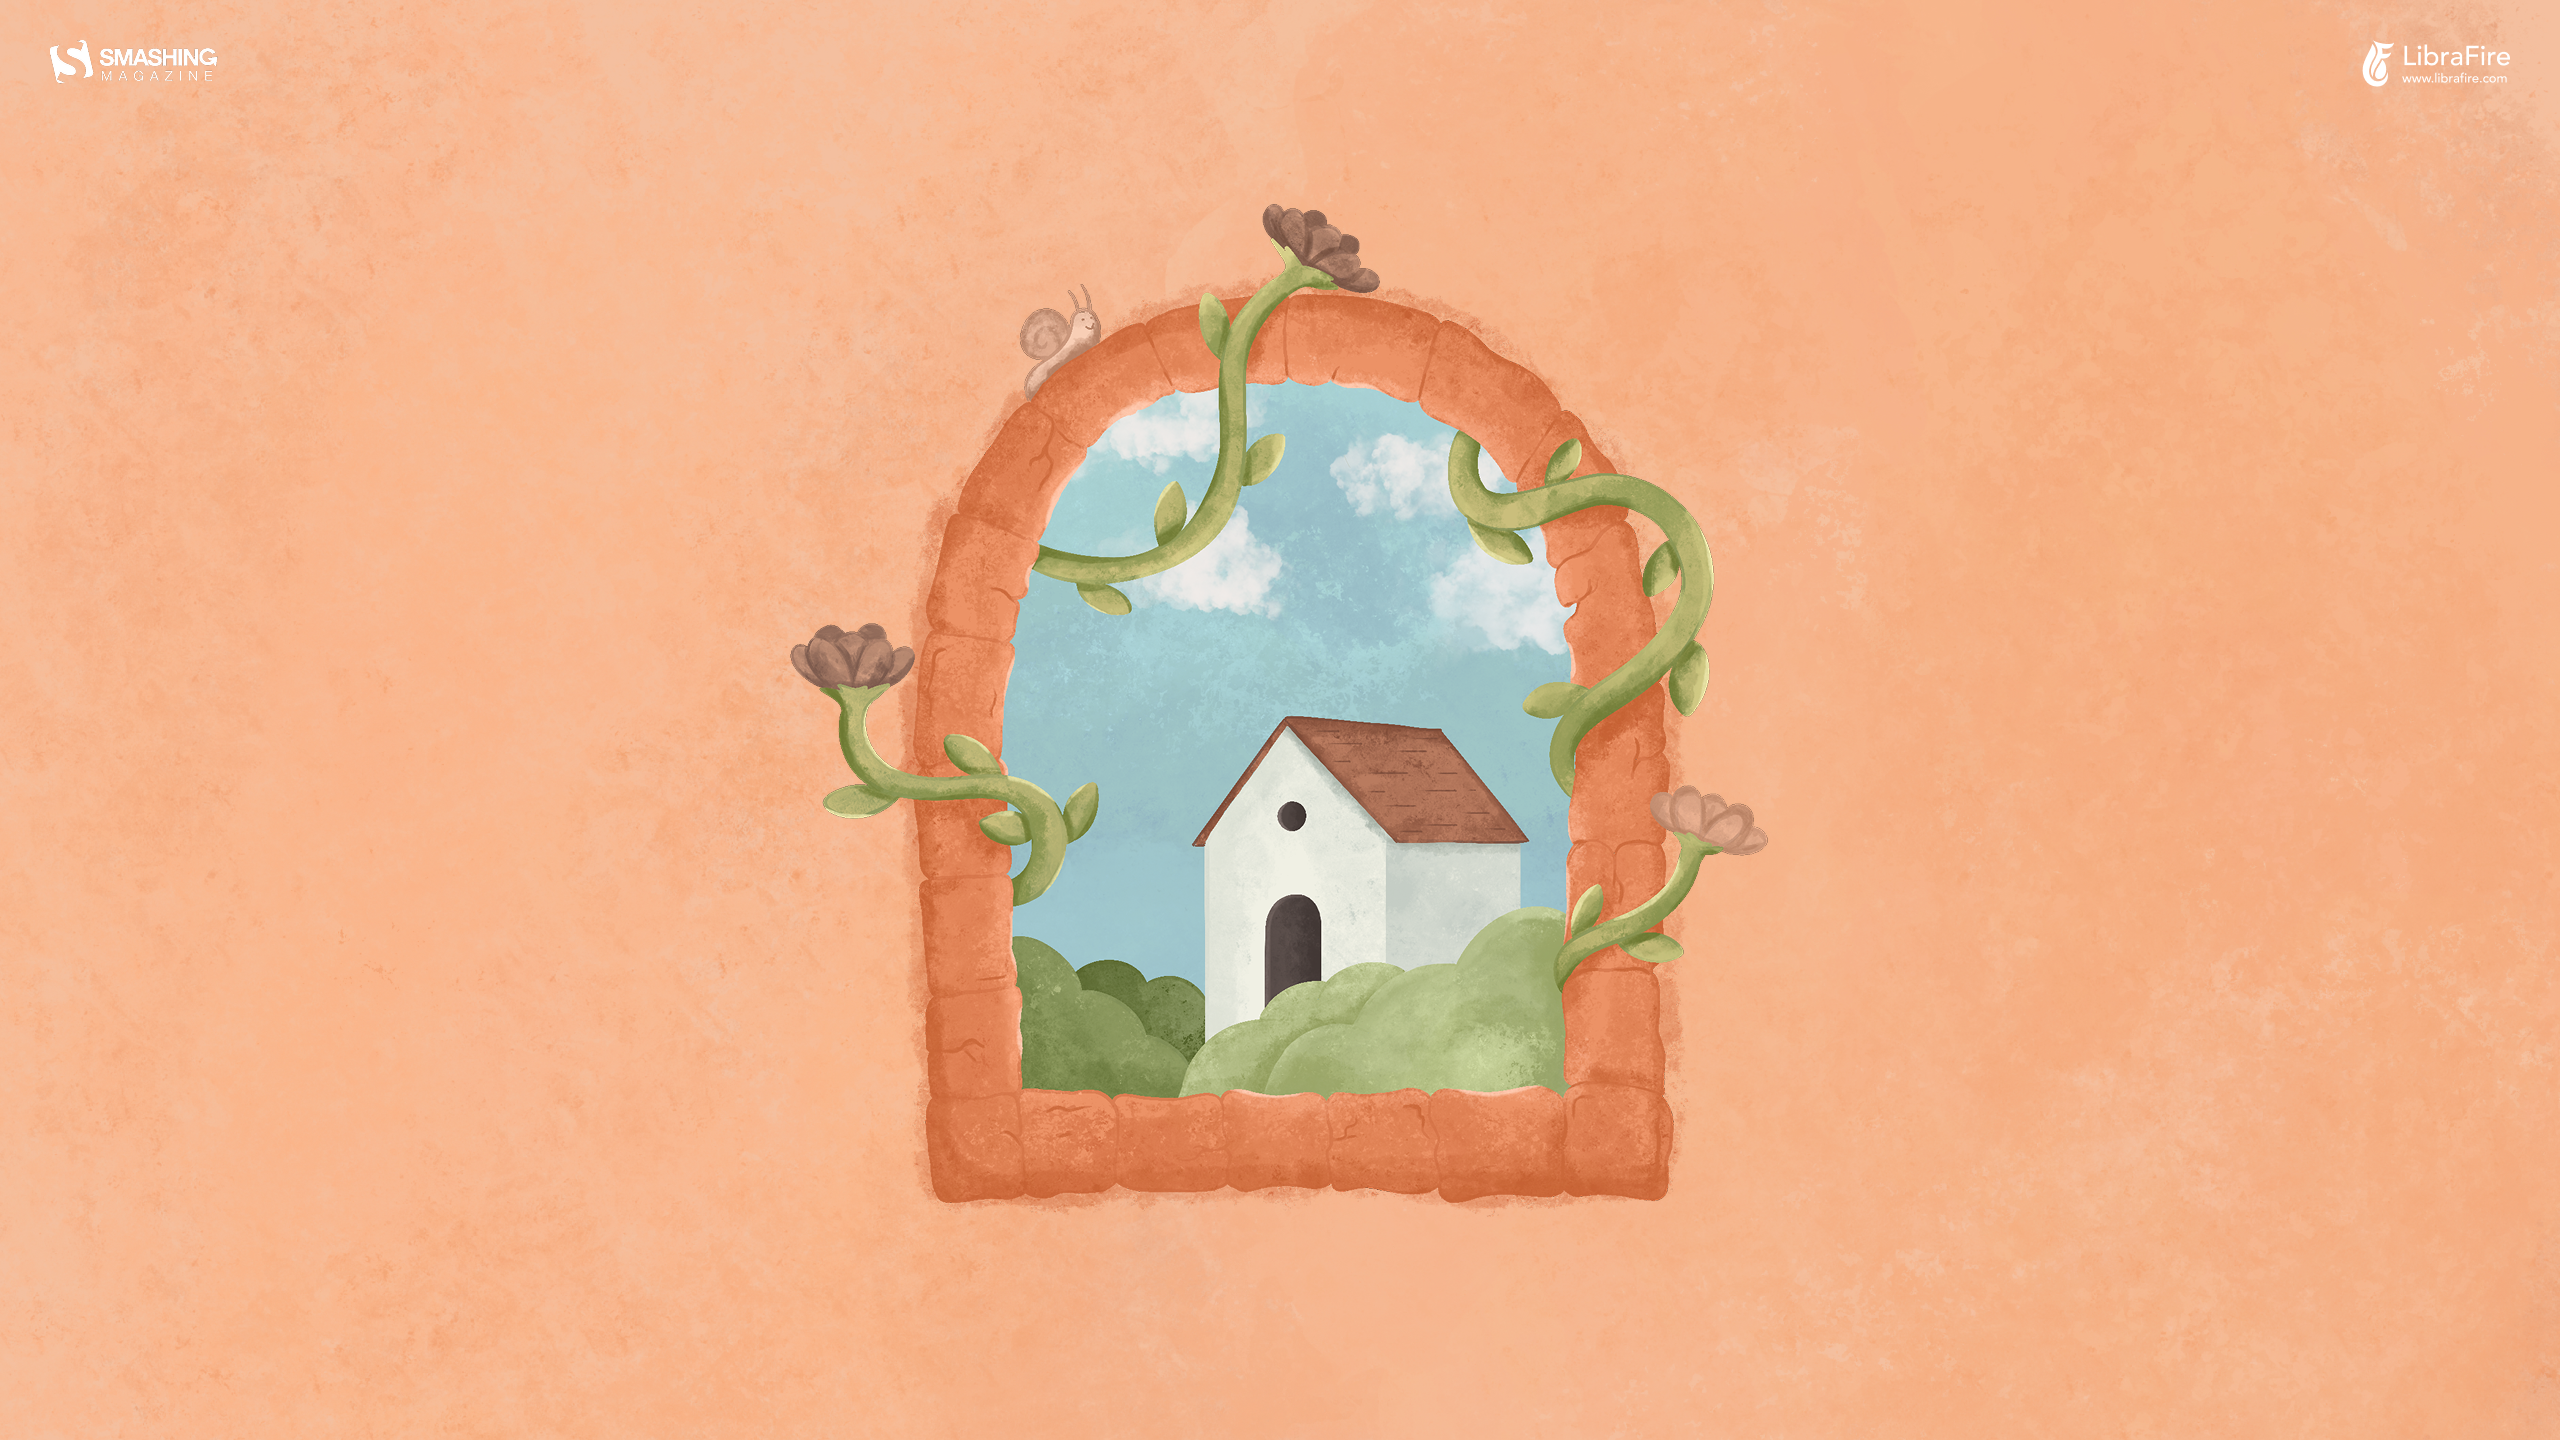
    Through The Castle’s Eye

    “Through a crumbling castle window, nature weaves its way back — framing a white house, green trees, and soft skies. A peaceful glimpse of history and new life intertwined.” — Designed by LibraFire from Serbia.

    • preview
    • with calendar: 320×480, 640×480, 800×480, 800×600, 1024×768, 1024×1024, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1366×768, 1400×1050, 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440
    • without calendar: 320×480, 640×480, 800×480, 800×600, 1024×768, 1024×1024, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1366×768, 1400×1050, 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440

    Crayfish Party

    Designed by Ricardo Gimenes from Spain.

    • preview
    • with calendar: 640×480, 800×480, 800×600, 1024×768, 1024×1024, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1366×768, 1400×1050, 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440, 3840×2160
    • without calendar: 640×480, 800×480, 800×600, 1024×768, 1024×1024, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1366×768, 1400×1050, 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440, 3840×2160

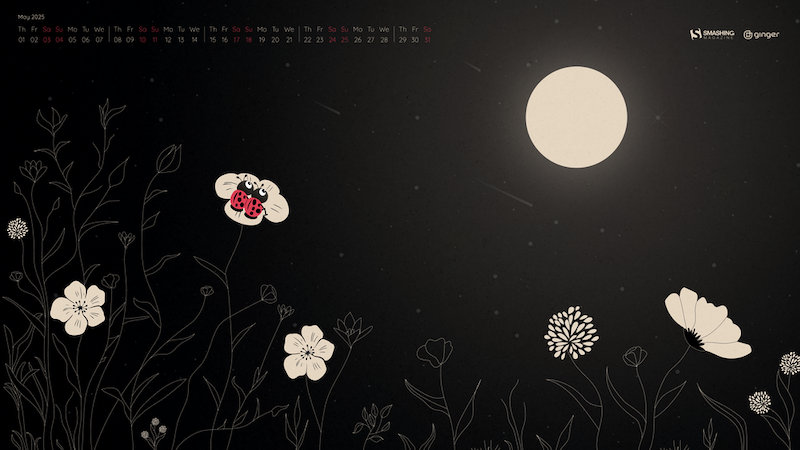
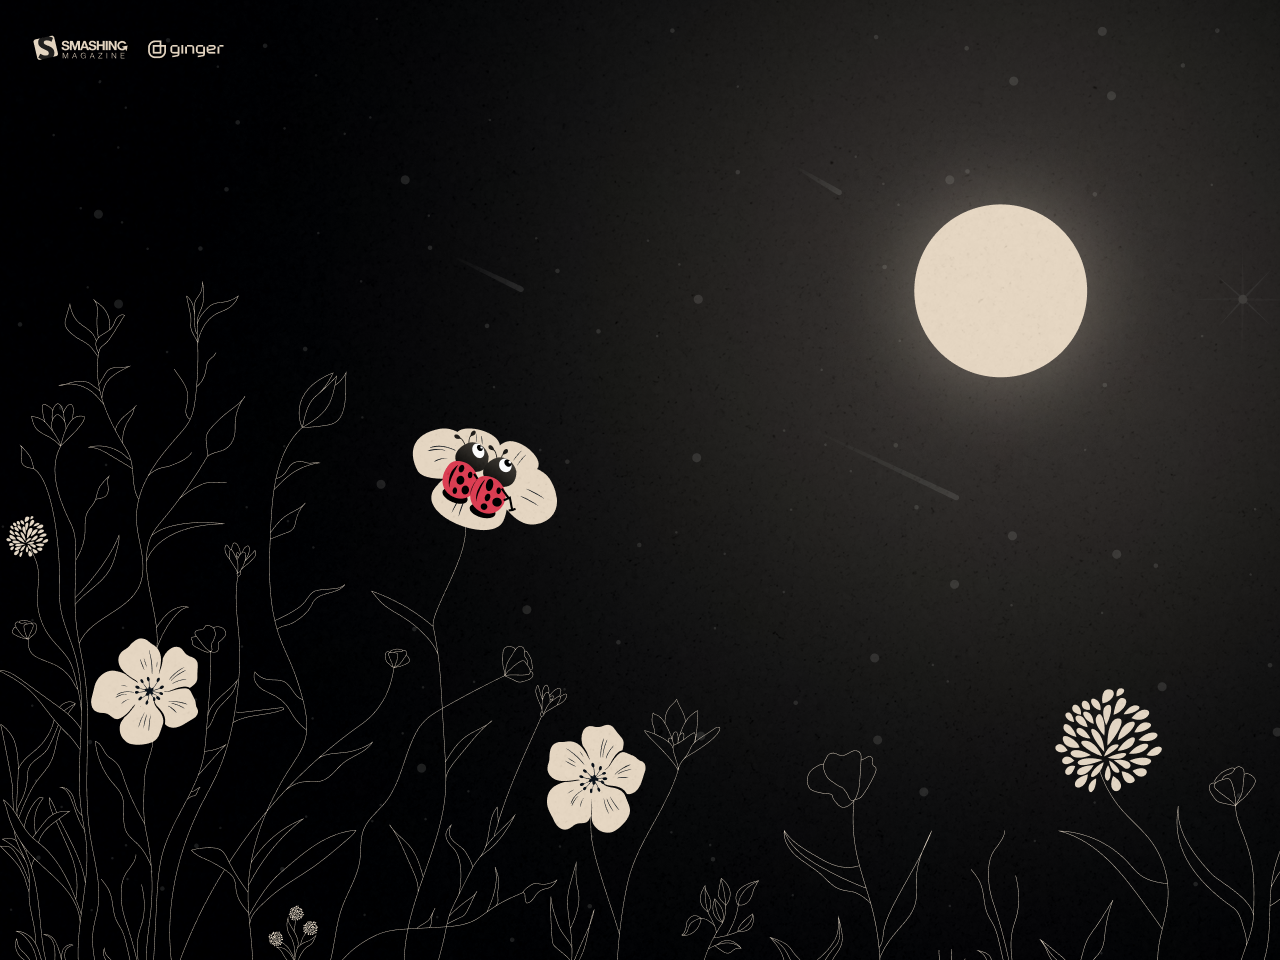
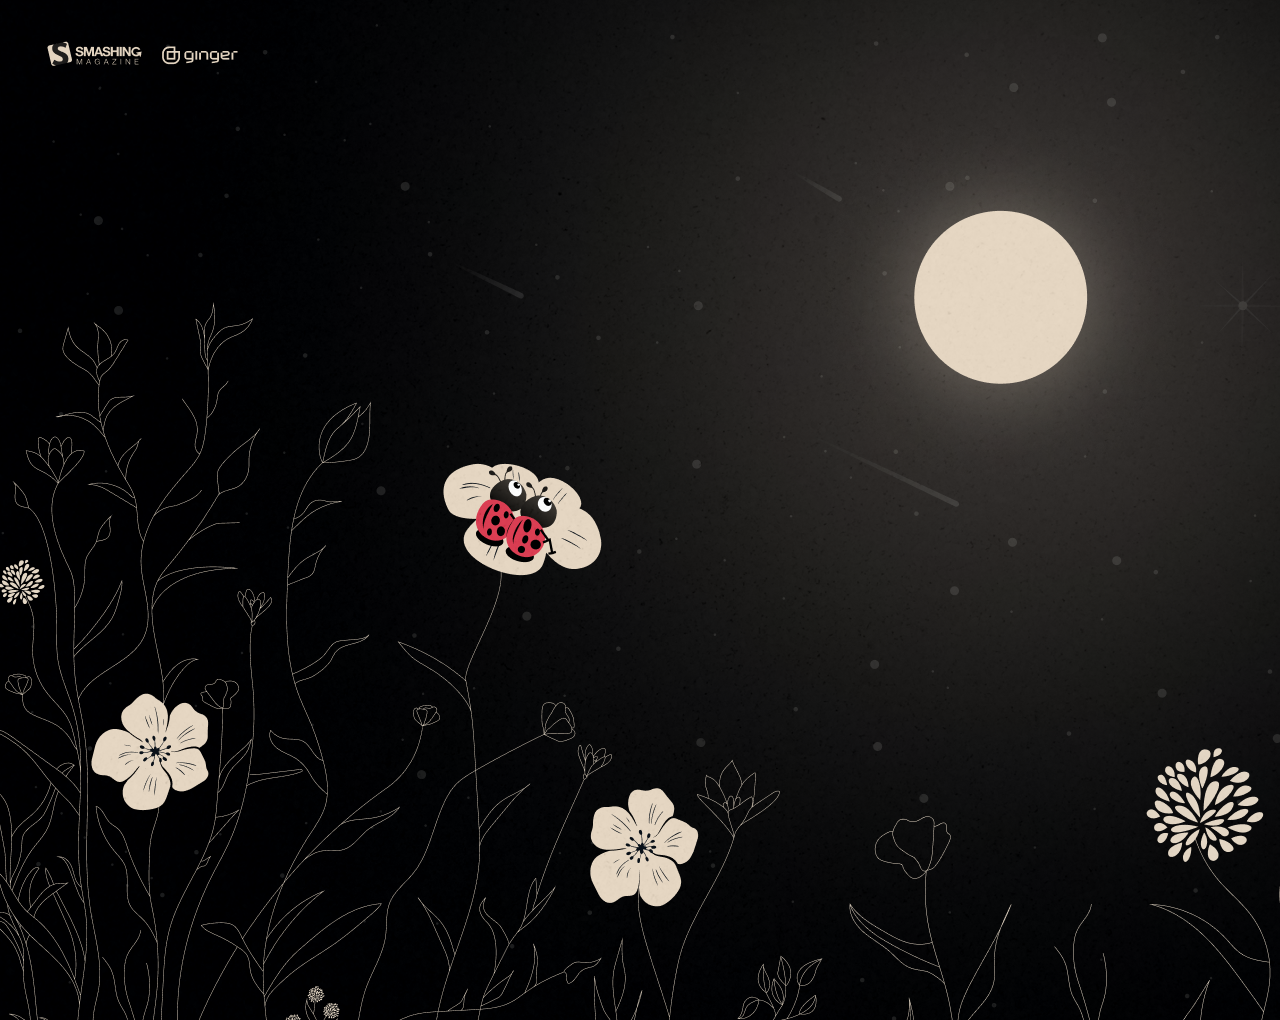
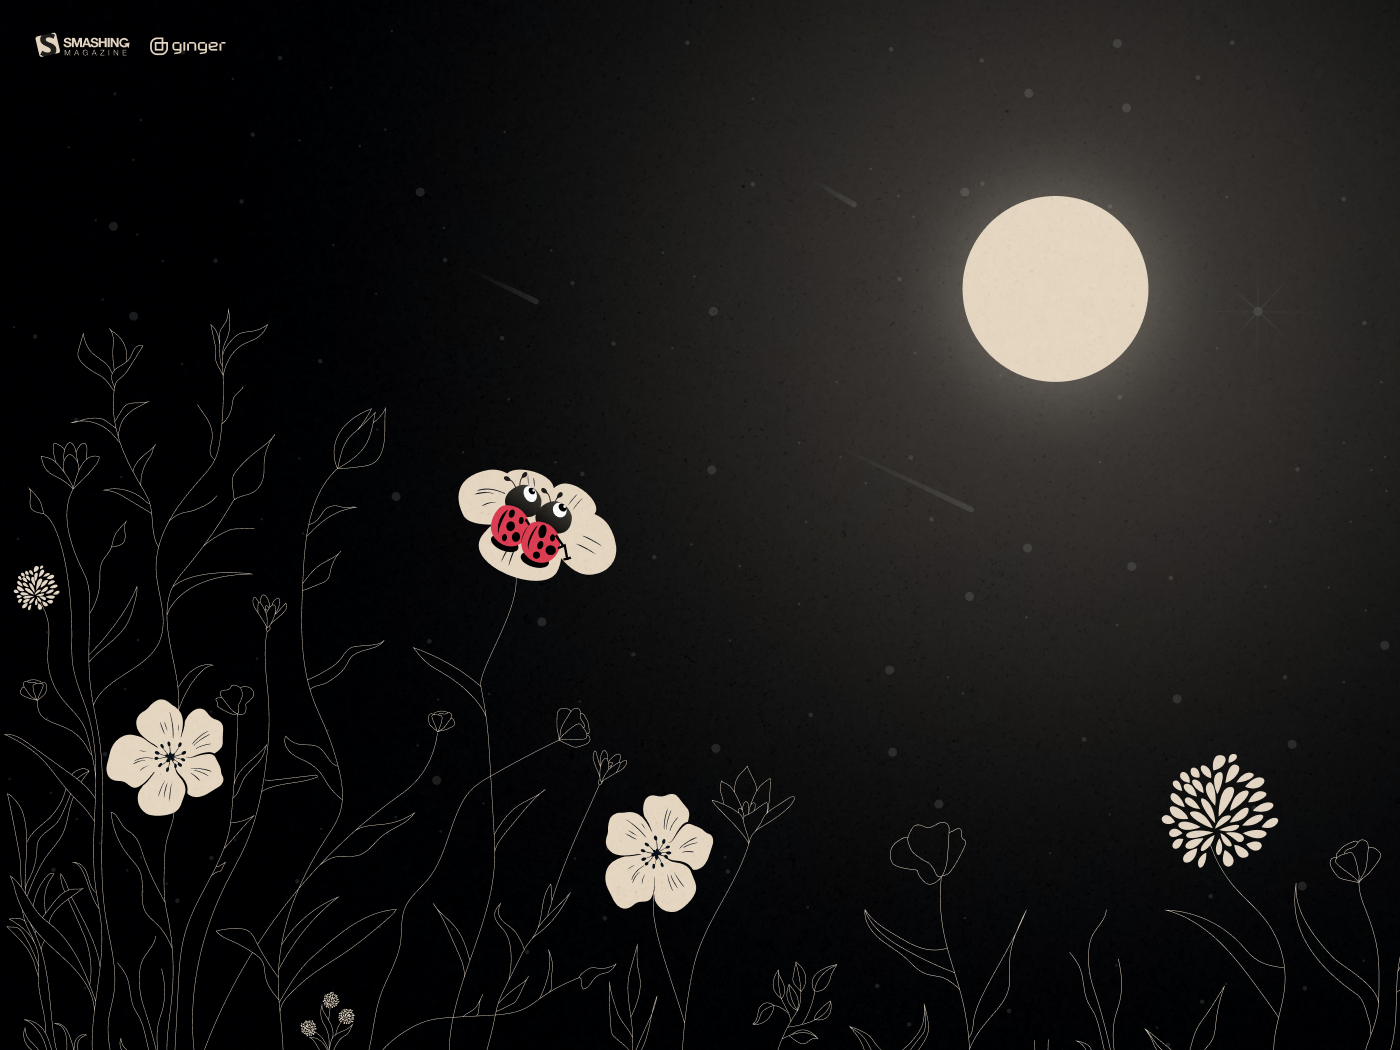
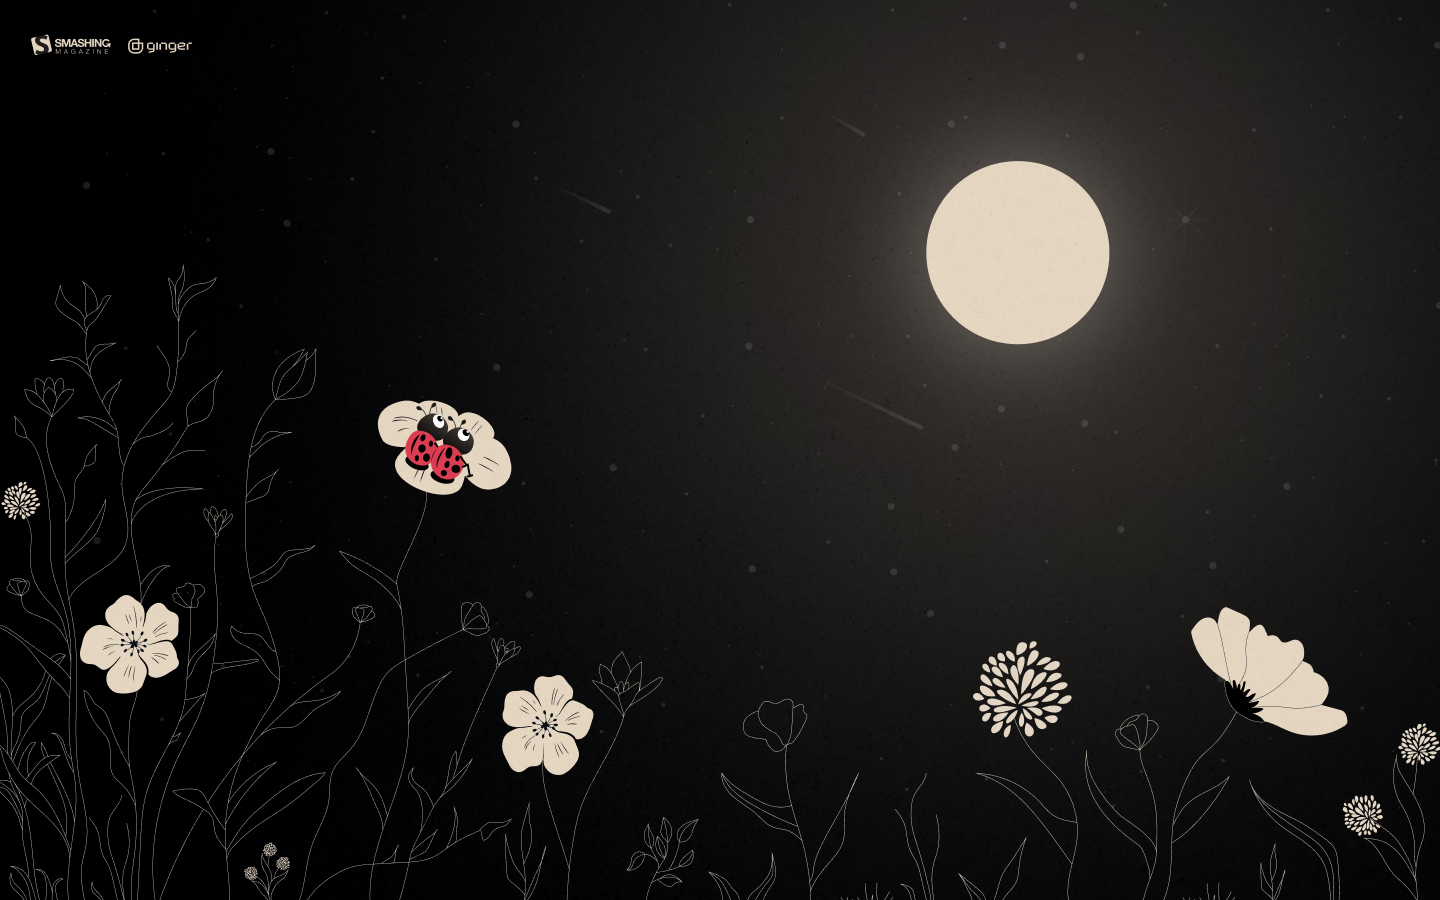
    Under The Flower Moon

    “Two ladybugs sat quietly on a flower, watching the Flower Moon rise high above. It was May, the time when blossoms wake and the moon whispers of new beginnings. Together, they listened.” — Designed by Ginger IT Solutions from Serbia.

    • preview
    • with calendar: 320×480, 640×480, 800×480, 800×600, 1024×768, 1024×1024, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1400×1050, 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440
    • without calendar: 320×480, 640×480, 800×480, 800×600, 1024×768, 1024×1024, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1400×1050, 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440

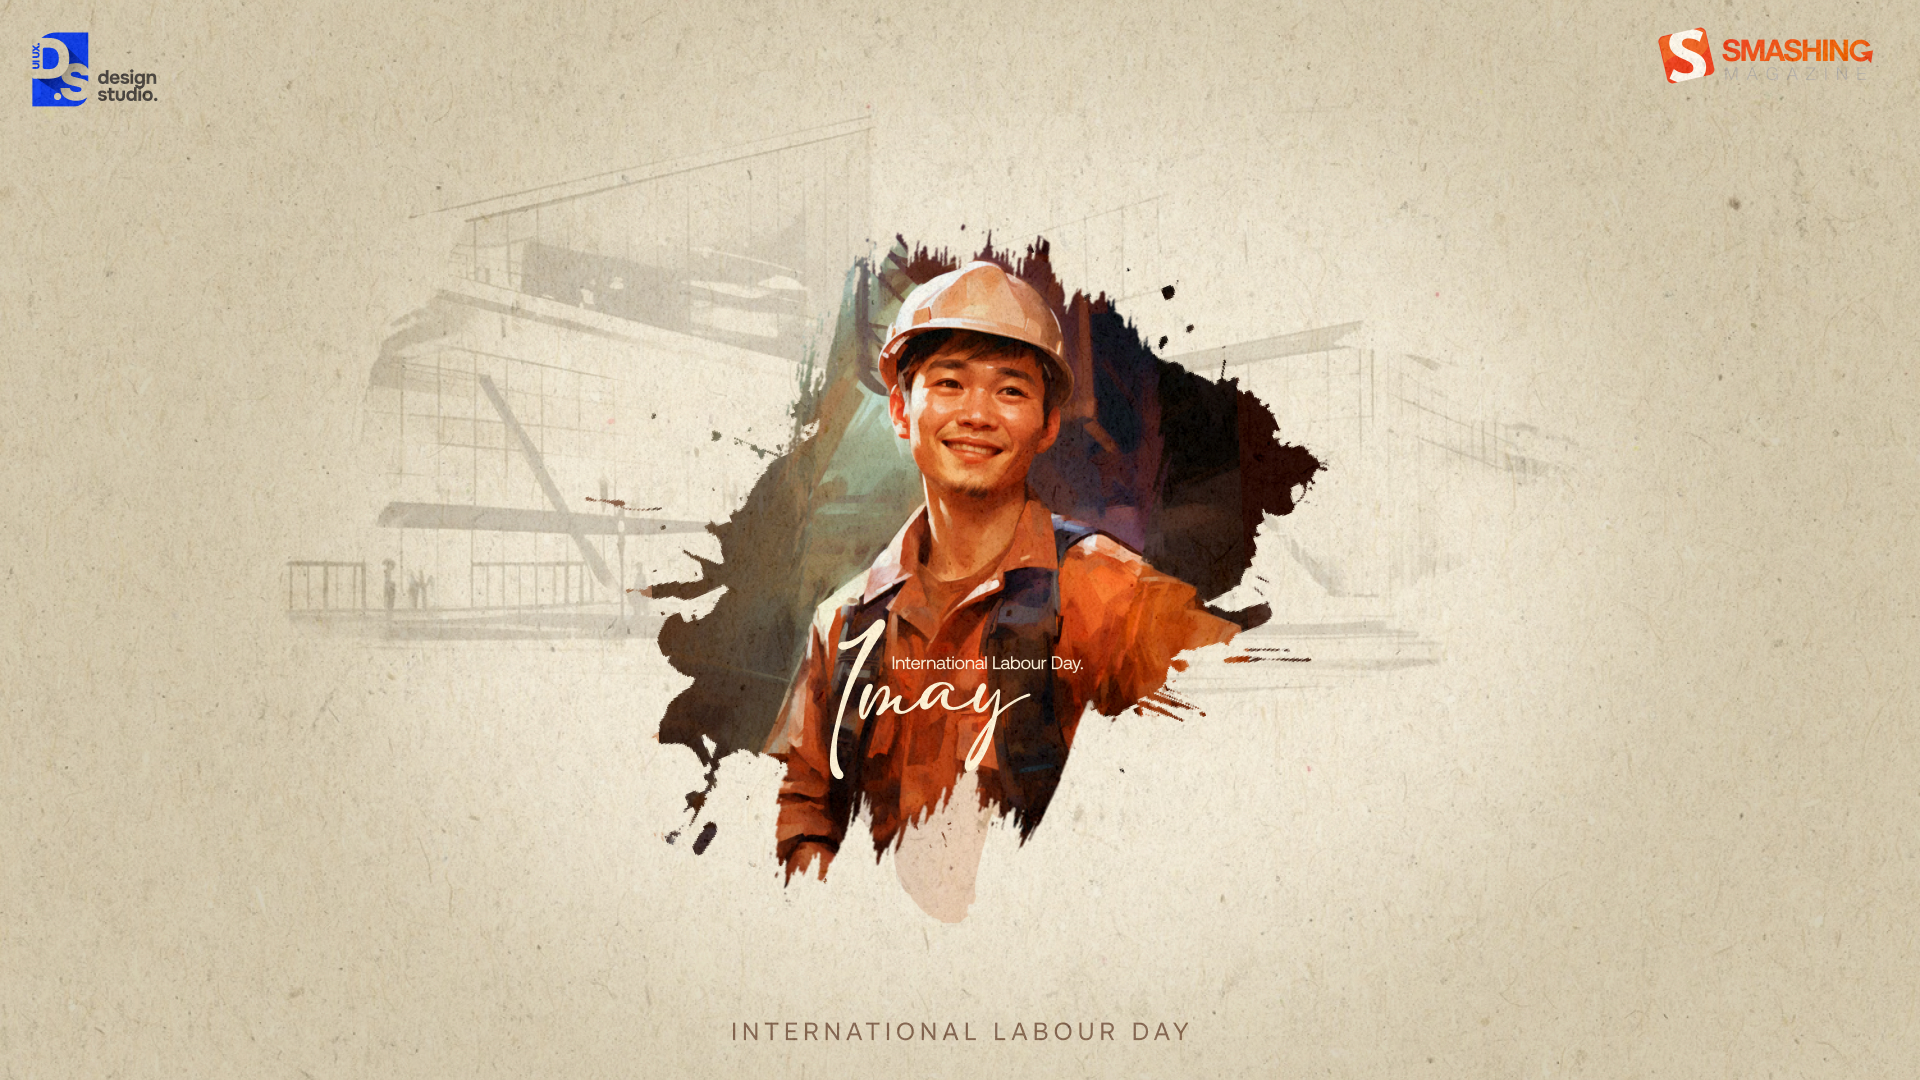
    International Labour Day

    “International Labour Day on May 1 celebrates the contributions and achievements of workers worldwide. Originating from 19th-century labor movements advocating for an eight-hour workday, it highlights the importance of fair wages, safe workplaces, and workers’ rights. Many countries hold events, parades, and rallies to honor this important day.” — Designed by Design Studio from India.

    • preview
    • with calendar: 640×480, 1024×768, 1280×800, 1400×900, 1600×1200, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440
    • without calendar: 640×480, 1024×768, 1280×800, 1400×900, 1600×1200, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440

    Hello May

    “The longing for warmth, flowers in bloom, and new beginnings is finally over as we welcome the month of May. From celebrating nature on the days of turtles and birds to marking the days of our favorite wine and macarons, the historical celebrations of the International Workers’ Day, Cinco de Mayo, and Victory Day, to the unforgettable ‘May the Fourth be with you’. May is a time of celebration — so make every May day count!” — Designed by PopArt Studio from Serbia.

    • preview
    • without calendar: 320×480, 640×480, 800×480, 800×600, 1024×768, 1024×1024, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1366×768, 1440×900, 1440×1050, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440

    Navigating The Amazon

    “We are in May, the spring month par excellence, and we celebrate it in the Amazon jungle.” — Designed by Veronica Valenzuela Jimenez from Spain.

    • preview
    • without calendar: 640×480, 800×480, 1024×768, 1280×720, 1280×800, 1440×900, 1600×1200, 1920×1080, 1920×1440, 2560×1440

    Bat Traffic

    Designed by Ricardo Gimenes from Sweden.

    • preview
    • without calendar: 640×480, 800×480, 800×600, 1024×768, 1024×1024, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1366×768, 1400×1050, 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440, 3840×2160

    Understand Yourself

    “Sunsets in May are the best way to understand who you are and where you are heading. Let’s think more!” — Designed by Igor Izhik from Canada.

    • preview
    • without calendar: 1280×720, 1280×800, 1280×960, 1280×1024, 1400×1050, 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440

    Poppies Paradise

    Designed by Nathalie Ouederni from France.

    • preview
    • without calendar: 320×480, 1024×768, 1280×1024, 1440×900, 1680×1200, 1920×1200, 2560×1440

    The Mushroom Band

    “My daughter asked me to draw a band of mushrooms. Here it is!” — Designed by Vlad Gerasimov from Georgia.

    • preview
    • without calendar: 800×480, 800×600, 1024×600, 1024×768, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1366×768, 1400×1050, 1440×900, 1440×960, 1600×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440, 2560×1600, 2880×1800, 3072×1920, 3840×2160, 5120×2880

    April Showers Bring Magnolia Flowers

    “April and May are usually when everything starts to bloom, especially the magnolia trees. I live in an area where there are many and when the wind blows, the petals make it look like snow is falling.” — Designed by Sarah Masucci from the United States.

    • preview
    • without calendar: 320×480, 640×480, 800×480, 800×600, 1024×768, 1024×1024, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1400×1050, 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440

    ARRR2-D2

    Designed by Ricardo Gimenes from Sweden.

    • preview
    • without calendar: 640×480, 800×480, 800×600, 1024×768, 1024×1024, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1366×768, 1400×1050, 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440, 3840×2160

    Add Color To Your Life!

    “This month is dedicated to flowers, to join us and brighten our days giving a little more color to our daily life.” — Designed by Verónica Valenzuela from Spain.

    • preview
    • without calendar: 800×480, 1024×768, 1152×864, 1280×800, 1280×960, 1440×900, 1680×1200, 1920×1080, 2560×1440

    Lake Deck

    “I wanted to make a big painterly vista with some mountains and a deck and such.” — Designed by Mike Healy from Australia.

    • preview
    • without calendar: 1280×960, 1440×900, 1680×1050, 1920×1080, 2560×1440, 2560×1600, 2880×1800

    Tentacles

    Designed by Julie Lapointe from Canada.

    • preview
    • without calendar: 320×480, 1024×768, 1280×800, 1280×1024, 1440×900, 1680×1050, 1920×1200

    Today, Yesterday, Or Tomorrow

    Designed by Alma Hoffmann from the United States.

    • preview
    • without calendar: 1024×768, 1024×1024, 1280×800, 1280×1024, 1366×768, 1440×900, 1680×1050, 1920×1080, 1920×1200, 2560×1440

    The Monolith

    Designed by Ricardo Gimenes from Sweden.

    • preview
    • without calendar: 640×480, 800×480, 800×600, 1024×768, 1024×1024, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1366×768, 1400×1050, 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440, 3840×2160

    Asparagus Say Hi!

    “In my part of the world, May marks the start of seasonal produce, starting with asparagus. I know spring is finally here and summer is around the corner when locally-grown asparagus shows up at the grocery store.” — Designed by Elaine Chen from Toronto, Canada.

    • preview
    • without calendar: 320×480, 800×480, 800×600, 1024×768, 1024×1024, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1366×768, 1400×1050, 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1200, 1920×1440, 2560×1440

    Spring Gracefulness

    “We don’t usually count the breaths we take, but observing nature in May, we can’t count our breaths being taken away.” — Designed by Ana Masnikosa from Belgrade, Serbia.

    • preview
    • without calendar: 320×480, 640×480, 800×480, 800×600, 1024×768, 1024×1024, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1400×1050, 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440

    Blooming May

    “In spring, especially in May, we all want bright colors and lightness, which was not there in winter.” — Designed by MasterBundles from Ukraine.

    • preview
    • without calendar: 320×480, 640×480, 800×480, 800×600, 1024×768, 1024×1024, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1366×768, 1400×1050, 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440

    Enjoy May!

    “Springtime, especially May, is my favorite time of the year. And I like popsicles — so it’s obvious isn’t it?” — Designed by Steffen Weiß from Germany.

    • preview
    • without calendar: 320×480, 640×480, 800×480, 800×600, 1024×768, 1024×1024, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1400×1050, 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440

    Geo

    Designed by Amanda Focht from the United States.

    • preview
    • without calendar: 320×480, 640×480, 800×480, 1024×768, 1024×1024, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1366×768, 1400×1050, 1440×900, 1680×1200, 1920×1080, 1920×1440, 2560×1440

    Be On Your Bike!

    “May is National Bike Month! So, instead of hopping in your car, grab your bike and go. Our whole family loves that we live in our bike-friendly community. So, bike to work, to school, to the store, or to the park — sometimes it is faster. Not only is it good for the environment, but it is great exercise!” — Designed by Karen Frolo from the United States.

    • preview
    • without calendar: 1024×768, 1024×1024, 1280×800, 1280×960, 1280×1024, 1366×768, 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440

    Duck

    Designed by Madeline Scott from the United States.

    • preview
    • without calendar: 320×480, 640×480, 800×480, 800×600, 1024×768, 1024×1024, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1400×1050, 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440

    Flying In The Air

    “We recently changed our workplace and now we’re in a windy place, so we like the idea of flying in the air, somehow.” — Designed by Monk Software from Italy.

    • preview
    • without calendar: 320×480, 960×640, 1024×768, 1280×800, 1280×1024, 1920×1080, 2560×1440

    May Your May Be Magnificent

    “May should be as bright and colorful as this calendar! That’s why our designers chose these juicy colors.” — Designed by MasterBundles from Ukraine.

    • preview
    • without calendar: 320×480, 640×480, 800×480, 800×600, 1024×768, 1024×1024, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1366×768, 1400×1050, 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440

    Popping Into Spring

    “Spring has sprung, and what better metaphor than toast popping up and out of a fun-colored toaster!” — Designed by Stephanie Klemick from Emmaus Pennsylvania, USA.

    • preview
    • without calendar: 320×480, 640×480, 800×480, 800×600, 1024×768, 1024×1024, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1400×1050, 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440

    Make A Wish

    Designed by Julia Versinina from Chicago, USA.

    • preview
    • without calendar: 320×480, 640×480, 800×480, 800×600, 1024×768, 1024×1024, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440

    The Green Bear

    Designed by Pedro Rolo from Portugal.

    • preview
    • without calendar: 1024×768, 1280×800, 1440×900, 1680×1200, 1920×1080, 2560×1440

    Birds Of May

    “Inspired by a little-known ‘holiday’ on May 4th known as ‘Bird Day’. It is the first holiday in the United States celebrating birds. Hurray for birds!” — Designed by Clarity Creative Group from Orlando, FL.

    • preview
    • without calendar: 320×480, 640×480, 640×960, 640×1136, 800×480, 800×600, 1024×768, 1024×1024, 1152×864, 1280×720, 1280×800, 1280×960, 1280×1024, 1400×1050, 1440×900, 1600×1200, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 1920×1440, 2560×1440

    Beautiful Things

    Designed by Elise Vanoorbeek from Belgium.

    • preview
    • without calendar: 1280×720, 1280×800, 1280×960, 1280×1024, 1440×1050, 1440×900, 1680×1050, 1680×1200, 1920×1080, 1920×1200, 2560×1440

    Source: Articles on Smashing Magazine — For Web Designers And Developers.
  • How To Turn Your Figma Designs Into Live Apps With Anima Playground

    How To Turn Your Figma Designs Into Live Apps With Anima Playground

    April 29, 2025
    Software

    This article is a sponsored by Anima App

    For years, designers and developers have been stuck in a frustrating loop. Designers create stunning UIs in Figma, only for developers to spend hours — or days — coding them from scratch. Along the way, details get lost, tweaks pile up, and before you know it, the whole process turns into a never-ending back-and-forth.

    It’s a tale as old as modern product teams: pixel-perfect designs turned into imperfect realities, timelines stretched by repetitive tasks, and collaboration slowed by tool mismatches. Designers work in one world, developers in another — and the bridge between them has always been shaky at best.

    But what if you could just… skip the painful part?

    That’s where Anima Playground comes in. It’s a tool that transforms your Figma designs into fully functional web apps automatically. No more pixel-matching marathons, no more manual UI rebuilding. Just a smoother, faster way to go from a design to a live product — with AI doing the heavy lifting.

    What Is Anima Playground?

    Anima Playground is an AI-powered development environment that makes the jump from design to code seamless. It turns your Figma designs into clean, editable, and production-ready React components — instantly. And unlike static design-to-code tools of the past, this one goes further: it lets you add business logic, connect to APIs, and preview real-time changes right inside the playground.

    In short: it’s not just a handoff tool. It’s where design becomes a working app.

    Here’s what you can do with Anima Playground:

    • Import Figma designs exactly as they were created — layouts, styles, responsiveness, and all.
    • Generate React components instantly, with support for libraries like MUI and shadcn/ui.
    • Use AI prompts to add logic — from button clicks to dynamic lists and form validation.
    • Customize everything, with full code access and live previews.

    How It Works

    Easily sync your Figma designs with Anima Playground. All it takes is four quick steps.

    1. Import Your Figma Designs

    No clunky exports, no third-party converters. Just paste your Figma link, and Anima syncs it directly. It preserves layout, typography, responsiveness, and component structure, exactly as designed.

    This step sets the foundation: Anima translates your Figma layers into React code, respecting design fidelity down to the pixel. Designers can rest easy knowing their UI won’t get “lost in translation.”

    2. Convert Designs Into React Components

    Once imported, your Figma designs are instantly transformed into React components. This includes:

    • Clean JSX structure
    • Tailwind, MUI, or shadcn/ui styling (you choose!)
    • Nested component trees
    • Auto-handling of responsive layouts

    You can switch between UI libraries with a simple prompt or setting change — no need to rewrite everything manually. Whether you’re building a startup landing page or a complex dashboard, the output is dev-ready and easy to extend.

    3. Add Logic With AI-Powered Prompts

    Want a button to open a modal? Or a form that sends data to an API? You don’t need to write all that boilerplate yourself.

    Just describe what you want using natural language — for example:

    “Make this button open a signup modal.”

    Anima’s AI will generate the underlying code for you — complete with state management, handlers, and reusable logic. You can always dive in and tweak the output to fit your specific app structure.

    This turns design into functional UI with a level of speed that traditional front-end workflows just can’t match.

    4. See Live Changes Instantly

    As you make changes — whether through prompts or direct code edits — you see them reflected in real-time. Anima Playground acts as a visual IDE, combining the flexibility of code with the immediacy of design tools.

    This live feedback loop means less context-switching and faster iterations. Whether you’re testing animations, layout tweaks, or new features, you get to see it before you commit to anything.

    More Than Just Design-to-Code

    While many tools promise “Figma to code,” Anima Playground goes beyond static conversion. It’s a fully interactive environment where real apps are born — with logic, data, and interactivity.

    Some powerful features include:

    • One-click AI suggestions to enhance your UI with logic.
    • Custom component support, allowing teams to inject their own building blocks.
    • Component reuse, letting you structure apps in a scalable way.
    • Flexible framework support, starting with React and planning to support more in the future.

    It’s not just for prototyping — it’s for building.

    Why It Matters

    The design-to-code handoff has been broken for too long. Anima Playground isn’t just another tool. It’s a game-changer. Here’s why:

    • 🚀 Speed
      What used to take days now takes minutes. You skip the repetitive coding, layout guesswork, and context switching.
    • 🎯 Accuracy
      Your designs stay true to the original. No more pixel-matching or guessing which font size the designer used.
    • 🧩 Flexibility
      Developers get full access to the code. It’s not a black box — it’s fully transparent and editable.
    • 🤝 Collaboration
      Designers and developers finally share the same playground — literally. This tightens feedback loops and shortens build cycles.

    By making the workflow smarter, Anima Playground helps teams build better products, faster, and with fewer headaches.

    Who Is It For?

    Whether you’re a designer, developer, startup founder, or PM, Anima Playground removes the barriers between your ideas and real products.

    • Designers can see their visions come to life, exactly as imagined.
    • Developers can skip the grunt work and focus on logic, architecture, and business needs.
    • Teams can work together in a unified environment — no more waiting for the “handoff.”

    It’s perfect for building landing pages, dashboards, internal tools, MVPs, and more.

    Are You Ready To Try It?

    Anima Playground and the Anima API are redefining the connection between design and development in the era of AI-powered coding. Whether you’re a designer, developer, product team member, marketer, or entrepreneur, Anima empowers you to transform visual ideas into concepts within minutes—and into fully functional products within hours.

    If you’re tired of the endless design-to-development grind, it’s time to give Anima Playground a spin. Whether you’re a designer who wants to bring your vision to life or a developer looking to speed up the build process, this tool has your back.

    Let your designs do more than look good — let them work!


    Source: Articles on Smashing Magazine — For Web Designers And Developers.
  • Additional explanatory material for the Deepseek Overview

    April 21, 2025
    Software

    This article provides a cohesive overview of four technical reports from DeepSeek:

    1. DeepSeek-LLM (Jan ’24): an early investigation of scaling laws and data-model tradeoffs.
    2. DeepSeek-V2 (Jun ’24): introducing Multi-Head Latent Attention (MLA) and DeepSeekMoE to improve memory and training efficiency.
    3. DeepSeek-V3 (Dec ’24): scaling sparse MoE networks to 671B parameters, with FP8 mixed precision training and intricate HPC co-design
    4. DeepSeek-R1 (Jan ’25): building upon the efficiency foundations of the previous papers and using large-scale reinforcement learning to incentivize emergent chain-of-thought capabilities, including a “zero-SFT” variant.

    For additional context on DeepSeek itself and the market backdrop that has caused claims made by the DeepSeek team to be taken out of context and spread widely, please take a look at my colleague Prasanna Pendse’s post: Demystifying Deepseek. For the purposes of this article, we’ll be focusing analysis and commentary on the technical work itself, its merits, and what it may signal for the future.

    Much of this article assumes significant knowledge of the terminology and concepts of building LLMs, more so than is typical for articles on this site. In future weeks we hope to expand this article to provide explanations of these concepts to make this article easier to follow for those not familiar with this world. We shall post any such updates on this site’s usual channels.

    All four papers revolve around a singular challenge: building ever-larger language models with minimal cost, memory overhead, and training instability. In each iteration, the authors refine both architecture and infrastructure – a strategy often referred to as HPC co-design.

    Key arcs in this series include:

    • Cost and Memory Efficiency: Methods like Multi-Head Latent Attention (MLA) compression, mixture-of-experts (MoE), and FP8-based optimizations all aim to make massive-scale training and inference feasible.
    • Sparsity + HPC Co-Design: From V2 to V3, we see mixture-of-experts architecture evolve alongside specialized HPC scheduling—allowing 671B-parameter models to be trained on H800 clusters without blowing up the budget.
    • Emergent Reasoning: In R1, large-scale Reinforcement Learning (RL) unlocks advanced chain-of-thought capabilities, culminating in “R1-Zero” and its purely RL-driven approach to reasoning tasks.

    Motivation & Overview

    The authors set out to answer an important question: Given a fixed compute budget for pre-training, how do we choose the scale of the model and how much training data to use? Prior studies (e.g. Chinchilla vs. GPT-3) differed on the ratio between these two factors. DeepSeek-LLM addresses that by measuring scale in a different way. Earlier work measured scale in terms of how many parameters were in the model, DeepSeek-LLM instead measured scale as non-embedding FLOPs/token1 They then found they could predict computation with:

    1: Non-embedding FLOPs are the amount of FLOPs (Floating Point Operations per Second) used for pre-training certain layers of the transformer (non-embedding). The authors found only some layers contributed to the scaling formula.

    $$ C = M times D $$

    where $C$ is the compute budget, $M$ is non-embedding FLOPs/token, and $D$ is data size.

    This more granular representation helps them predict how a 7B or 67B model might train on 2T tokens of bilingual data.

    Training Instability

    A central concern they grapple with is training instability (sudden irrecoverable divergences in the training process), which can often manifest in large-scale language models—especially those with mixture-of-experts or very long contexts.

    By carefully tuning learning rates, batch sizes, and other hyperparameters 2, DeepSeek-LLM demonstrates that stable large-scale training is achievable, but it requires meticulous design of the architecture of the transformer model together with the infrastructure of the High Performance Computing (HPC) data center used to train it. This interwoven design of both architecture and infrastructure is called HPC Co-Design.

    2: A model consists of billions of internal variables, which are called its parameters. These parameters gain their values (weights) during training. Before training, developers will set a number of different variables that control the training process itself, these are called hyperparameters.
    Data Quality & Model Scale

    A point the authors make is about how data quality shifts the optimal ratio—i.e., higher-quality data can justify a bigger model for the same number of tokens. You can intuit this by imagining two scenarios:

    • Scenario A: You have a 100-billion-token corpus full of duplicates, spammy text, or incomplete sentences. The model might not glean much new knowledge because the data is partly redundant or low-value.
    • Scenario B: You have a carefully curated 100-billion-token corpus with broad coverage of code, math, multi-lingual dialogues, factual text, etc. Each token is more “information-rich,” so the model can “afford” to use more parameters without hitting diminishing returns prematurely.

    In other words, when data is denser in useful information, scaling the model further pays off because each parameter can learn from richer signals.

    Key Takeaways

    • Hyperparameter Scaling: They propose simple power-law fits to pick batch size and learning rate as compute $C$ grows.
    • Bilingual Data: They train two base sizes (7B, 67B) on 2T tokens covering English/Chinese, then do Supervised Fine Tuning (SFT) and a simpler preference-based alignment called Direct Preference Optimization (DPO).
    • Results: The resulting DeepSeek-LLM67B “Outperforms LLaMA-2 70B” on math/coding tasks, illustrating how HPC co-designed approaches can keep training stable while efficiently pushing scale.

    The seeds planted here – scaling laws and infrastructure for extremely large training – will reappear in subsequent works.

    DeepSeek-V2: Multi-Head Latent Attention & MoE

    Expanding the Model While Reducing Memory

    Where DeepSeek-LLM mostly explored high-level scale tradeoffs, DeepSeek-V2 dives into specifics of Transformer architecture overhead. Two big obstacles in large LLMs are:

    1. Attention KV Cache: Storing Key/Value vectors for thousands of tokens is memory-intensive.
    2. Feed-Forward Computation: Typically the largest consumption of FLOPs in a Transformer.

    To tame both, they propose:

    1. Multi-Head Latent Attention (MLA): compresses Key/Value vectors to reduce memory.
    2. DeepSeekMoE: a sparse Mixture-of-Experts approach that activates a fraction of the feed-forward capacity per token.

    Multi-Head Latent Attention (MLA)

    Attention is the process by which the model decides which tokens in the input stream to pay attention to when it’s trying to predict the next token. In standard attention, each token’s Q/K/V3 can be as large as $d_{model}$4 times the number of heads5. MLA folds them into smaller “latent” vectors:

    3: Q/K/V stand for “Query,” “Key,” and “Value” vectors. At each layer, the model uses learned linear transformations to produce these vectors from the hidden states of the input. The attention mechanism then computes similarities between Q and K to decide how much of each Value vector to incorporate.

    4: $d_{model}$ is the dimension of the model’s hidden representation. You can think of this hidden representation as the internal “space” in which the model’s computations occur. A larger dimension can capture richer and more complex patterns, though at increased computational and memory cost.

    5: In multi-head attention, a head is a parallel attention mechanism with its own parameters. From a software-engineering perspective, each head is a distinct transform that runs in parallel with the others, letting the model attend to different aspects of the input simultaneously.
    $$ quad mathbf{c}_{t}^{KV} = W^{DKV}mathbf{h}_t, quad mathbf{k}_{t}^{C} = W^{UK}mathbf{c}_t^{KV}, quad mathbf{v}_{t}^{C} = W^{UV}mathbf{c}_t^{KV}, quad $$

    Where $c_{t}^{KV}$ is the compressed latent vector for keys and values. $W^{DKV}$ is the down-projection matrix, and $W^{UK}, W^{UV}$ are the up-projection matrices for keys and values, respectively. In simpler terms:

    1. Replaces the standard QKV computation by using low rank factorization to turn one matrix of dim (in, out) into two matrices of (in, rank) and (rank, out)
    2. Project the compressed KV latent vector for each head to get the full K and V head corresponding to each Q head
    3. Cache the compressed KV latent vector instead of each of the KV heads in full, and compute the KV heads on the fly from the latent vector.

    DeepSeekMoE: Sparsely Activated FFNs

    Next, they adopt a Mixture-of-Experts (MoE) in the feed-forward blocks. Mixture-of-Experts (MoE) is a design technique that logically splits the model into separate areas (experts) each having specialized parameters for different domains of knowledge. Because each token is only routed to the experts most relevant to it, MoE can drastically reduce the compute required compared to a fully dense approach. This approach ties directly into the HPC co-design arc, as each expert can reside on different GPU devices. By limiting cross-device communication (e.g., device-limited routing), MoE effectively scales to extremely large parameter counts without incurring prohibitive memory or data-transfer costs.

    DeepSeek uses more fine-grained experts than previous models, dividing them into two kinds:

    • Shared Experts handle universal patterns for every token.
    • Routed Experts handle specialized sub-problems, chosen dynamically via gating.

    During training, they consider Auxiliary Loss to ensure balanced usage so no expert collapses (i.e. is never used).

    They further limit cross-device6 routing with a “device-limited routing” scheme – instead of allowing any token to access any expert, DeepSeekMoE selects a limited number of devices ($M$) per token, and performs expert selection only within these devices. The basic process is as follows:

    6: Here, a device usually means a single GPU (or specialized accelerator). Large-scale training typically distributes the model across many devices in a cluster to handle computation and memory constraints.

    • Identify top $M$ devices that contain experts with the highest affinity to the token
    • Perform top $K_r$ expert selection within these $M$ devices
    • Assign the selected experts to process the token

    Without device-limited routing, MoE models can generate excessive communication overhead which is incompatible with the hardware limitations imposed on the DeepSeek team. In addition, MoE models typically risk uneven expert utilization, where some experts are overused while others remain inactive. To prevent this, DeepSeekMoE introduces three balancing loss functions:

    • Expert-level Balance Loss ($L_{ExpBal}$):
      • Ensures uniform distribution of tokens across experts to prevent expert collapse
      • Uses a loss function based on softmax scores of token-expert affinity
    • Device-level Balance Loss ($L_{DevBal}$):
      • Ensures workload is evenly distributed across devices
    • Communication Balance Loss ($L_{CommBal}$):
      • Balances incoming and outgoing token routing to each device

    Training & Outcomes

    DeepSeek-V2, with ~236B total params (21B activated), is pre-trained on 8.1T tokens. They do Supervised Fine Tuning (SFT) on 1.5M instruction samples, then reinforcement learning (RL) for alignment7. The end result:

    7: Alignment refers to techniques (like supervised fine-tuning or reinforcement learning) that steer the model toward producing responses considered correct, helpful, or safe within certain guidelines or objectives.

    • Inference and training are both faster and cheaper (MLA + sparse experts)
    • They remain stable at scale

    This paper is really when iteration gains due to HPC Co-Design start to become apparent. By designing the model architecture with the training infrastructure in mind, and implementing a training regime that considers the realities of the hardware (e.g. low interconnect speeds on H800s), the team was able to lay the foundation for their most notable breakthrough.

    DeepSeek-V3: HPC Co-Design

    Scaling MoE to 671B While Preserving Efficiency

    Building on V2, DeepSeek-V3 further extends sparse models to 671B parameters (37B activated), training on 14.8T tokens in under 2.8M H800 GPU hours. The authors credit extensive HPC co-design:
    Lastly, we emphasize again the economical training costs of DeepSeek-V3, summarized in Table 1, achieved through our optimized co-design of algorithms, frameworks, and hardware.

    — DeepSeek-V3 Tech. Report, p.5

    The major novelties are:

    1. Refined MLA
    2. Refined DeepSeekMoE
    3. Co-Designed Training & Inference Frameworks

    Refined MLA

    Multi-Head Latent Attention was introduced in V2 to reduce KV cache overhead. In V3, it is further refined with several new features:

    • Improved RoPE Handling: V2 only partially decoupled keys8, but V3 extends the concept for more stable 128K context. They track a “decoupled shared key” that reduces numerical drift9 in extremely long generations.
    • 8: “Decoupling” the keys refers to a strategy of separating or factoring out certain positional or rotational encodings so that they can be processed with reduced interference, improving numerical stability for extended context windows.
      9: Numerical drift occurs when small floating-point rounding errors accumulate over long sequences or many operations, potentially causing the model’s outputs (e.g. attention scores) to diverge or become unstable for very long context lengths.

    • Joint KV Storage: V2 stored compressed keys and values separately. V3 merges them into a shared compressed representation to further reduce memory traffic during multi-node inference10.
    • 10: Multi-node inference refers to running the model across multiple interconnected machines (or “nodes”) in a cluster—distinct from simply using multiple GPUs in one node. Although both multi-GPU and multi-node setups distribute the model, multi-node adds additional networking and scheduling layers that must be co-designed for efficiency.

    • Layer-Wise Adaptive Cache: Instead of caching all past tokens for all layers, V3 prunes older KV entries at deeper layers. This helps keep memory usage in check when dealing with 128K context windows.

    Together, these MLA refinements ensure that while DeepSeek-V3 can attend across very long sequences, the memory overhead remains manageable. While many popular LLMs cap out around 4K to 32K tokens, 128K pushes that envelope significantly, enabling the model to process or reference an entire large document in a single pass. This bigger context window puts added pressure on GPU memory—hence the importance of refining MLA to keep overhead in check.

    Refined DeepSeekMoE: Auxiliary-Loss-Free, Higher Capacity

    On the MoE side, DeepSeek-V3 drops the auxiliary-loss approach from V2. Instead of an explicit penalty term, each expert acquires a dynamic bias $b_i$. If an expert is overloaded at a step, $b_i$ decreases; if underloaded, $b_i$ increases. The gating decision then adds $b_i$ to the token’s affinity:

    $$ s’_{i,t} = s_{i,t} + b_i $$

    Key Improvements:

    • No Token Dropping: V2 occasionally dropped tokens if certain experts got overloaded, but the new bias-based method keeps everything.
    • More Activated Experts: They raise the number of routed experts from 6 to 8 per token, improving representational power.
    • Higher Stability: By removing auxiliary losses, they avoid potential interference with the main training objective, focusing purely on the intrinsic gating signals plus bias adjustments11.
    • 11: By removing auxiliary losses that directly penalize or encourage certain expert usage, the gating mechanism is now free to learn solely from the main optimization objective. This prevents external penalty terms from overshadowing or disrupting the natural distribution of tokens across experts.

    Hence, the final feed-forward module is a combination of a small set of shared experts plus up to 8 specialized experts chosen adaptively.

    Co-Designed Frameworks: FP8, DualPipe, and PTX Optimizations

    Scaling an MoE model to 671B demanded HPC-level solutions for training and inference. The authors emphasize:

    Through the co-design of algorithms, frameworks, and hardware, we overcome the communication bottleneck in cross-node MoE training, achieving near-full computation- communication overlap.

    — DeepSeek-V3 Tech. Report, p.5

    FP8 Mixed Precision

    They adopt an FP8 data format for General Matrix Multiplications (GEMMs), halving memory. The risk is reduced numeric range so they offset it with:

    • Block-wise scaling (e.g., 1×128 or 128×128 tiles).
    • Periodic “promotion” to FP32 after short accumulation intervals to avoid overflow/underflow.

    DualPipe Parallelism

    They propose DualPipe to overlap forward/backward computation with the MoE all-to-all dispatch. It rearranges pipeline stages to ensure that network communication (particularly across InfiniBand12) is hidden behind local matrix multiplications.

    12: InfiniBand is a high-speed, low-latency network interconnect often used in HPC clusters. “Hiding” network traffic behind other computations means overlapping communication with local GPU operations so that data transfer time has minimal impact on the total runtime.

    PTX-Level & Warp Specialization

    To fully exploit InifiniBand(IB) and NVLink:

    • They tune warp-level13 instructions in PTX (a level lower than CUDA), auto-tuning the chunk size for all-to-all dispatch.
    • 13: At the GPU’s warp level, instructions control how threads are batched and scheduled. Hand-tuned or specialized PTX code can exploit specific GPU hardware features for more efficient parallel processing, especially in all-to-all (MoE) communication.

    • They dynamically partition Streaming Microcontrollers into communication vs. compute tasks so that token dispatch never stalls local GEMM14.
    • 14: Streaming multiprocessors (SMs or “microcontrollers”) can be partially allocated to communication or computation tasks. Dynamically partitioning them ensures that the model’s token-routing (communication) can happen without forcing compute-bound operations to idle, boosting overall utilization.

    As a result, training costs were cut to 2.8M H800 GPU hours per run – low for a 14.8T token corpus.

    Outcomes

    The resulting DeepSeek-V3 excels at code, math, and some multilingual tasks, outperforming other open-source LLMs of similar scale. Deep HPC co-design (FP8, DualPipe, PTX-level optimization) plus refined MLA/MoE implementation achieve extreme scale with stable training.

    DeepSeek-R1: Reinforcement Learning for Deeper Reasoning

    It’s worth noting that both DeepSeek R1 and DeepSeek R1-Zero are architecturally identical to DeepSeek V3. They both take the pre-trained base model of V3 and apply differing amounts of post-training.

    Emergent Reasoning Behaviors Through RL-Only

    All prior DeepSeek releases used Supervised Fine-Tuning (SFT), plus occasional Reinforcement Learning (RL). By contrast, DeepSeek-R1-Zero tries an extreme: no supervised warmup, just RL from the base model. They adopt Group Relative Policy Optimization (GRPO), which:

    1. Samples a group of old-policy outputs ${o_1, …, o_G}$
    2. Scores each with a reward (in this case, rule-based)
    3. Normalizes the advantage $A_i$ by group mean/stdev
    4. Optimizes a clipped PPO-like objective15
    5. 15: PPO stands for Proximal Policy Optimization, a popular reinforcement learning algorithm that optimizes a clipped objective to keep the new policy from deviating too far from the old policy.

    The reward function for the R1 models is rule-based – a simple weighted sum between 2 components

    • Accuracy Reward – if the task has an objective correct answer (e.g. a math problem, coding task, etc.), correctness is verified using mathematical equation solvers for step-by-step proof checking, and code execution & test cases for code correctness verification
    • Format Reward – the model is rewarded for following a structured reasoning process using explicit reasoning markers <think></think> and <answer></answer>

    The relative advantage $A_i$ for a given output is calculated as:

    $$ A_i = frac{r_i – mean({r_1, r_2, …, r_G})}{std({r_1, r_2, …, r_G})} $$

    where $r_i$ is the reward calculated for the given output. The model’s policy is updated to favor responses with higher rewards while constraining changes using a clipping function which ensures that the new policy remains close to the old.

    In so many words: the authors created a testing/verification harness around the model which they exercised using reinforcement learning, and gently guided the model using simple Accuracy and Format rewards. In doing so, emergent reasoning behaviors were observed:

    • Self-verification where the model double-checks its own answers
    • Extended chain-of-thought where the model learns to explain its reasoning more thoroughly
    • Exploratory reasoning – the model tries different approaches before converging on an answer
    • Reflection – the model starts questioning its own solutions and adjusting reasoning paths dynamically

    R1-Zero is probably the most interesting outcome of the R1 paper for researchers because it learned complex chain-of-thought patterns from raw reward signals alone. However, the model exhibited notable issues:

    • Readability Problems: Because it never saw any human-curated language style, its outputs were sometimes jumbled or mixed multiple languages.
    • Instability in Non-Reasoning Tasks: Lacking SFT data for general conversation, R1-Zero would produce valid solutions for math or code but be awkward on simpler Q&A or safety prompts.
    • Limited Domain: Rule-based rewards worked well for verifiable tasks (math/coding), but handling creative/writing tasks demanded broader coverage.

    Hence, the authors concluded that while “pure RL” yields strong reasoning in verifiable tasks, the model’s overall user-friendliness was lacking. This led them to DeepSeek-R1: an alignment pipeline combining small cold-start data, RL, rejection sampling, and more RL, to “fill in the gaps” from R1-Zero’s deficits.

    Refined Reasoning Through SFT + RL

    DeepSeek-R1 addresses R1-Zero’s limitations by injecting a small amount of supervised data before RL and weaving in additional alignment steps.

    Stage 1: “Cold-Start” SFT

    They gather a small number (~thousands) of curated, “human-friendly” chain-of-thought data covering common sense Q&A, basic math, standard instruction tasks, etc. Then, they do a short SFT pass on the base model. This ensures the model acquires:

    • Better readability: Polished language style and formatting.
    • Non-reasoning coverage: Some conversation, factual QA, or creative tasks not easily rewarded purely by rule-based checks.

    In essence, the authors realized you can avoid the “brittleness” of a zero-SFT approach by giving the model a seed of user-friendly behaviors.

    Stage 2: Reasoning-Oriented RL

    Next, as in R1-Zero, they apply large-scale RL for tasks like math and code. The difference is that now the model starts from a “cold-start SFT” checkpoint—so it retains decent language style while still learning verifiable tasks from a rule-based or tool-based reward. This RL stage fosters the same emergent chain-of-thought expansions but without the random “language mixing” or bizarre structure.

    Stage 3: Rejection Sampling + Additional SFT

    Once that RL converges, they generate multiple completions per prompt from the RL checkpoint. Using a combination of automatic verifiers and some human checks, they pick the best outputs (“rejection sampling”) and build a new SFT dataset. They also incorporate standard writing/factual/safety data from DeepSeek-V3 to keep the model balanced in non-verifiable tasks. Finally, they re-fine-tune the base model on this curated set.

    This step addresses the “spotty coverage” problem even further: The best RL answers become training targets, so the model improves at chain-of-thought and clarity.

    Stage 4: RL for “All Scenarios”

    Lastly, they do another RL pass on diverse prompts—not just math/code but general helpfulness, safety, or role-playing tasks. Rewards may come from a combination of rule-based checks and large “preference” models (trained from user preference pairs). The final result is a model that:

    • Retains strong chain-of-thought for verifiable tasks,
    • Aligns to broad user requests in everyday usage,
    • Maintains safer, more controlled outputs.

    Connecting the Arcs: Efficiency & Emergence

    Despite covering different angles – scaling laws, MoE, HPC scheduling, and large-scale RL – DeepSeek’s work consistently follows these arcs:

    1. Cost and Memory Efficiency
    • They systematically design methods (MLA, MoE gating, device-limited routing, FP8 training, DualPipe) to maximize hardware utilization even in constrained environments
    • HPC-level scheduling (PTX instructions, warp specialization) hides communication overhead and overcomes the limitations imposed by limited interconnect speeds on H800s
  • Sparse + HPC Co-Design
    • From V2 to V3, we see an evolving mixture-of-experts approach, culminating in a 671B-parameter model feasible on H800 clusters.
    • The authors repeatedly stress that HPC co-design is the only path to cheaply train multi-hundred-billion-parameter LLMs.
  • Emergent Reasoning
    • R1 pushes beyond standard supervised training, letting RL signals shape deep chain-of-thought. The synergy between pre-trained scale and targeted post-training yields advanced reasoning patterns like reflection or multi-step verification.

    Taken as a whole, the DeepSeek series highlights how architecture, algorithms, frameworks, and hardware must be co-designed to handle LLM training at trillion-token scales. Looking to the future, it indicates that toolchain builders may want to find ways to capture some of these HPC optimizations as part of the model compilation path or training apparatus, and AI research teams may want to work closely with HPC expertise even in the early days of architecture ideation.


    Source: Martin Fowler.

  • Guiding an LLM for Robust Java ByteBuffer Code

    April 17, 2025
    Software

    AI editors like Cursor can generate code with remarkable speed using LLMs, handling boilerplate and providing functional snippets for various tasks. However, when building robust systems, functional correctness is only the starting point. Code must also be safe, predictable, maintainable, and free from subtle side effects.

    This article demonstrates, through a dialogue between a developer and an LLM, how expert guidance is crucial to transform an initial, potentially unsafe code snippet into a robust, system-ready component. This development session was done as part of a larger development effort to write a BoltDB like storage engine for an internal workshop. This also demonstrates how breaking the larger development efforts into smaller programming sessions can be more effective with LLM based development. We’ll use the common task of reading and writing a fixed-structure header within a Java ByteBuffer.

    Our goal is to create a Java class to manage a simple page header structure within a ByteBuffer. The structure includes: Page Type (byte), Page Level (byte), Number of Keys (short), Free Space Offset (int), and Right Sibling Page ID (int).

    The Conversation Begins

    Initial Prompt to Start the Conversation

    Can you show me how to write and read a simple page header structure to a Java ByteBuffer? The header should contain: Page Type (byte), Page Level (byte), Number of Keys (short), Free Space Offset (int), Right Sibling Page ID (int).

    LLM-Generated Code (Using position())

    Certainly. Here’s a basic example using ByteBuffer’s position() method to manage reads and writes:”

    import java.nio.ByteBuffer; public class PageHeaderV1 { // Offsets (implicitly managed by position) private static final int PAGE_TYPE_OFFSET = 0; private static final int LEVEL_OFFSET = 1; // pageType is 1 byte private static final int NUM_KEYS_OFFSET = 2; // level is 1 byte private static final int FREE_SPACE_OFFSET_OFFSET = 4; // numKeys is 2 bytes private static final int RIGHT_SIBLING_OFFSET = 8; // freeSpaceOffset is 4 bytes public static final int HEADER_SIZE = 12; // rightSibling is 4 bytes public static void write(ByteBuffer buffer, byte pageType, byte level, short numKeys, int freeSpaceOffset, int rightSiblingPageId) { buffer.clear(); // Reset position to 0, limit to capacity buffer.position(PAGE_TYPE_OFFSET); buffer.put(pageType); buffer.position(LEVEL_OFFSET); buffer.put(level); buffer.position(NUM_KEYS_OFFSET); buffer.putShort(numKeys); buffer.position(FREE_SPACE_OFFSET_OFFSET); buffer.putInt(freeSpaceOffset); buffer.position(RIGHT_SIBLING_OFFSET); buffer.putInt(rightSiblingPageId); } public static byte getPageType(ByteBuffer buffer) { buffer.position(PAGE_TYPE_OFFSET); return buffer.get(); } public static byte getLevel(ByteBuffer buffer) { buffer.position(LEVEL_OFFSET); return buffer.get(); } public static short getNumKeys(ByteBuffer buffer) { buffer.position(NUM_KEYS_OFFSET); return buffer.getShort(); } public static int getFreeSpaceOffset(ByteBuffer buffer) { buffer.position(FREE_SPACE_OFFSET_OFFSET); return buffer.getInt(); } public static int getRightSiblingPageId(ByteBuffer buffer) { buffer.position(RIGHT_SIBLING_OFFSET); return buffer.getInt(); } } 

    This code uses position() to move to the correct offset before each read or write.

    Developer Insight: The LLM produced functionally correct code for a simple case. However, the expert developer immediately recognizes a potential problem: the use of buffer.position(). This method modifies the state of the ByteBuffer object itself.

    Developer Suggests Absolute Offsets

    Thanks. However, constantly changing the buffer’s position can cause issues, especially with shared buffers like MappedByteBuffer or in concurrent code. It introduces side effects. Can we rewrite this using the absolute get(index) and put(index, value) methods instead to make it stateless regarding the buffer’s position?

    Developer Insight: The developer identifies the specific issue (side effects via state mutation) and understands the context where it becomes dangerous (shared buffers, concurrency). They guide the LLM towards a safer, stateless pattern.

    You are absolutely right. Using absolute offset methods avoids modifying the buffer’s position state, which is much safer for shared or concurrent use cases. Here’s how you can read the numKeys and freeSpaceOffset using the absolute methods:

    import java.nio.ByteBuffer; // Example correction for a couple of methods: public class PageHeaderCorrection { private static final int NUM_KEYS_OFFSET = 2; private static final int FREE_SPACE_OFFSET_OFFSET = 4; // Corrected getter using absolute offset public static short getNumKeys(ByteBuffer buffer) { return buffer.getShort(NUM_KEYS_OFFSET); // Reads at index 2, doesn't change position } // Corrected getter using absolute offset public static int getFreeSpaceOffset(ByteBuffer buffer) { return buffer.getInt(FREE_SPACE_OFFSET_OFFSET); // Reads at index 4, doesn't change position } // Similarly, writing would use put(index, value): public static void writeNumKeys(ByteBuffer buffer, short numKeys) { buffer.putShort(NUM_KEYS_OFFSET, numKeys); // Writes at index 2, doesn't change position } } 

    Using get(index) and put(index, value) ensures the operations are side-effect-free concerning the buffer’s position.

    Developer Insight: The LLM correctly implements the suggested pattern. The developer now pushes for better software design, moving from static utility methods to an object-oriented approach.

    Developer Requests Refactoring to Instance-Based Class

    Developer: “Excellent, that’s exactly the pattern needed. Please provide the complete PageHeader class using only the absolute offset methods (get(index), put(index, value), getShort(index), putShort(index, value), etc.) for all fields. Also, let’s refactor this. Instead of static methods, make PageHeader a class that takes the ByteBuffer in its constructor. It should act as a view or wrapper around that buffer section. Remove the static write method that takes all attributes. Instead, provide instance methods for getting and setting each field directly on the buffer provided in the constructor, still using the safe absolute offset methods.”

    Developer Insight: The developer applies software design principles: Encapsulation (wrapping the buffer) and Object-Oriented Design (instance methods acting on object state – the buffer reference). This improves usability and maintainability.

    LLM: “Understood. Refactoring the PageHeader into a class that wraps a ByteBuffer provided at construction is a good way to encapsulate header access for a specific page buffer. Here’s the refactored class with instance methods for getting and setting fields using absolute offsets:”

    import java.nio.ByteBuffer; public class PageHeader { // Define constants for offsets and size private static final int OFFSET_PAGE_TYPE = 0; private static final int OFFSET_LEVEL = 1; private static final int OFFSET_NUM_KEYS = 2; private static final int OFFSET_FREE_SPACE = 4; private static final int OFFSET_RIGHT_SIBLING = 8; public static final int HEADER_SIZE = 12; // Total size of the header private final ByteBuffer buffer; // Store the buffer instance /** * Creates a PageHeader view wrapping the given ByteBuffer. * Assumes the buffer's relevant section starts at position 0 * or that the buffer slice/view is correctly positioned. * @param buffer The ByteBuffer containing the page data. */ public PageHeader(ByteBuffer buffer) { // Consider adding checks: buffer != null, buffer.capacity() >= HEADER_SIZE this.buffer = buffer; } // --- Getters using absolute offsets --- public byte getPageType() { return buffer.get(OFFSET_PAGE_TYPE); } public byte getLevel() { return buffer.get(OFFSET_LEVEL); } public short getNumKeys() { return buffer.getShort(OFFSET_NUM_KEYS); } public int getFreeSpaceOffset() { return buffer.getInt(OFFSET_FREE_SPACE); } public int getRightSiblingPageId() { return buffer.getInt(OFFSET_RIGHT_SIBLING); } // --- Setters using absolute offsets --- public void setPageType(byte pageType) { buffer.put(OFFSET_PAGE_TYPE, pageType); } public void setLevel(byte level) { buffer.put(OFFSET_LEVEL, level); } public void setNumKeys(short numKeys) { buffer.putShort(OFFSET_NUM_KEYS, numKeys); } public void setFreeSpaceOffset(int freeSpaceOffset) { buffer.putInt(OFFSET_FREE_SPACE, freeSpaceOffset); } public void setRightSiblingPageId(int rightSiblingPageId) { buffer.putInt(OFFSET_RIGHT_SIBLING, rightSiblingPageId); } /** * Initializes a new header structure with default/zero values * in the underlying buffer. */ public void initializeNewHeader() { setPageType((byte) 0); setLevel((byte) 0); setNumKeys((short) 0); setFreeSpaceOffset(HEADER_SIZE); // Default free space starts after header setRightSiblingPageId(0); // Assuming 0 represents no sibling initially // Or use specific constants for null/invalid IDs if available } } 

    This version encapsulates access to the header fields within an instance tied to a specific ByteBuffer. All read and write operations use absolute offsets, ensuring safety and avoiding side effects on the buffer’s position. I’ve also added an example initializeNewHeader method for convenience.

    Takeaways: The importance of the developer role

    There are more improvements possible. But this dialogue highlights critical areas where developer expertise is indispensable when working with LLMs:

    1. Identifying Hidden Risks: The initial code worked, but the developer recognized the latent danger of side effects from position() in broader system contexts.
    2. Contextual Awareness: Understanding implications for MappedByteBuffer, concurrency, and library design was key to steering away from the stateful approach.
    3. Guiding Towards Robust Patterns: The developer explicitly prompted for stateless, absolute offset methods, leveraging deep knowledge of safe low-level programming practices.
    4. Applying Software Design Principles: The final refactoring wasn’t just about correctness but about better design – encapsulation, instance-based logic, maintainability (constants), and usability.
    5. Critical Evaluation: Throughout the process, the developer critically evaluated the LLM’s output against not just functional requirements but also non-functional requirements like safety, stability, and maintainability.

    Conclusion

    LLMs are incredibly powerful coding assistants, accelerating development and handling complex tasks. However, as this case study shows, they are tools that respond to guidance. Building robust, reliable, and performant systems, requires the critical thinking, contextual understanding, and deep systems knowledge of an experienced developer. The expert doesn’t just prompt for code; they evaluate, guide, refine, and integrate, ensuring the final product meets the rigorous demands of real-world software engineering.


    Source: Martin Fowler.

  • Updating yesterday’s post on social media engagement

    April 4, 2025
    Software
    Photo of Martin Fowler
    Martin Fowler

    04 April 2025

    A few years ago, whenever I published a new article here, I would just announce it on Twitter, which seemed to help attract readers who would find the article worthwhile. Since the Muskover, Twitter’s importance has declined sharply. It now doesn’t take very much time at all for me to check posts of people I follow on X (Twitter), since most of them have left. Instead I’m looking at other social sites, and posting there too. Now when I announce a new article, I post on LinkedIn, Bluesky, Mastodon, as well as X (Twitter). (I also post into my RSS feed, which is still my favorite way to let people know of new material, but that may just reveal I’m stuck in an idyllic past.)

    While it’s one thing to have a gut feel for the importance of these platforms, I’d rather gather some more objective data.

    One source of data is how many followers I have on the these platforms.

    Here X (Twitter) shows a notable lead, but I strongly suspect that many of my followers there are inactive (or bots). Considering I only joined LinkedIn about a year ago, it’s developed a healthy number.

    Given that I decided to look at activity based on my recent posts. Most of my posts to social media I make across all these platforms, tweaking them a little bit depending upon their norms and constraints. For this exercise I took 24 recent posts and looked at what activity they generated on each platform.

    I’ll start with reposts. Although some LinkedIn posts get reposted more often than X, the median is pretty close. Bluesky trails a bit behind, but nowhere near as far as the follower count would suggest. Mastodon, as we’ll see with all three stats, is far smaller.

    Figure 2: Plot of reposts

    This plot is a combined strip chart and box plot. When visualizing data, I’m suspicious of using aggregates such as averages, as averages can often hide a lot of important information. I much prefer to plot every point, and in this case a stripchart does the trick. A strip chart plots every data point as a dot on a column for the category. So every dot in the linkedIn column is the value for one linkedin post. I add some horizontal jitter to these points so they don’t print on top of each other. The strip charts allow me to see every point and thus get a good feel of the distribution. I then overlay a boxplot, which allows me to compare medians and quartiles.

    Shift over to likes however, and now LinkedIn is far above the others, X and Bluesky are about the same.

    Figure 3: Plot of likes

    With replies LinkedIn is again clearly averaging more, but bluesky does have a significant number of heavily replied posts that push its upper quartile far above the other two services.

    Figure 4: Plot of replies

    That’s looking at the data, how might I interpret this in terms of the importance of the services? Of the three I’m more inclined to value the reposts – after all that is someone thinking the that post is valuable enough to send out to their own followers. That indicates a clear pecking order with LinkedIn > X > Bluesky > Mastodon. It’s interesting that LinkedIn is a more singular leader on likes, it seems both higher itself and X is lower. I guess that means LinkedIn people are more eager to hit the like button.

    As for replies, it’s interesting to see that Bluesky has generated quite a few posts that have triggered lots of replies. But given that most replies aren’t exactly insightful, I don’t chalk that up as a positive. Indeed I see more inane and downright mean replies on Bluesky than I ever got on Twitter. In contrast, while Mastodon replies are much fewer, they far more likely to be worth reading.

    An obvious further question to look at would be how many people click on the link and go on to read the article. To track that information, I’d need to add tracking attributes to my URLs (eg ?utm_source=mastodon&utm_medium=social). I’ve not done that, partly because I always disliked such cluttered URLs, but mostly because I don’t think I’d get enough value from the information to be worth the trouble.

    What I can do, however, is look at the source information for all traffic to the site. Here’s a plot of engaged sessions for the first quarter of each the last three years.

    As we can see X (Twitter) was the dominant figure in 2023 but in 2025 LinkedIn has surged to a much greater amount of traffic. Bluesky is hardly visible. (I can’t track Mastodon this way.)

    LinkedIn has indeed shot to #3 source so far this year. But #3 is a long way from the first two (google and direct).

    LinkedIn may be #3, but is the source for only 3.3% of the site’s traffic.1

    1: I’m not sure how much traffic from these networks does not get properly flagged as a source in the analytics, so I’m wary of concluding too much from this figure.

    One of the reasons for this is that social media posts may drive traffic to new articles, but most of my traffic is for older material. 80% of the traffic to my site goes to articles that are over six months old.

    Overall, I’d say that LinkedIn has taken over as the number one social network for my posts, but X (Twitter) is still important. And Bluesky is by far the most active on a per-follower basis.


    Source: Martin Fowler.

  • Social Media Engagement in Early 2025

    April 3, 2025
    Software
    Photo of Martin Fowler
    Martin Fowler

    04 April 2025

    A few years ago, whenever I published a new article here, I would just announce it on Twitter, which seemed to help attract readers who would find the article worthwhile. Since the Muskover, Twitter’s importance has declined sharply. It now doesn’t take very much time at all for me to check posts of people I follow on X (Twitter), since most of them have left. Instead I’m looking at other social sites, and posting there too. Now when I announce a new article, I post on LinkedIn, Bluesky, Mastodon, as well as X (Twitter). (I also post into my RSS feed, which is still my favorite way to let people know of new material, but that may just reveal I’m stuck in an idyllic past.)

    While it’s one thing to have a gut feel for the importance of these platforms, I’d rather gather some more objective data.

    One source of data is how many followers I have on the these platforms.

    Here X (Twitter) shows a notable lead, but I strongly suspect that many of my followers there are inactive (or bots). Considering I only joined LinkedIn about a year ago, it’s developed a healthy number.

    Given that I decided to look at activity based on my recent posts. Most of my posts to social media I make across all these platforms, tweaking them a little bit depending upon their norms and constraints. For this exercise I took 24 recent posts and looked at what activity they generated on each platform.

    I’ll start with reposts. Although some LinkedIn posts get reposted more often than X, the median is pretty close. Bluesky trails a bit behind, but nowhere near as far as the follower count would suggest. Mastodon, as we’ll see with all three stats, is far smaller.

    Figure 2: Plot of reposts

    This plot is a combined strip chart and box plot. When visualizing data, I’m suspicious of using aggregates such as averages, as averages can often hide a lot of important information. I much prefer to plot every point, and in this case a stripchart does the trick. A strip chart plots every data point as a dot on a column for the category. So every dot in the linkedIn column is the value for one linkedin post. I add some horizontal jitter to these points so they don’t print on top of each other. The strip charts allow me to see every point and thus get a good feel of the distribution. I then overlay a boxplot, which allows me to compare medians and quartiles.

    Shift over to likes however, and now LinkedIn is far above the others, X and Bluesky are about the same.

    Figure 3: Plot of likes

    With replies LinkedIn is again clearly averaging more, but bluesky does have a significant number of heavily replied posts that push its upper quartile far above the other two services.

    Figure 4: Plot of replies

    That’s looking at the data, how might I interpret this in terms of the importance of the services? Of the three I’m more inclined to value the reposts – after all that is someone thinking the that post is valuable enough to send out to their own followers. That indicates a clear pecking order with LinkedIn > X > Bluesky > Mastodon. It’s interesting that LinkedIn is a more singular leader on likes, it seems both higher itself and X is lower. I guess that means LinkedIn people are more eager to hit the like button.

    As for replies, it’s interesting to see that Bluesky has generated quite a few posts that have triggered lots of replies. But given that most replies aren’t exactly insightful, I don’t chalk that up as a positive. Indeed I see more inane and downright mean replies on Bluesky than I ever got on Twitter. In contrast, while Mastodon replies are much fewer, they far more likely to be worth reading.

    An obvious further question to look at would be how many people click on the link and go on to read the article. To track that information, I’d need to add tracking attributes to my URLs (eg ?utm_source=mastodon&utm_medium=social). I’ve not done that, partly because I always disliked such cluttered URLs, but mostly because I don’t think I’d get enough value from the information to be worth the trouble.

    What I can do, however, is look at the source information for all traffic to the site. Here’s a plot of engaged sessions for the first quarter of each the last three years.

    As we can see X (Twitter) was the dominant figure in 2023 but in 2025 LinkedIn has surged to a much greater amount of traffic. Bluesky is hardly visible. (I can’t track Mastodon this way.)

    LinkedIn has indeed shot to #3 source so far this year. But #3 is a long way from the first two (google and direct).

    LinkedIn may be #3, but is the source for only 3.3% of the site’s traffic.1

    1: I’m not sure how much traffic from these networks does not get properly flagged as a source in the analytics, so I’m wary of concluding too much from this figure.

    One of the reasons for this is that social media posts may drive traffic to new articles, but most of my traffic is for older material. 80% of the traffic to my site goes to articles that are over six months old.

    Overall, I’d say that LinkedIn has taken over as the number one social network for my posts, but X (Twitter) is still important. And Bluesky is by far the most active on a per-follower basis.


    Source: Martin Fowler.

  • I’ve been kidnapped by Robert Caro

    April 1, 2025
    Software
    Photo of Martin Fowler
    Martin Fowler

    30 March 2025

    diversions

    I’ve always enjoyed reading, and for most of my life I’ve particularly enjoyed reading history. My wife is a structural engineer (well “was”, as she’s now retired) and long urged me to read one of her favorite books: The Power Broker, by Robert Caro. I’d heard great things about this book from other sources too, so was certainly inclined to. The problem was that it is a huge book, over 1200 pages, and I didn’t want to lug it around in my carry-on baggage – and it wasn’t available in electronic form.

    He’s a highly regarded writer, so I might try something else, but his other work is a biography of Lyndon Johnson. Not one book, however, but four huge volumes – and he’s only got up to 1964. Now Lyndon Johnson is a fascinating character, and I’d like to read more about him, but nobody is worth four-plus volumes.

    Then, last fall, The Power Broker because available electronically, so I finally decided to get to reading it, further encouraged by a wonderful series of podcasts on 99% invisible.

    The Power Broker is a biography of Robert Moses. Most readers are probably wondering who that is. Robert Moses was one of the most powerful officials in New York for four decades. While he never won any elected office, he had more power, and often access to more money, than either New York City’s mayor or New York State’s governor. He used this power to build highways, parks, bridges, and buildings – in the process displacing hundreds of thousands of people from their homes. His impact on New York is still apparent decades after he lost power in the 1960’s as it shaped the physical structure of the city to this day.

    So Caro’s book is interesting because it describes an otherwise little-known but highly influential figure. Further than that, the book is wonderful because it is so well written. I’m a professional writer of non-fiction, but reading this book reminds me how far I have yet to advance to consider myself anywhere close to mastery of my profession. Many times, I’ve had to stop after reading a section, just so I can catch my breath and fully admire the prose I’ve just read. He can take the arcane maneuverings of 1920’s New York legislature and make it a page-turner. He has a superb knack of putting the reader into the story, making me feel how Moses’s actions affected the lives of the people whose communities were lost to build those highways.

    It was the best book I’ve read for many years.

    So now the prospect of four volumes of Lyndon Johnson no longer filled me with apprehension. I dove right in. As I write this I’m half way through, and the quality of the writing hasn’t stopped. The first book has memorable passages describing “the trap” that the Texas Hill Country set for its early settlers, the struggles for farmers working that land before Johnson’s efforts brought them electricity, the way Johnson bullied those who worked for him, and how he flattered those men more powerful than him.

    Caro’s reputation is built on the detailed research he and his wife do into these books. Many people had told stories on Johnson’s early life, but the Caros went out and seemingly interviewed every living person who knew Johnson. These interviews revealed the true story behind these stories, making Johnson less benevolent, but even more fascinating. The second volume is forged from this kind of research, as the Caros realized that the story of Johnson’s 1948 senate race was even more thrilling than a victory margin of 87 votes out of 988,295 might suggest. And like The Power Broker included a jaw-droppingly good mini-biography of New York governor Al Smith, this book painted an enthralling biography of Texas governor Coke Stevenson. It kept me up late several nights as I couldn’t stop myself from just one more section.

    Reviewers I’ve read say the next in the series, Master of the Senate, is the best volume. I can’t wait to get started.


    Source: Martin Fowler.

  • The role of developer skills in agentic coding

    March 25, 2025
    Software

    Generative AI and particularly LLMs (Large Language Models) have exploded into the public consciousness. Like many software developers I am intrigued by the possibilities, but unsure what exactly it will mean for our profession in the long run. I have now taken on a role in Thoughtworks to coordinate our work on how this technology will affect software delivery practices. I’m posting various memos here to describe what my colleagues and I are learning and thinking.

    I still care about the code (09 July 2025)

    Autonomous coding agents: A Codex example (04 June 2025)

    Building Custom Tooling with LLMs (14 May 2025) by Unmesh Joshi

    Coding Assistants Threaten the Software Supply Chain (13 May 2025) by Jim Gumbley and Lilly Ryan

    Building TMT Mirror Visualization with LLM: A Step-by-Step Journey (30 April 2025) by Unmesh Joshi

    Guiding an LLM for Robust Java ByteBuffer Code (17 April 2025) by Unmesh Joshi

    The role of developer skills in agentic coding (25 March 2025)

    What role does LLM reasoning play for software tasks? (18 February 2025)

    Expanding the solution size with multi-file editing (19 November 2024)

    Building an AI agent application to migrate a tech stack (20 August 2024)

    Onboarding to a ‘legacy’ codebase with the help of AI (15 August 2024)

    How to tackle unreliability of coding assistants (29 November 2023)

    How is GenAI different from other code generators? (19 September 2023)

    TDD with GitHub Copilot (17 August 2023) by Paul Sobocinski

    Coding assistants do not replace pair programming (10 August 2023)

    In-line assistance – how can it get in the way? (03 August 2023)

    In-line assistance – when is it more useful? (01 August 2023)

    Median – A tale in three functions (27 July 2023)

    The toolchain (26 July 2023)

    If you’re wondering why we use a donkey in our series image, read why I made up a persona for an eager, yet unreliable, coding assistant.


    Source: Martin Fowler.

Previous Page
1 … 907 908 909 910 911
Next Page
MONIMEGA
  • Instagram
  • Facebook
  • Twitter
Gestisci Consenso
Per fornire le migliori esperienze, utilizziamo tecnologie come i cookie per memorizzare e/o accedere alle informazioni del dispositivo. Il consenso a queste tecnologie ci permetterà di elaborare dati come il comportamento di navigazione o ID unici su questo sito. Non acconsentire o ritirare il consenso può influire negativamente su alcune caratteristiche e funzioni.
Funzionale Always active
L'archiviazione tecnica o l'accesso sono strettamente necessari al fine legittimo di consentire l'uso di un servizio specifico esplicitamente richiesto dall'abbonato o dall'utente, o al solo scopo di effettuare la trasmissione di una comunicazione su una rete di comunicazione elettronica.
Preferenze
L'archiviazione tecnica o l'accesso sono necessari per lo scopo legittimo di memorizzare le preferenze che non sono richieste dall'abbonato o dall'utente.
Statistiche
L'archiviazione tecnica o l'accesso che viene utilizzato esclusivamente per scopi statistici. L'archiviazione tecnica o l'accesso che viene utilizzato esclusivamente per scopi statistici anonimi. Senza un mandato di comparizione, una conformità volontaria da parte del vostro Fornitore di Servizi Internet, o ulteriori registrazioni da parte di terzi, le informazioni memorizzate o recuperate per questo scopo da sole non possono di solito essere utilizzate per l'identificazione.
Marketing
L'archiviazione tecnica o l'accesso sono necessari per creare profili di utenti per inviare pubblicità, o per tracciare l'utente su un sito web o su diversi siti web per scopi di marketing simili.
  • Manage options
  • Manage services
  • Manage {vendor_count} vendors
  • Read more about these purposes
Visualizza le preferenze
  • {title}
  • {title}
  • {title}