Last year, Linus Torvalds openly admitted his regret to ever allowing bcachefs support to be added to the Linux kernel, when he stated the following in a response to the bcachefs pull request: “Yeah, no, enough is enough. The last pull was already big. This is too big, it touches non-bcachefs stuff, and it’s not even remotely some kind of regression. At some point, ‘fix something’ just turns into development, and this is that point.”
Torvalds continued, “Nobody sane uses bcachefs and expects it to be stable, so every single user is an experimental site.” He went on to say “The bcachefs patches have become these kinds of ‘lots of development during the release cycles rather than before it’, to the point where I’m starting to regret merging bcachefs.” He concluded with, “This is getting beyond ridiculous.”
The clash continued to be heated. Because of Torvalds’s strict release cycle, the Linux creator decided (after the lead bcachefs developer submitted large changes for the new <I>journal_rewind<I> feature) that he’d had enough.
In the end, Torvalds pulled support for Bcachefs for the 6.16-rc3 kernel release and notified the developer that it wouldn’t be included in the 6.17 merge window.
In another communication on the Linux Kernel Mailing List, Torvalds put the final kibosh on the situation when he stated “Honestly, at that point, I don’t really feel comfortable being involved at all, and the only thing we both seemed to really fundamentally agree on in that discussion was ‘we’re done’.”
The core of Tailwind are its utilities. This means you have two choices:
The default choice
The unorthodox choice
The default choice
The default choice is to follow Tailwind’s recommended layer order: place components first, and Tailwind utilities last.
So, if you’re building components, you need to manually wrap your components with a @layer directive. Then, overwrite your component styles with Tailwind, putting Tailwind as the “most important layer”.
/* Write your components */ @layer components { .component { /* Your CSS here */ } }
But, being the bad boy I am, I don’t take the default approach as the “best” one. Over a year of (major) experimentation with Tailwind and vanilla CSS, I’ve come across what I believe is a better solution.
The Unorthodox Choice
Before we go on, I have to tell you that I’m writing a course called Unorthodox Tailwind — this shows you everything I know about using Tailwind and CSS in synergistic ways, leveraging the strengths of each.
Shameless plug aside, let’s dive into the Unorthodox Choice now.
In this case, the Unorthodox Choice is to write your styles in an unnamed layer — or any layer after utilities, really — so that your CSS naturally overwrites Tailwind utilities.
/* Named layer option */ /* Use whatever layer name you come up with. I simply used css here because it made most sense for explaining things */ @layer theme, base, components, utilities, css; @layer css { .component { /* ... */ } }
I have many reasons why I do this:
I don’t like to add unnecessary CSS layers because it makes code harder to write — more keystrokes, having to remember the specific layer I used it in, etc.
I’m pretty skilled with ITCSS, selector specificity, and all the good-old-stuff you’d expect from a seasoned front-end developer, so writing CSS in a single layer doesn’t scare me at all.
I can do complex stuff that are hard or impossible to do in Tailwind (like theming and animations) in CSS.
Your mileage may vary, of course.
Now, if you have followed my reasoning so far, you would have noticed that I use Tailwind very differently:
Tailwind utilities are not the “most important” layer.
My unnamed CSS layer is the most important one.
I do this so I can:
Build prototypes with Tailwind (quickly, easily, especially with the tools I’ve created).
Shift these properties to CSS when they get more complex — so I don’t have to read messy utility-littered HTML that makes my heart sink. Not because utility HTML is bad, but because it takes lots of brain processing power to figure out what’s happening.
Finally, here’s the nice thing about Tailwind being in a utility layer: I can always !important a utility to give it strength.
Whoa, hold on, wait a minute! Isn’t this wrong, you might ask?
Nope. The !important keyword has traditionally been used to override classes. In this case, we’re leveraging on the !important feature in CSS Layers to say the Tailwind utility is more important than any CSS in the unnamed layer.
This is perfectly valid and is a built-in feature for CSS Layers.
Besides, the !important is so explicit (and used so little) that it makes sense for one-off quick-and-dirty adjustments (without creating a brand new selector for it).
Tailwind utilities are more powerful than they seem
Tailwind utilities are not a 1:1 map between a class and a CSS property. Built-in Tailwind utilities mostly look like this so it can give people a wrong impression.
Tailwind utilities are more like convenient Sass mixins, which means we can build effective tools for layouts, theming, typography, and more, through them.
For many of us, July is the epitome of summer. The time for spending every free minute outside to enjoy the sun and those seemingly endless summer days, whether it’s in a nearby park, by a lake, or on a trip exploring new places. So why not bring a bit of that summer joy to your desktop, too?
For this wallpapers post, artists and designers from across the globe once again tickled their creativity and designed desktop wallpapers that capture that very special July feeling — just like it has been a monthly tradition here at Smashing Magazine for more then 14 years already. You’ll find their artworks compiled below, along with a selection of summery favorites from our wallpapers archives that are just too good to be forgotten. A huge thank-you to everyone who shared their designs with us this month — this post wouldn’t exist without you!
If you, too, would like to get featured in one of our upcoming wallpapers posts, please don’t hesitate to submit your design. We can’t wait to see what you’ll come up with! Happy July!
You can click on every image to see a larger preview.
We respect and carefully consider the ideas and motivation behind each and every artist’s work. This is why we give all artists the full freedom to explore their creativity and express emotions and experience through their works. This is also why the themes of the wallpapers weren’t anyhow influenced by us but rather designed from scratch by the artists themselves.
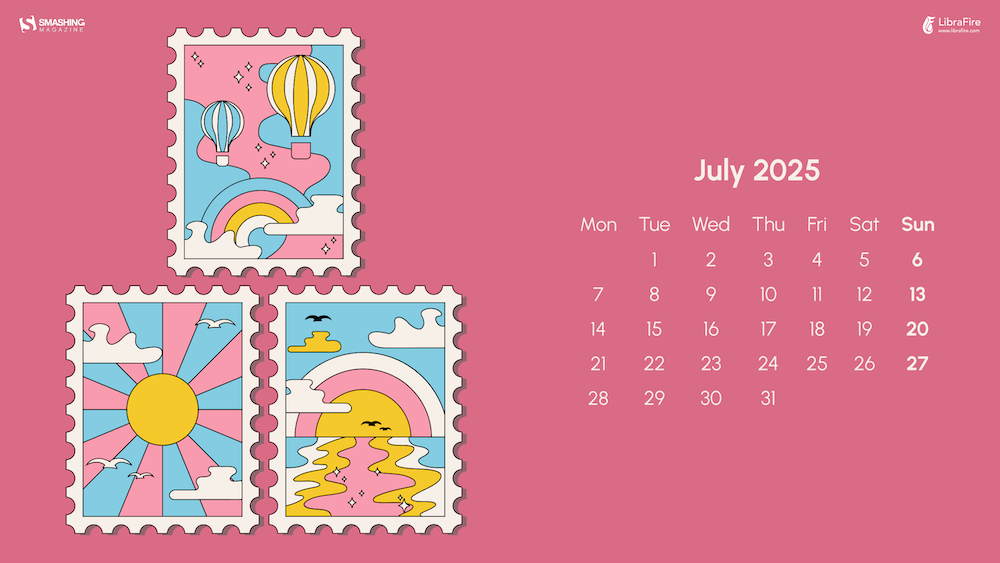
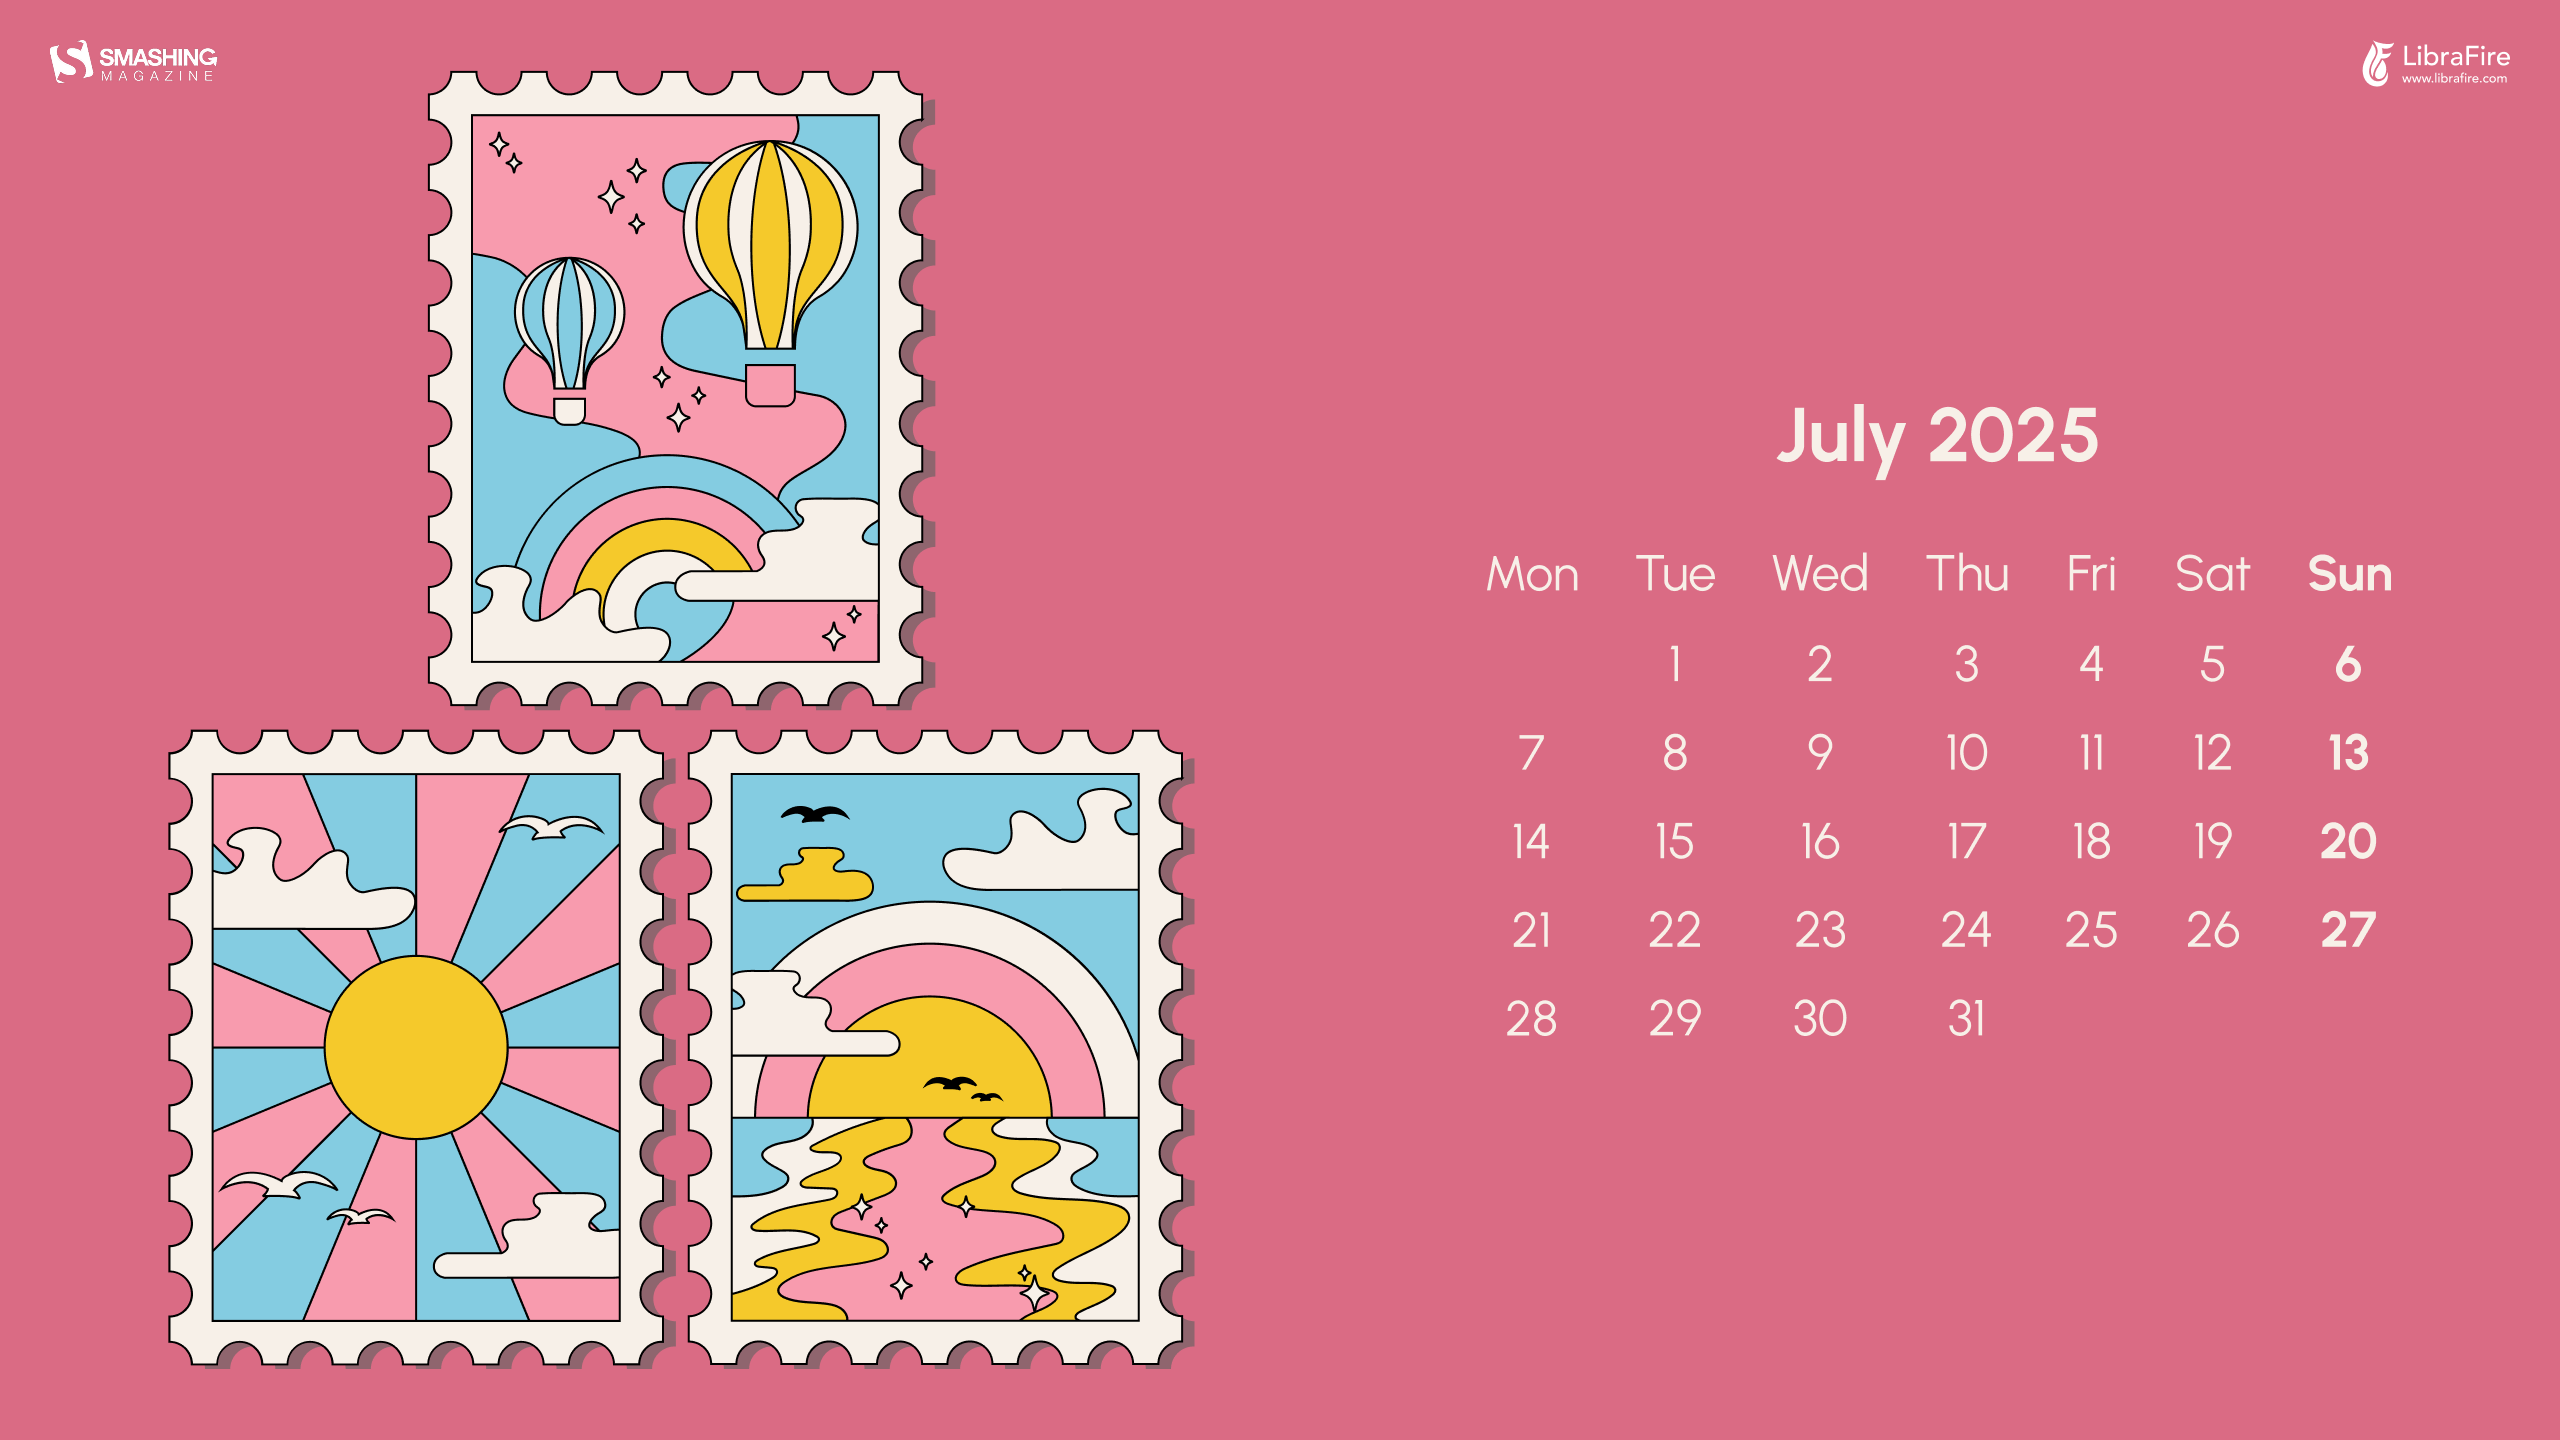
Stamped In Summer
“Moments of July marked in sunlight, sea breeze, and sky — a quiet snapshot of summer, worn at the edges like a well-traveled postcard.” — Designed by Libra Fire from Serbia.
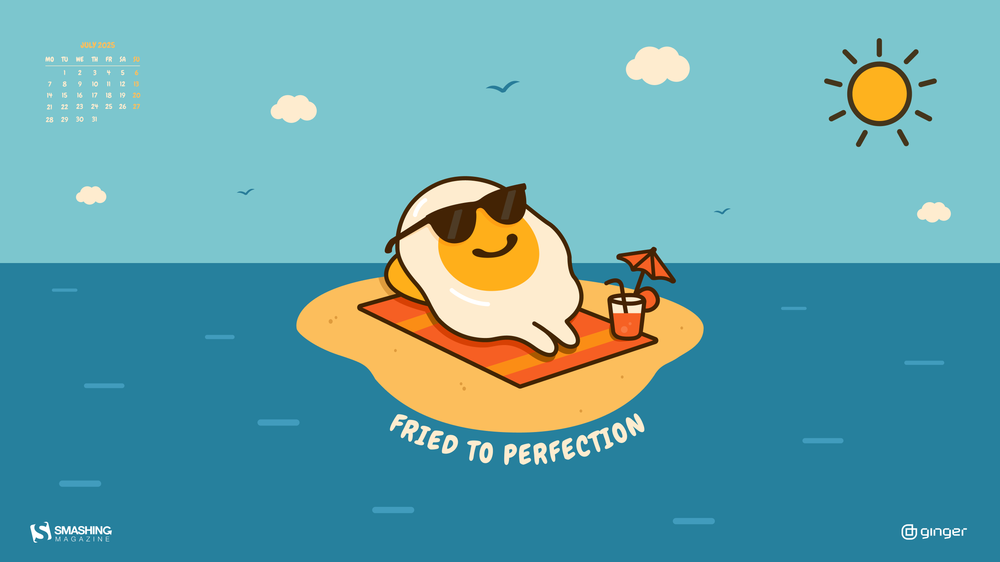
“This egg knows what July is all about. Soaking up the sun, relaxing without a care, and letting the warmth do its magic. Whether it’s a full vacation or just a quiet afternoon, take a moment to pause and recharge. You deserve it.” — Designed by Ginger IT Solutions from Serbia.
“Before going on holidays, let’s clean up your desk! Choose this wallpaper with shapes in disorder, and then you will have to reorder your desktop shortcuts.” — Designed by Philippe Brouard from France.
“Summer is here, and this month we share it with Virginia Apgar, a great woman who, thanks to her famous Apgar test applied to newborns, has reduced infant mortality worldwide.” — Designed by Veronica Valenzuela from Spain.
“The long-awaited vacation is coming closer. After working all year, we find ourselves with months that, although we don’t stop completely, are lived differently. We enjoy the days and nights more, and if we can, the beach will keep us company. Therefore, we’ll spend this month in Australia, enjoying the coral reefs and diving without limits.” — Designed by Veronica Valenzuela from Spain.
“Summer is coming in the northern hemisphere and what better way to enjoy it than with watermelons and cannonballs.” — Designed by Maria Keller from Mexico.
“July in South Africa is dreary and wintery so we give all the southern hemisphere dwellers a bit of color for those gray days. And for the northern hemisphere dwellers a bit of pop for their summer!” — Designed by Wonderland Collective from South Africa.
“And once you let your imagination go, you find yourself surrounded by eternal summer, unexplored worlds, and all-pervading warmth, where there are no rules of physics and colors tint the sky under your feet.” — Designed by Ana Masnikosa from Belgrade, Serbia.
“July is the middle of summer, when most of us go on road trips, so I designed a calendar inspired by my love of traveling and summer holidays.” — Designed by Patricia Coroi from Romania.
“Rain has come, showering the existence with new seeds of life. Everywhere life is blooming, as if they were asleep and the falling music of raindrops have awakened them. Feel the drops of rain. Feel this beautiful mystery of life. Listen to its music, melt into it.” — Designed by DMS Software from India.
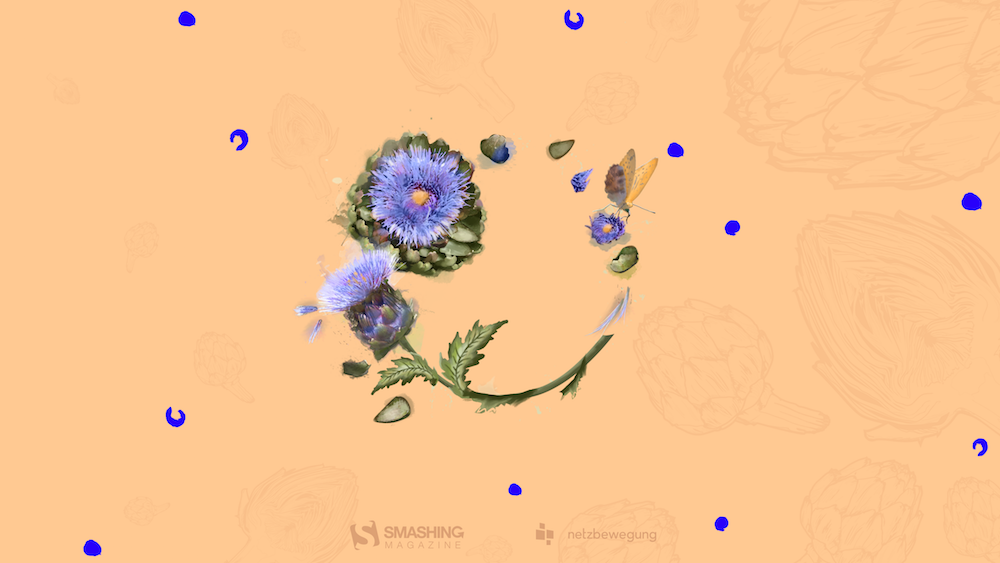
“In times of clean eating and the world of superfoods there is one vegetable missing. An old, forgotten one. A flower actually. Rare and special. Once it had a royal reputation (I cheated a bit with the blue). The artichocke — this is my superhero in the garden! I am a food lover — you too? Enjoy it, dip it!” — Designed by Alexandra Tamgnoué from Germany.
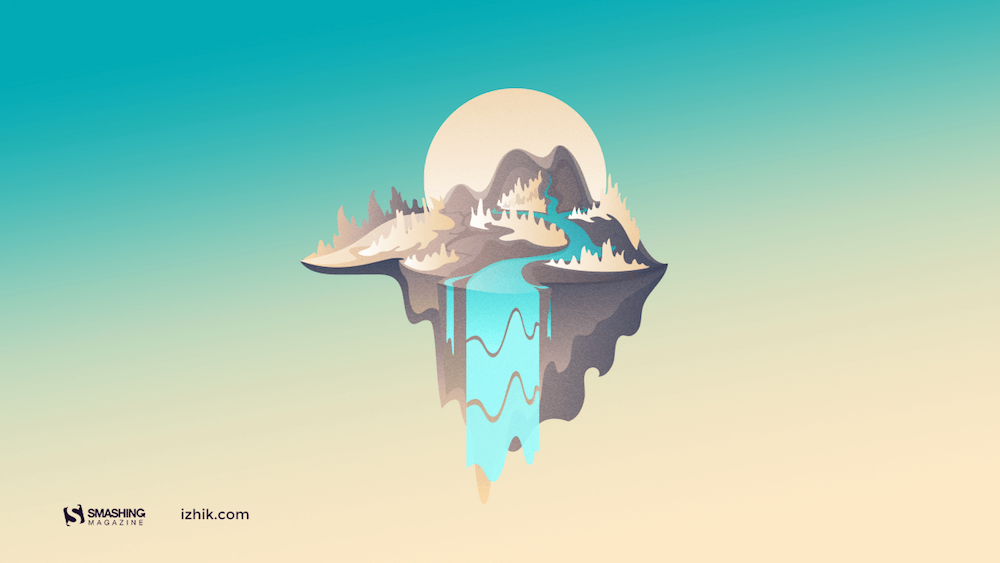
“Make sure you have a refreshing source of ideas, plans, and hopes this July. Especially if you are to escape from urban life for a while.” — Designed by Igor Izhik from Canada.
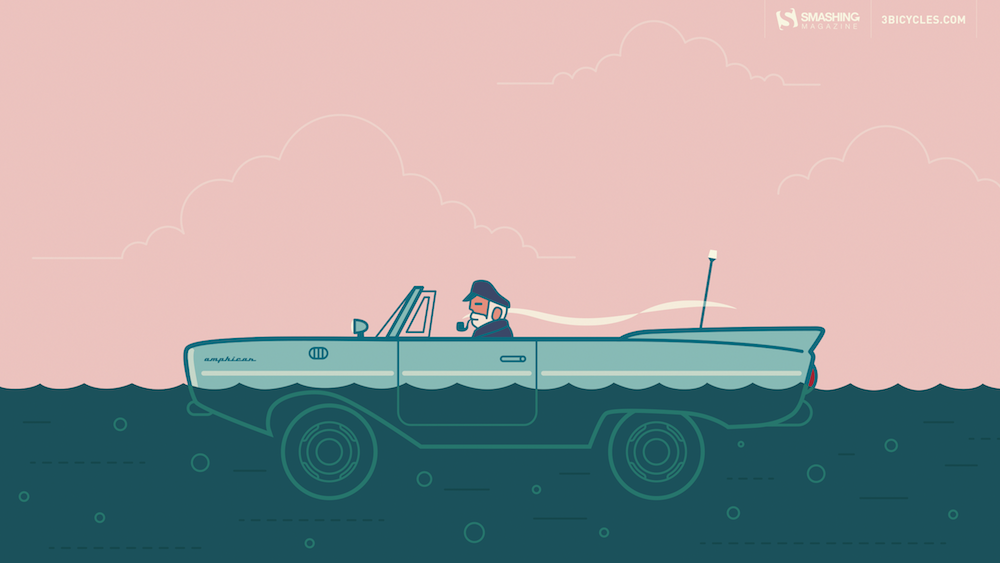
“My son and I are obsessed with the Amphicar right now, so why not have a little fun with it?” — Designed by 3 Bicycles Creative from the United States.
“Ever watched Joe’s Apartment when you were a kid? Well, that movie left a soft spot in my heart for the little critters. Don’t get me wrong: I won’t invite them over for dinner, but I won’t grab my flip flop and bring the wrath upon them when I see one running in the house. So there you have it… three roaches… bringing the smack down on that pesky human… ZZZZZZZAP!!” — Designed by Wonderland Collective from South Africa.
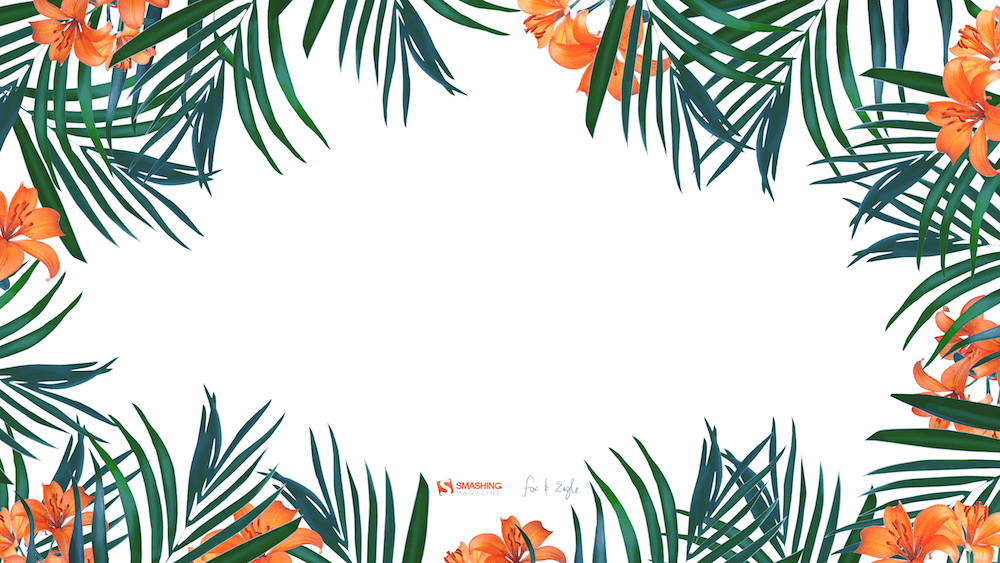
“I enjoy creating tropical designs. They fuel my wanderlust and passion for the exotic, instantaneously transporting me to a tropical destination.” — Designed by Tamsin Raslan from the United States.
“What’s better than a starry summer night with an (unexpected) friend around a fire camp with some marshmallows? Happy July!” — Designed by Etienne Mansard from the UK.
“July often brings summer heat and we all wish for something cold to take it away… If you take a closer look, you will see an ice cream melting from the sunset. Bon appetit!” — Designed by PopArt Studio from Serbia.
It should come as no surprise that nearly every office suite has introduced AI in some form or another, including ones that run on the open source Linux OS. ONLYOFFICE v9 follows the trend with AI-powered virtual assistants.
The AI enhancements in ONLYOFFICE v9 include automatic text extraction for PDF files, smart automation for macros, smart formulas for complex data analysis in spreadsheets, macro creation based on prompts, and conversion of VBA macros to ONLYOFFICE macros.
AI isn’t the only addition to ONLYOFFICE 9.0, as you’ll find a pair of brand new themes, Modern Light and Modern Dark, that give the user interface some serious polish (note: the classic themes are still available to use). There’s also a redesigned Start page, a new Diagram Viewer, support for new file formats (such as Markdown, OpenDocument graphic files, and Excel binary workbook files), drag-and-drop recording of PDF pages, asynchronous calculations in the spreadsheet editor, ability to enable/disable spelling language detection in Linux, and much more. Of course, there’s also the usual bug fixes and performance enhancements.
Blob, Blob, Blob. You hate them. You love them. Personally, as a design illiterate, I like to overuse them… a lot. And when you repeat the same process over and over again, it’s only a question of how much you can optimize it, or in this case, what’s the easiest way to create blobs in CSS? Turns out, as always, there are many approaches.
To know if our following blobs are worth using, we’ll need them to pass three tests:
They can be with just a single element (and preferably without pseudos).
They can be easily designed (ideally through an online tool).
We can use gradient backgrounds, borders, shadows, and other CSS effects on them.
Without further ado, let’s Blob, Blob, Blob right in.
Just generate them online
I know it’s disenchanting to click on an article about making blobs in CSS just for me to say you can generate them outside CSS. Still, it’s probably the most common way to create blobs on the web, so to be thorough, these are some online tools I’ve used before to create SVG blobs.
Haikei. Probably the one I have used the most since, besides blobs, it can also generate lots of SVG backgrounds.
Blobmaker. A dedicated tool for making blobs. It’s apparently part of Haikei now, so you can use both.
Lastly, almost all graphic programs let you hand-draw blobs and export them as SVGs.
For example, this is one I generated just now. Keep it around, as it will come in handy later.
While counterintuitive, we can use the border-radius property to create blobs. This technique isn’t new by any means; it was first described by Nils Binder in 2018, but it is still fairly unknown. Even for those who use it, the inner workings are not entirely clear.
To start, you may know the border-radius is a shorthand to each individual corner’s radius, going from the top left corner clockwise. For example, we can set each corner’s border-radius to get a bubbly square shape:
<div class="blob"></div>
.blob { border-radius: 25% 50% 75% 100%; }
CodePen Embed Fallback
However, what border-radius does — and also why it’s called “radius” — is to shape each corner following a circle of the given radius. For example, if we set the top left corner to 25%, it will follow a circle with a radius 25% the size of the shape.
.blob { border-top-left-radius: 25%; }
CodePen Embed Fallback
What’s less known is that each corner property is still a shortcut towards its horizontal and vertical radii. Normally, you set both radii to the same value, getting a circle, but you can set them individually to create an ellipse. For example, the following sets the horizontal radius to 25% of the element’s width and the vertical to 50% of its height:
.blob { border-top-left-radius: 25% 50%; }
CodePen Embed Fallback
We can now shape each corner like an ellipse, and it is the combination of all four ellipses that creates the illusion of a blob! Just take into consideration that to use the horizontal and vertical radii syntax through the border-radius property, we’ll need to separate the horizontal from the vertical radii using a forward slash (/).
The syntax isn’t too intuitive, so designing a blob from scratch will likely be a headache. Luckily, Nils Binder made a tool exactly for that!
Blobbing blobs together
This hack is awesome. We aren’t supposed to use border-radius like that, but we still do. Admittedly, we are limited to boring blobs. Due to the nature of border-radius, no matter how hard we try, we will only get convex shapes.
Just going off border-radius, we can try to minimize it a little by sticking more than one blob together:
CodePen Embed Fallback
However, I don’t want to spend too much time on this technique since it is too impractical to be worth it. To name a few drawbacks:
We are using more than one element or, at the very least, an extra pseudo-element. Ideally, we want to keep it to one element.
We don’t have a tool to prototype our blobby amalgamations, so making one is a process of trial and error.
We can’t use borders, gradients, or box shadows since they would reveal the element’s outlines.
Multiple backgrounds and SVG filters
This one is an improvement in the Gooey Effect, described here by Lucas Bebber, although I don’t know who first came up with it. In the original effect, several elements can be morphed together like drops of liquid sticking to and flowing out of each other:
CodePen Embed Fallback
It works by first blurring shapes nearby, creating some connected shadows. Then we crank up the contrast, forcing the blur out and smoothly connecting them in the process. Take, for example, this demo by Chris Coyer (It’s from 2014, so more than 10 years ago!):
CodePen Embed Fallback
If you look at the code, you’ll notice Chris uses the filter property along the blur() and contrast() functions, which I’ve also seen in other blob demos. To be specific, it applies blur() on each individual circle and then contrast() on the parent element. So, if we have the following HTML:
However, there is a good reason why those demos stick to white shapes and black backgrounds (or vice versa) since things get unpredictable once colors aren’t contrast-y enough. See it for yourself in the following demo by changing the color. Just be wary: shades get ugly.
CodePen Embed Fallback
To solve this, we will use an SVG filter instead. I don’t want to get too technical on SVG (if you want to, read Luca’s post!). In a nutshell, we can apply blurring and contrast filters using SVGs, but now, we can also pick which color channel we apply the contrast to, unlike normal contrast(), which modifies all colors.
Since we want to leave color channels (R, G and B) untouched, we will only crank the contrast up for the alpha channel. That translates to the next SVG filter, which can be embedded in the HTML:
To apply it, we will use again filter, but this time we’ll set it to url("#blob"), so that it pulls the SVG from the HTML.
.blob { filter: url("#blob"); }
And now we can even use it with gradient backgrounds!
CodePen Embed Fallback
That being said, this approach comes with two small, but important, changes to common CSS filters:
The filter is applied to the parent element, not the individual shapes.
The parent element must be transparent (which is a huge advantage). To change the background color, we can instead change the body or other ancestors’ background, and it will work with no issues.
What’s left is to place the .subblob elements together such that they make a blobby enough shape, then apply the SVG filters to morph them:
CodePen Embed Fallback
Making it one element
This works well, but it has a similar issue to the blob we made by morphing several border-radius instances: too many elements for a simple blob. Luckily, we can take advantage of the background property to create multiple shapes and morph them together using SVG filters, all in a single element. Since we are keeping it to one element, we will go back to just one empty .blob div:
<div class="blob"></div>
To recap, the background shorthand can set all background properties and also set multiple backgrounds at once. Of all the properties, we only care about the background-image, background-position and background-size.
First, we will use background-image along with radial-gradient() to create a circle inside the element:
farthest-side: Confines the shape to the element’s box farthest from its center. This way, it is kept as a circle.
var(--blob-color) 100%: Fills the background shape from 0 to 100% with the same color, so it ends up as a solid color.
#0000: After the shape is done, it makes a full stop to transparency, so the color ends.
The next part is moving and resizing the circle using the background-position and background-size properties. Luckily, both can be set on background after the gradient, separated from each other by a forward slash (/).
The first pair of percentages sets the shape’s horizontal and vertical position (taking as a reference the top-left corner), while the second pair sets the shape’s width and height (taking as a reference the element’s size).
As I mentioned, we can stack up different backgrounds together, which means we can create as many circles/ellipses as we want! For example, we can create three ellipses on the same element:
What’s even better is that SVG filters don’t care whether shapes are made of elements or backgrounds, so we can also morph them together using the last url(#blob) filter!
CodePen Embed Fallback
While this method may be a little too much for blobs, it unlocks squishing, stretching, dividing, and merging blobs in seamless animations.
Again, all these tricks are awesome, but not enough for what we want! We accomplished reducing the blob to a single element, but we still can’t use gradients, borders, or shadows on them, and also, they are tedious to design and model. Then, that brings us to the ultimate blob approach…
Using the shape() function
Fortunately, there is a new way to make blobs that just dropped to CSS: the shape() function!
First off, the CSS shape() function is used alongside the clip-path property to cut elements into any shape we want. More specifically, it uses a verbal version of SVG’s path syntax. The syntax has lots of commands for lots of types of lines, but when blobbing with shape(), we’ll define curves using the curve command:
.blob { clip-path: shape( from X0 Y0, curve to X1 Y1 with Xc1 Yc1, curve to X2 Y2 with Xc21 Yc21 / Xc22 Yc22 /* ... */ ); }
Let’s break down each parameter:
X0 Y0 defines the starting point of the shape.
curve starts the curve where X1 Y1 is the next point of the shape, while Xc1 Yc1 defines a control point used in Bézier curves.
The next parameter is similar, but we used Xc21 Yc21 / Xc22 Yc22 instead to define two control points on the Bézier curve.
I honestly don’t understand Bézier curves and control points completely, but luckily, we don’t need them to use shape() and blobs! Again, shape() uses a verbal version of SVG’s path syntax, so it can draw any shape an SVG can, which means that we can translate the SVG blobs we generated earlier… and CSS-ify them. To do so, we’ll grab the d attribute (which defines the path) from our SVG and paste it into Temani’s SVG to shape() generator.
This is the exact code the tool generated for me:
.blob { aspect-ratio: 0.925; /* Generated too! */ clip-path: shape( from 91.52% 26.2%, curve to 93.52% 78.28% with 101.76% 42.67%/103.09% 63.87%, curve to 44.11% 99.97% with 83.95% 92.76%/63.47% 100.58%, curve to 1.45% 78.42% with 24.74% 99.42%/6.42% 90.43%, curve to 14.06% 35.46% with -3.45% 66.41%/4.93% 51.38%, curve to 47.59% 0.33% with 23.18% 19.54%/33.13% 2.8%, curve to 91.52% 26.2% with 62.14% -2.14%/81.28% 9.66% ); }
As you might have guessed, it returns our beautiful blob:
CodePen Embed Fallback
Let’s check if it passes our requirements:
Yes, they can be made of a single element.
Yes, they can also be created in a generator and then translated into CSS.
Yes, we can use gradient backgrounds, but due to the nature of clip-path(), borders and shadows get cut out.
Two out of three? Maybe two and a half of three? That’s a big improvement over the other approaches, even if it’s not perfect.
Conclusion
So, alas, we failed to find what I believe is the perfect CSS approach to blobs. I am, however, amazed how something so trivial designing blobs can teach us about so many tricks and new CSS features, many of which I didn’t know myself.
KelpUI is new library that Chris Ferdinandi is developing, designed to leverage newer CSS features and Web Components. I’ve enjoyed following Chris as he’s published an ongoing series of articles detailing his thought process behind the library, getting deep into his approach. You really get a clear picture of his strategy and I love it.
He outlined his principles up front in a post back in April:
I’m imagining a system that includes…
Base styles for all of the common HTML elements.
Loads of utility classes for nudging and tweaking things.
Group classes for styling more complex UI elements without a million little classes.
Easy customization with CSS variables.
Web Components to progressively add interactivity to functional HTML.
All of the Web Component HTML lives in the light DOM, so its easy to style and reason about.
I’m imagining something that can be loaded directly from a CDN, downloaded locally, or imported if you want to roll your own build.
KelpUI is still evolving, and that’s part of the beauty of looking at it now and following Chris’s blog as he openly chronicles his approach. There’s always going to be some opinionated directions in a library like this, but I love that the guiding philosophy is so clear and is being used as a yardstick to drive decisions. As I write this, Chris is openly questioning the way he optimizes the library, demonstrating the tensions between things like performance and a good developer experience.
Looks like it’ll be a good system, but even more than that, it’s a wonderful learning journey that’s worth following.
Chrome 137 shipped the if() CSS function, so it’s totally possible we’ll see other browsers implement it, though it’s tough to know exactly when. Whatever the case, if() enables us to use values conditionally, which we can already do with queries and other functions (e.g., media queries and the light-dark() function), so I’m sure you’re wondering: What exactly does if() do?
To recap, if() conditionally assigns a value to a property based on the value of a CSS variable. For example, we could assign different values to the color and background properties based on the value of --theme:
--theme: "Shamrock"
color: hsl(146 50% 3%)
background: hsl(146 50% 40%)
--theme: Anything else
color: hsl(43 74% 3%)
background: hsl(43 74% 64%)
:root { /* Change to fall back to the ‘else’ values */ --theme: "Shamrock"; body { color: if(style(--theme: "Shamrock"): hsl(146 50% 3%); else: hsl(43 74% 3%)); background: if(style(--theme: "Shamrock"): hsl(146 50% 40%); else: hsl(43 74% 64%)); } }
CodePen Embed Fallback
I don’t love the syntax (too many colons, brackets, and so on), but we can format it like this (which I think is a bit clearer):
We should be able to do a crazy number of things with if(), and I hope that becomes the case eventually, but I did some testing and learned that the syntax above is the only one that works. We can’t base the condition on the value of an ordinary CSS property (instead of a custom property), HTML attribute (using attr()), or any other value. For now, at least, the condition must be based on the value of a custom property (CSS variable).
Exploring what we can do with if()
Judging from that first example, it’s clear that we can use if() for theming (and design systems overall). While we could utilize the light-dark() function for this, what if the themes aren’t strictly light and dark, or what if we want to have more than two themes or light and dark modes for each theme? Well, that’s what if() can be used for.
Pretty simple really, but there are a few easy-to-miss things. Firstly, there’s no “else condition” this time, which means that if the theme isn’t Shamrock, Saffron, or Amethyst, the default browser styles are used. Otherwise, the if() function resolves to the value of the first true statement, which is the Saffron theme in this case. Secondly, transitions work right out of the box; in the demo below, I’ve added a user interface for toggling the --theme, and for the transition, literally just transition: 300ms alongside the if() functions:
CodePen Embed Fallback
Note: if theme-swapping is user-controlled, such as selecting an option, you don’t actually need if() at all. You can just use the logic that I’ve used at the beginning of the demo (:root:has(#shamrock:checked) { /* Styles */ }). Amit Sheen has an excellent demonstration over at Smashing Magazine.
To make the code more maintainable though, we can slide the colors into CSS variables as well, then use them in the if() functions, then slide the if() functions themselves into CSS variables:
/* Setup */ :root { /* Shamrock | Saffron | Amethyst */ --theme: "Shamrock"; /* ...I choose you! */ /* Base colors */ --shamrock: hsl(146 50% 40%); --saffron: hsl(43 74% 64%); --amethyst: hsl(282 47% 56%); /* Base colors, but at 3% lightness */ --shamrock-complementary: hsl(from var(--shamrock) h s 3%); --saffron-complementary: hsl(from var(--saffron) h s 3%); --amethyst-complementary: hsl(from var(--amethyst) h s 3%); --background: if( style(--theme: "Shamrock"): var(--shamrock); style(--theme: "Saffron"): var(--saffron); style(--theme: "Amethyst"): var(--amethyst) ); --color: if( style(--theme: "Shamrock"): var(--shamrock-complementary); style(--theme: "Saffron"): var(--saffron-complementary); style(--theme: "Amethyst"): var(--amethyst-complementary) ); /* Usage */ body { /* One variable, all ifs! */ background: var(--background); color: var(--color); accent-color: var(--color); /* Can’t forget this! */ transition: 300ms; } }
CodePen Embed Fallback
As well as using CSS variables within the if() function, we can also nest other functions. In the example below, I’ve thrown light-dark() in there, which basically inverts the colors for dark mode:
If you haven’t used container style queries before, they basically check if a container has a certain CSS variable (much like the if() function). Here’s the exact same example/demo but with container style queries instead of the if() function:
As you can see, where if() facilitates conditional values, container style queries facilitate conditional properties and values. Other than that, it really is just a different syntax.
Additional things you can do with if() (but might not realize)
Check if a CSS variable exists:
/* Hide icons if variable isn’t set */ .icon { display: if( style(--icon-family): inline-block; else: none ); }
Although I’m not keen on the syntax and how unreadable it can sometimes look (especially if it’s formatted on one line), I’m mega excited to see how if() evolves. I’d love to be able to use it with ordinary properties (e.g., color: if(style(background: white): black; style(background: black): white);) to avoid having to set CSS variables where possible.
It’d also be awesome if calc() calculations could be calculated on the fly without having to register the variable.
That being said, I’m still super happy with what if() does currently, and can’t wait to build even simpler design systems.
Writing a sophisticated computer program often requires a lot of detailed knowledge. If we do this in Java, we need to know the syntax of the language, the wide range of libraries available to assist us in the work, the various tools required to verify and build our programs. If we do this in Python instead, we are faced with a different syntax, libraries that are named and work differently, a whole other ecosystem to build and run our work.
Faced with these details, a natural response is to recruit people who are knowledgeable about a specific ecosystem. Thus we see job descriptions that say “at least three years of Java”, or even deeper requirements for subsets of that community, with experience in specific tools. What use is a skilled Python programmer to such a team?
We’ve always felt that such desires are wrong-headed. The characteristics that we’ve observed separating effective software developers from the chaff aren’t things that depend on the specifics of tooling. We rather appreciate such things as: the knowledge of core concepts and patterns of programming, a knack for decomposing complex work-items into small, testable pieces, and the ability to collaborate with both other programmers and those who will benefit from the software.
Throw such a Python programmer into a Java team, and we’d expect them to prosper. Sure they would ask a lot of questions about the new language and libraries, we’d hear a lot of “how do you do this here?” But such questions are quickly answered, and the impediments of Java-ignorance soon wither away.
An experienced Pythonista who understands the core patterns and practices of software development can be a productive member of a team building software in Java. Knowing how to handle snakes can be surprisingly handy.
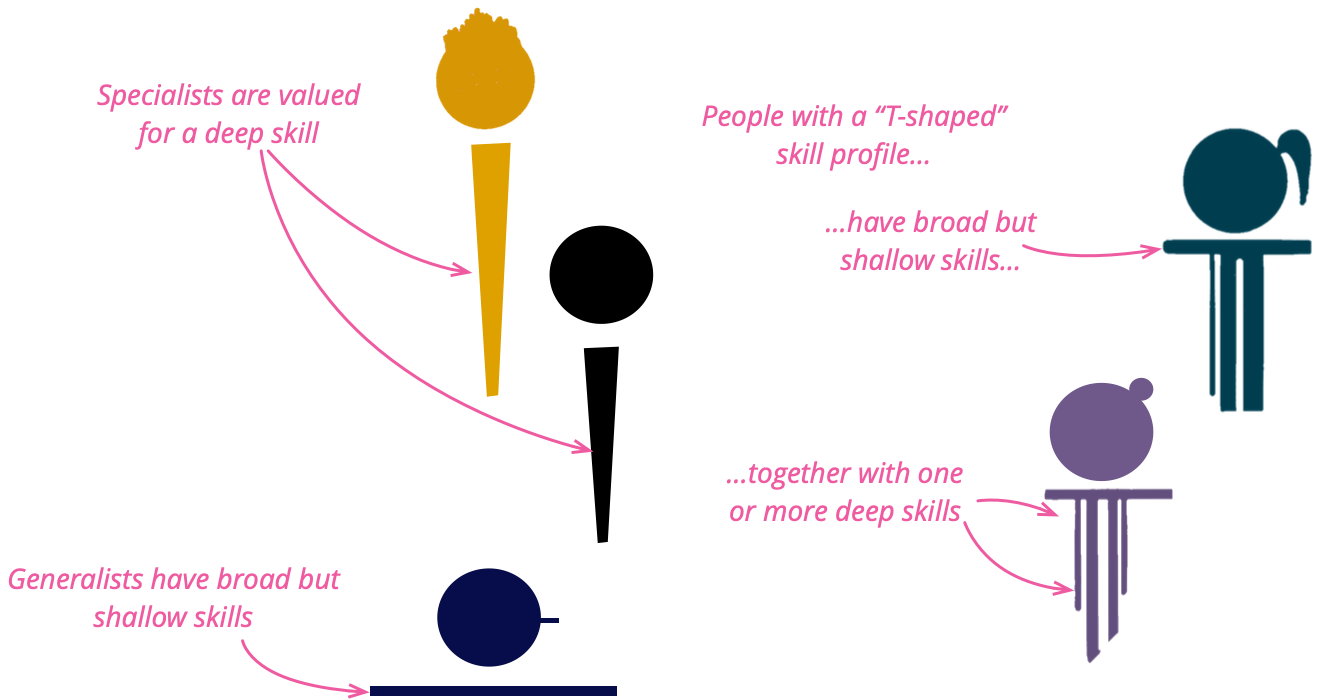
This echoes a long debate about the relative value of specialists and generalists. Specialists are seen as people with a deep skill in a specific subject, while generalists have broad but shallow skills. A dissatisfaction with that dichotomy led to the idea of “T-shaped people”: folks that combine deep knowledge in one topic, with a broad but shallow knowledge of many other topics. We’ve seen many such people quickly grow other deep legs, which doesn’t do much for the “T-shape” name (as we’ll discuss below), but otherwise leads to success. Often experience of a different environment leads to trying things that seem innovative in a new home. Folks that only work in a single technological neighborhood are at the constant risk of locking themselves into a knowledge silo, unaware of many tools that could help them in their work.
This ability goes beyond just developer skills. We’ve seen our best business analysts gain deep skills in a couple of domains, but use their generalist skills to rapidly understand and contribute in new domains. Developers and User Experience folks often step outside “their lanes” to contribute widely in getting work done. We’ve seen this capability be an essential quality in our best colleagues, to the degree that its importance is something we’ve taken for granted.
But increasingly we see the software industry push for increasing, narrower specialization.
So over the last year or so we have started to resist this industry-wide push for narrow skills, by calling out this quality, which we call an Expert Generalist. Why did we use the word “expert”? There are two sides to real expertise. The first is the familiar depth: a detailed command of one domain’s inner workings. The second, crucial in our fast-moving field is the ability to learn quickly, spot the fundamentals that run beneath shifting tools and trends, and apply them wherever we land. As an example from software teams, developers who roam across languages, architectures, and problem spaces may seem like “jack-of-all-trades, master-of-none,” yet repeated dives below surface differences help them develop durable, principle-level mastery. Over time these generalists can dissect unfamiliar challenges, spot first-principles patterns, and make confident design decisions with the assurance of a specialist – and faster. Being such a generalist is itself a sophisticated expertise.
We’ve long noticed that not just anyone succeeds as an Expert Generalist, but once we understand the traits that are key for such Expert Generalists, organizations can shape learning programs, hiring filters, and career paths that deliberately develop them. Indeed our hiring and career progression at Thoughtworks has been cultivating this skill for over two decades, but doing so informally. We think the industry needs to change gears, and treat Expert Generalist as a first-class skill in its own right: something we name, assess, and train for. (But beware, we find many Expert Generalists, including at least one author of this article, cringe at the word “expert”.)
When we’ve observed Expert Generalists, there are certain attributes that stand out.
Curiosity
Expert Generalists display a lot of curiosity. When confronted with a new technology or domain, their default reaction is to want to discover more about it, to see how it can be used effectively. They are quite happy to spend time just exploring the new topic area, building up some familiarity before using it in action. For most, learning new topics is a pleasure in itself, whether or not it’s immediately applicable to their work.
This characteristic is noticeable when Expert Generalists get an answer to a question. Rather than just typing in some code from Stack Overflow, an Expert Generalist’s curiosity usually motivates them to ensure they understand the answer, taking the opportunity to expand their knowledge, and check that the answer they got is appropriate. It’s also present when asking a question. There is an art to asking questions that elicit deeper answers without leading the witness.
Collaborativeness
Learning about a new topic area may require reading, watching videos, and prototyping. But we see the greatest aid here is another vital characteristic: collaborativeness. A wise Expert Generalist knows that they can never really learn about most of the things they run into. Their T-shape will grow several legs, but never enough to span all the things they need to know, let alone want to know. Working with people who do have those deeper skills is essential to being effective in new domains.
Working with an otherly-skilled worker allows the generalist to contribute while the skilled collaborator spots more effective paths that only a specialist would know. The generalist appreciates these corrections, learning from them. Learning involves both knowing more about the new domain, but also learning to differentiate between areas where the generalist can do primary contributions and areas where the generalist needs help from the specialist. We notice Expert Generalists are never afraid to ask for help, they know there is much they are ignorant of, and are eager to involve those who can navigate through those areas.
An effective combination of collaborative curiosity requires humility. Often when encountering new domains we see things that don’t seem to make sense. Effective generalists react to that by first understanding why this odd behavior is the way it is, because there’s usually a reason, indeed a good reason considering its context. Sometimes, that reason is no longer valid, or was missing an important consideration in the first place. In that situation a newcomer can add considerable value by questioning the orthodoxy. But at other times the reason was, and is still valid – at least to some extent. Humility encourages the Expert Generalist to not leap into challenging things until they are sure they understand the full context.
This humility extends to recognizing the different trade-offs we see across architectures. An architecture designed to support large volumes of simple transactions will differ from one designed to handle a few complex interactions. Expert Generalists are comfortable in a world where different trade-offs make sense in different circumstances, usually because their travels have exposed them to these differences.
Customer Focus
This curiosity and eagerness to collaborate with people with different skills does raise a danger. Someone driven by curiosity can chase every shiny object. This is where the characteristic of customer-focus comes into play. We are often impressed with how an Expert Generalist takes each unfamiliar technology and questions how it helps the customer. We are fans of Kathy Sierra’s notion that our purpose as software developers is to help our customers become “badass” at what they do.
Customer-focus is the necessary lens to focus curiosity. Expert generalists prioritize their attention on the things that will help them help their users to excel. This encourages learning about what their customers do, and how they can improve their work. It focuses attention on technologies that contribute to building those things. Customer-focus energizes collaboration, encouraging the exchange of information between customer and technologist, and allowing the Expert Generalist to coordinate other technologists towards enabling the customers’ excellence.
Favor Fundamental Knowledge
Software development is a vast field, where nobody can know everything, or even a reasonable fraction of everything, so we all need to prioritize what topics we learn. Expert Generalists favor fundamental knowledge, that doesn’t become outdated with changes when platforms update. These are often expressed as patterns or principles. Such knowledge tends to age slowly, and is applicable when folks move into new environments. For example the basic moves of refactoring are the same whatever language you are programming, the core patterns of distributed systems reappear regularly (and it’s no coincidence that’s why we wrote books on those topics – we like book sales that last for many years).
Blend of Generalist and Specialist Skills
Thus generalists often have deep knowledge of fundamentals, and we usually see them have deep knowledge of a few other topics too. They combine a broad general skill with several areas of deeper knowledge, usually acquired as it’s necessary for products they’ve worked on, coupled with the curiosity to dig into things that puzzle most people. These deeper areas may not be relevant to every engagement they work on, but is a signal for their acumen and curiosity. We’ve learned to be suspicious of people who present as a generalist yet don’t have a few deep specialties.
We mentioned before that a common name for this skills profile is that of the “T-shaped” person, implying a blend of specialist and generalist skills. While the T-shape moniker did catch on, it comes with a major problem in the metaphor, we don’t find such folks have only a single deeper skill. They usually have a few, of varying depth. We’re not the only people to identify this problem, and there have been several other names proposed to describe this skill-set, although the alternatives all have their own problems. 1
1: Kent Beck came up with the metaphor of “paint drip people”, although a problem with this metaphor is that paint-drips aren’t usually something we desire. “π-shape” at least admits two deeper skills, but again implies an arbitrary limit that doesn’t work in practice. “Comb-shaped” implies many deeper skills, which is good, but it also implies they are all the same depth, which isn’t true.
The vertical stroke of a skill set represents broader, long-lasting domains, not specific tools or frameworks. An expert generalist therefore pursues depth in distributed-data systems—partitioning and replication strategies, fault-tolerance mechanisms, consistency models, and consensus algorithms—instead of mastering only Databricks notebooks. In the cloud, they focus on cloud-native architecture: auto-scaling heuristics, multi-region fail-over etc rather than focusing on AWS-specific configuration syntax. On the front end, they study browser-based UI architecture—rendering pipelines, state-reconciliation patterns, and accessibility primitives—instead of the latest React APIs.
Sympathy for Related Domains
Expert generalists often find themselves in unfamiliar territory—be it a new software stack, a new domain, or a new role. Rather than chasing exhaustive detail from day one, they cultivate a rough, perceptive sense of what works in the new environment. That helps them make choices that go with the grain—even when it differs from their previous experience.
Jackie Stewart, a triple Formula 1 world champion (1969-93), described how, while he wasn’t an engineer of the cars he drove, he still needed a sense of how they worked, how they responded to what the driver was trying to do, a sense he called mechanical sympathy. Martin Thompson brought this concept into software, by talking about how a similar knowledge of how computer hardware works is vital to writing high-performance software.
We think that the notion of mechanical sympathy has a broader sense in software, in that we do need to cultivate such a sympathy for any adjacent domain to the ones we are working on. When working on a database design, we need such a sympathy for the user-interface so we can construct a design that will work smoothly with the user-experience. A user-experience designer needs such a sympathy with software constraints so when choosing between similarly valuable user flows, they take into account how hard it is to build them.
This also shows itself with new teams. When joining a new team, expert generalists tend to listen to the established ways that a team works, introducing different approaches thoughtfully. Even when coming in as leaders, they don’t default to tearing up existing workflows in favor of those more familiar to them. Their curiosity extends to understanding why different people work in different ways, trying out unfamiliar working styles, then incorporating their experience to develop practices to improve from the current state.
Assessing Expert Generalists
We have two crucial checkpoints for spotting —and then nurturing —expert generalists: the hiring interview and ongoing career progression.
Hiring
Traditional interview loops still revolve around product trivia—“Explain Spark’s shuffle stages,” “How does Databricks Delta time-travel work?” A candidate who has never touched those tools can still be exactly the kind of person we need: someone who quickly grasps unfamiliar concepts, breaks complex systems into manageable parts, and collaborates across functions. Focusing on a single stack or cloud provider risks filtering out such talent.
To surface that potential, widen the conversation beyond tool recall. Ask candidates to talk through past experiences:
How did they approach a particularly challenging situation?
When have they ventured into an unfamiliar domain, and how did they get up to speed?
How do they collaborate with people inside and outside their own organisation or discipline?
These stories reveal learning velocity, systems thinking, and people skills—the raw material of an expert generalist.
Example · Process-control engineer We once met an engineer whose entire résumé was industrial PLC work—no general-purpose language, no web, no cloud. Yet his record of diagnosing control-system failures and the questions he asked during the interview showed exceptional learning agility. Hired for those qualities, he grew into a respected technical leader and later a product owner. Rejecting him for not knowing “our” tools would have been a costly miss.
Career progression
Inside the organisation, narrow verticals can freeze growth: UI developers, QAs, data engineers, or cloud experts seldom step outside their lanes. The growth paths map one-to-one with vertical silos: UI Engineer → Senior UI Engineer → UI Architect, or Data Engineer → Senior Data Engineer → Principal Databricks Guru. The unintended message is, “wander outside your lane and your progress stalls.
We have found that encouraging people to experiment—letting them make mistakes and learn in adjacent disciplines—yields remarkable benefits. A business analyst writing code out of curiosity, a front-end engineer dabbling in DevOps, a data engineer trying product analysis: each cross-pollination broadens both the individual and the team.
Example · Medical-domain analyst A non-technical professional from healthcare joined us as a business analyst. His passion for tech pulled him into code reviews and pairing sessions. Over time he became an outstanding tech lead and a broader strategic thinker than many traditional “pure” engineers.
Both stories underscore the same lesson: if we base assessment and advancement solely on a checklist of tools, we forfeit the chance to work with brilliant, adaptable people—and we hamper the organisation’s ability to innovate.
Growing Expert Generalists
From Tools to Fundamentals
IT trends get triggered by pivotal inventions that enable new business opportunities. Product providers and tool vendors quickly build products, and the industry focus often shifts to expertise in tools and frameworks rather than the underlying technical trends. For example, in the 1990s, when graphical-user-interface two-tier architectures were popular, the essential skill was mastering Object-Oriented Programming — its iterative, collaborative design — yet most attention centred on tools like Rational Rose, the C++ programming language, and frameworks such as Microsoft Foundation Classes. When the Web arrived, understanding Web architecture and global-scale caching was crucial, but early hype gravitated toward technologies like J2EE. In today’s cloud era, with complex microservice based architectures, big-data technologies, and expansive DevOps toolchains, the foundational discipline of distributed systems is often overlooked while certifications in specific tools dominate.
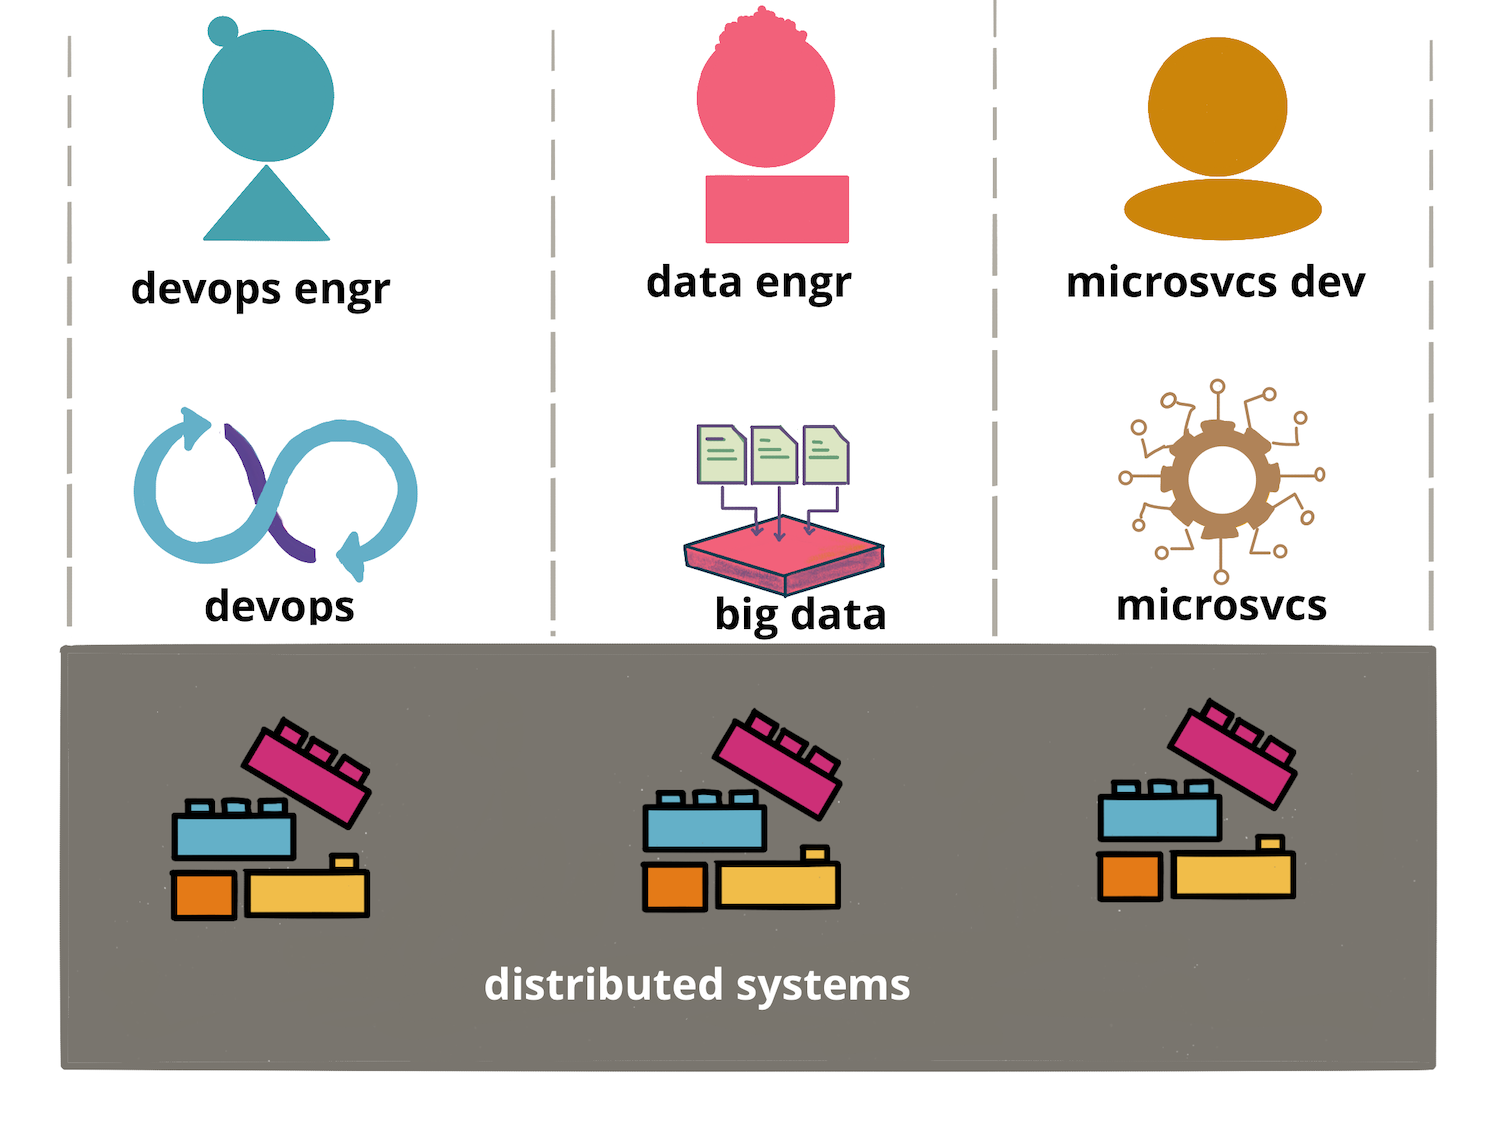
One of the biggest problems with excessive focus on tools and framework expertise is when it is cemented into organizational structures. Teams and organisations get structured around tool expertise, with hardened boundaries making it difficult for people from one team to acquire skills from others. Beyond language preferences like Python or Java, you can see this crystallise in the three most common software verticals—Application Development, Data Engineering, and DevOps. Are labels like “Application Development,” “DevOps,” and “Data Engineer” just harmless shorthand for the work we do? Not really. Once these words harden into career lanes, they solidify the very silos that the Agile and DevOps culture was meant to dismantle. The labels become an organisational anti-pattern—turning flow into a series of hand-offs when it should be a cross-functional sprint. All three share the same distributed-systems foundations, and anyone who masters those fundamentals can navigate all three without getting lost in each vertical’s ever-growing toolset. An expert generalist recognizes this and makes the deliberate effort to master those fundamentals.
Why does our attention keep drifting toward tool expertise? It isn’t because people are shortsighted or lazy; it’s because the fundamentals are hard to see amid the noise. Key ideas hide under stacks of product docs, YouTube tutorials, vendor blogs, and conference talks. At one end of the spectrum lie dense academic papers and university courses; at the other, vendor certifications tied to a single product. Connecting these dots — cutting through the surface to reach the essentials — takes deliberate effort. One proven aid is the language of patterns: reusable problem-solution pairs that capture the core principle without the brand labels. That’s why we belive in investing in exploring, distilling, and sharing such patterns — so the industry conversation can shift from “Which tool should I learn next?” to “Which underlying principles and patterns must I master?”
In our experience, the good grasp of this common language of patterns and principles also strengthens the product-service partnership. Today the relationship is often one-way: product teams ship features, service teams consume APIs. Product teams decide how to certify an engineer as an expert in a product and service teams aim to do those certifications. Cloud providers and tool vendors often demand a certain number of “certified professionals” before they will recognise a service provider as a competent partner. Yet our experience shows little correlation between certifications and competence. The focus on fundamentals pays off when competence is most needed: an engineer versed in Raft can untangle a Kubernetes control-plane stall that might puzzle several certified admins, and a Delta Lake write anomaly can be resolved from first-principles reasoning about optimistic-concurrency control instead of searching vendor docs. Once developers across roles share the lingua franca of a system’s internals, the partnership becomes bidirectional — both sides can diagnose, propose, and refine solutions together. Better yet, the engineers who have a good grasp of the fundamentals are able to partner well with multiple product and platform teams, without needing to have product specific training for each product
An Example Workshop: Breaking silos and building partnerships
We’ve seen that we can grow the Expert Generalist skill through mentoring and exposure to varied ecosystems, but one of the consequences of recognizing Expert Generalist as a first-class skill is that we should provide training in a similar way that we do with specialist skills. Such training currently barely exists in our profession. We’ve begun to fill that gap with workshops that are deliberately focused on developing the Expert Generalist competence, and we think there should be more training along these lines.
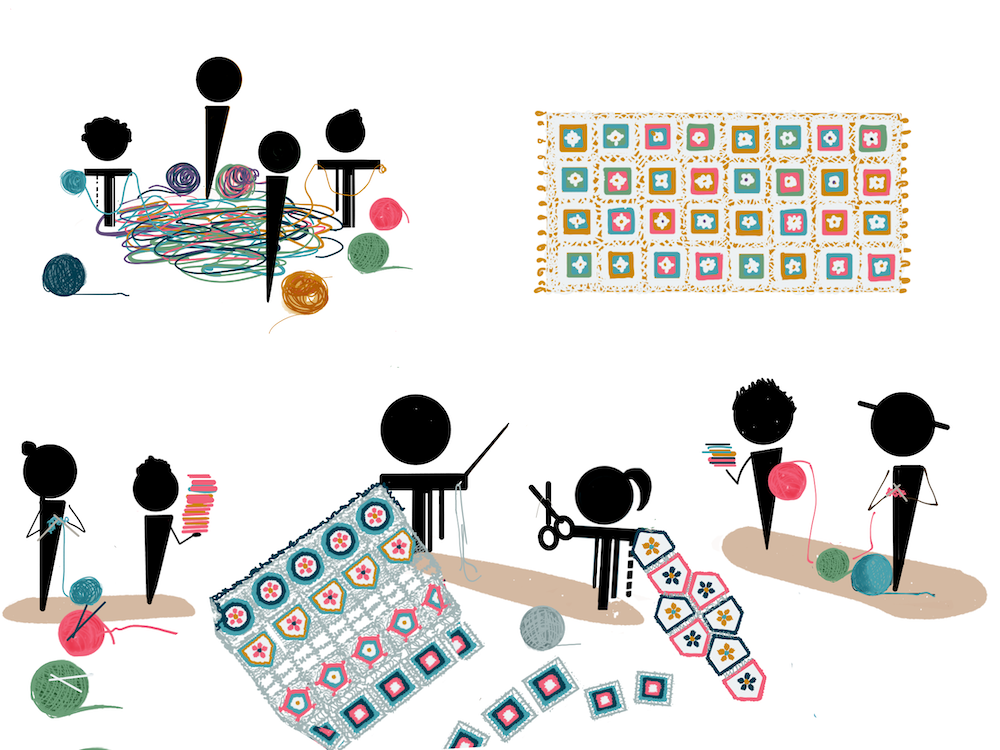
To help stimulate thinking about this, here’s the details of such a workshop, aimed at developers to connect Application Development, Data Engineering, and DevOps. The workshop views this work through a distributed systems lens, shifting attention to shared building blocks and establishing a common language across teams. Although this example is developer-centric, we think the same principle can be adapted just as effectively to any role that benefits from cross-disciplinary insight.
As we saw earlier, each discipline—Application Development, Data Engineering, and DevOps—faces the same distributed-systems realities, yet we still lack a shared language. The key challenges of these systems are the same. They must replicate state, tolerate partial failures, and still offer consistency guarantees to end users. A catalogue of patterns around the implementation of partitioning, replication, consistency, and consensus—that lets every team talk about the fundamentals without tool-specific jargon is a good start. One workshop will not turn people into expert generalists, but it does give them a head-start and a clear window into the challenges their peers tackle every day. That visibility lowers the barrier to cross-discipline tasks and deepens everyone’s understanding of the products and platforms they use.
The workshop structure – Building the miniature
One of the challenges in teaching the abstract patterns is that the developers need to do some mental mapping to connect the pattern to the product in use. This is why we chose an approach to structure the workshops around specific products, but then focus on the patterns that are most relevant and using the product as a window into the broader concepts.
The way we structured the workshops to teach distributed-system patterns, is by coding pocket versions of Kafka, Kubernetes, and Delta Lake. The idea is to pick a flagship product from each broad area of specialty, and build it step by step. Implementing a flagship system in just a few hundred lines flips your perspective from ‘a user’ of a product to ‘a builder’. An important mindset shift. To keep the exercise grounded in reality, write it in the product’s own language, mirror its file and method names, and rely on real infrastructure — ZooKeeper or etcd, an on-disk log, live sockets. The result stays close enough to the original to highlight the pivotal design choices while still giving you a safe canvas for experimentation. This approach is powerful, because each target is often open source, the moment the miniature works, you can open the full codebase on GitHub, recognise the directory structure, and feel confident submitting a patch. The miniature is not a toy; it is a gateway.
We have three workshops, one for each of the three systems.
Build Your Own Kafka — a miniature written in Java.
We use ZooKeeper for membership and store every message in a single append-only log. Even on one node you meet the classic fsync dilemma: flush every write for safety or batch for speed. Add a second process and you’re suddenly faced with many decisions. You need partition leader election, quorum acknowledgements, an in-sync replica list, and a high-water-mark so consumers never read uncommitted data. (A cluster-wide controller comes later, once multiple partitions appear.) Each mechanism maps to a production feature in Kafka. After walking this code you recognise why a broker stalls when a replica slows and know exactly which metric to graph next time it happens. The takeaway pattern is simple: an append-only log guarded by quorum replication—a design you will encounter throughout modern distributed systems.
Kubernetes from the Inside Out.
Start by writing a controller that watches a JSON document in etcd, then calls reconcile() until the local Docker daemon reflects that desired state. Very quickly you have to choose how to list running containers, queue events, and keep spec and status distinct—exactly the concerns that dominate the Kubernetes code base. Add real failure cases and things get tricky. What should the controller do when a container exits? How does a Postgres container keep its data? Each decision forces you to reason about restart policies and persistent-volume claims. After that exercise, the dense Go structs in kube-controller-manager feel like natural continuations of a model you already understand. The core learning: the power of a declarative desired state converged by reconcile loops – the common pattern of orchestration in modern distributed systems
ACID on Object Storage – A miniature Delta Lake.
Create a directory of Parquet files and pair it with a text log; each data change appends a JSON file naming the new data file. Move this setup into a miniature object store and every append becomes its own key-value write, with the Parquet file as the value. To handle concurrent writers, wrap the append in an optimistic lock that retries if the log tail changes. After a dozen commits start-up drags, so you add a checkpoint file and learn first-hand why Delta Lake emits one every N transactions. From there, time-travel queries drop out naturally from the log-plus-checkpoint design. The key takeaway, achieving ACID guarantees on eventually consistent storage through an immutable transaction log, optimistic concurrency, and periodic checkpointing – a pattern vital for modern data lakehouses.
Each miniature leaves you with a concrete pattern — append-only log, reconcile loop, optimistic commit—that travels well beyond the original context. When the next new tool arrives, you’ll recognise the pattern first and the product name second, which is precisely the habit that turns professionals into Expert Generalists.
Expert Generalists still need Specialists
While we’ve spent this article praising the Expert Generalist, we simultaneously do not deny the value of specialist knowledge. Even the most skilled Expert Generalist may have to spend valuable time figuring out the details of how to do something with a new platform. Their knowledge of common patterns helps them know what to look for, their skill helps them research faster, but it’s still longer than what a specialist already knows. Furthermore an Expert Generalist may miss a vital technique that’s particular to a domain, essentially because the Expert Generalist doesn’t know what they don’t know – a trap a specialist is far less likely to fall into. In our experience, a team of Expert Generalists without specialist knowledge of the core technology of their work will still get the job done, but will be significantly slower than a team with specialist skills on board.
The point here is that to be the most efficient, the team needs some specialist skill. There needs to be at least one deep specialist on a team for any core technology that the team is working with. But we’ve found that, providing the team is collaborating effectively, we don’t need very many. Often one or maybe two people is quite enough.
With someone with specialist knowledge present, a less knowledgeable Expert Generalist can quickly ask a question when they are faced with a task that needs the depth. Similarly the specialist should review the work of less knowledgeable colleagues, so they can spot when folks are taking the wrong path and show them the better way.
We think it is important to have such a specialist available full-time on the team. Much of their value comes from being responsive to questions and issues as they come up. In this situation, the important cost to monitor is the Cost of Delay – the speed of resolving questions is much more important that the utilization of the specialists. So it’s worth having a full-time specialist even if it means they aren’t fully occupied.2
2: This also indicates how to tell if you don’t have enough specialists on a team: measure how long it takes to answer questions. This follows Reinertsen’s advice to monitor queue sizes.
All of this does need everyone involved to have right kind of collaborative attitudes. The specialist needs to be someone who is keen to share their knowledge with everyone else on the team, and is approachable with dumb questions. The Expert Generalists need be comfortable demonstrating their ignorance, and actually enjoy being told they are doing something wrong in an unfamiliar environment. All in all there needs to be plenty of psychological safety around.
And, of course, the people with specialist skills can often be Expert Generalists themselves, with the specialty being legs in their T.
The flip-side of this is the danger of teams that consist only of specialists. Things outside their specialty can easily be missed. For example a data engineering team that’s full of specialist data engineers can miss anything that isn’t specific to data engineering, such as quality strategy, release management, and value articulation.
Expert Generalists in the Age of LLMs
Large Language Models and tools based on LLMs are growing in prominence. We’ve observed that Expert Generalist capabilities are considerably more valuable with these LLMs. The relationship between Expert Generalists and LLMs is often similar to that between Expert Generalists and specialists in a team. Similarly to a specialist, an LLM can rapidly answer questions that an Expert Generalist will have when working in a new domain. This significantly lowers the barrier for exploring completely new and unfamiliar tools, offering a quick way to get started.
An Expert Generalist, armed with a solid grasp of fundamentals and the knack to master principles and patterns, can truly harness the power of LLMs. They’re not just asking an LLM to write code in a new language; they’re able to ask more insightful questions, critically assess the AI-generated suggestions against their broader understanding, and adapt those suggestions to fit sound architectural patterns. Their curiosity discourages them from simply accepting an answer, but to understand how proposed solutions work – which is exactly the behavior needed to overcome the unreliability inherent in LLM-given advice.
We’ve noticed that Expert Generalists approach working with LLMs in a different way. Rather than looking for “the answer”, they prompt them to generate questions, explaining mechanisms, and providing examples and even tools that help explore the underlying mechanisms of an idea.
So, despite the early days of this technology, we think that the rise of LLMs will further enhance the importance of skilled Expert Generalists, and thus incentivize enterprises to put more effort into identifying, and training people with these skills.
Why Organizations Need Expert Generalists
The simplest reason why organizations should pay more attention to Expert Generalists is the loss of opportunities to staff teams. Finding exactly the right kind of specialist limits the candidate pool, either from hiring from outside, or by internal transfers. As long as there’s enough specialist skill available to assist, Expert Generalists often do as well, indeed often better, than adding another specialist.
But the benefits of Expert Generalists go further than that. Modern software systems involve many components, needing collaboration between specialties to deliver features to production. Too often we see stifled communication, with folks blocked while waiting on dependent teams to schedule necessary work. Lots of these queues between teams impedes flow, slowing down the release of valuable features.
Expert Generalists can unplug the pipes. Sometimes they do this by making the interaction smoother due to their overlapping skills, sometimes they know enough to do some of these dependent tasks themselves. Indeed one of the greatest values an Expert Generalist brings is the ability to Get Things Done. The customer-focus drives a good Expert Generalist to use their collaborativeness, curiosity, and skills blend to drive features to completion. If it requires crossing competency boundaries, they will find a way to do it. If they need to rapidly acquire some deeper skills, they will do so. They do risk taking on more than they can chew in the process, but that ability to close the deal is often imperative in getting critical software out the door.
Expert Generalists are particularly valuable at working across the specialist skill boundaries, handling interactions and filling in gaps.
The ability to see complex systems across their full breadth can be essential when things go wrong. Faults are often not in the depth of a single technology, but in the implicit interactions between them. If specialists can’t see the whole picture, they easily miss what falls between the gaps.
The presence of Expert Generalists crossing the competency boundaries can also increase knowledge transfer between competency groups, increasing everyone’s sympathy for related domains. This mechanism also encourages specialists to explore the Expert Generalist skill for themselves.
Specialists tend to use their familiar tool in contexts where it doesn’t make sense. We can’t fault them for that, if you’ve never seen a screwdriver, you’ll naturally reach for a hammer first. Expert Generalists are more likely to pick appropriate tools. There is a risk there, of introducing too many tools into an environment. Sometimes it’s better to use a familiar-but-inferior tool, than to introduce a complicated tool for a narrow task that’s a burden once the Expert Generalist moves on. A wise Expert Generalist will take that factor into account.
The broad view that Expert Generalist develops naturally leads them towards leadership roles. Crossing specialties encourages them to develop communication skills, particularly skills on explaining different disciplines to each other. Collaboration naturally grows relationships with key people around an organization. Customer-focus, Getting Things Done, build credibility with business leadership. Organizations that take deliberate steps to nurture Expert Generalists can reap the reward by growing technologists with a strategic perspective, without necessarily pushing them into management tracks.
All that said, despite the fact that we are clearly big proponents of Expert Generalists, there are downsides. Perhaps the greatest is that although we’ve found it possible to assess people for their Expert Generalist skill, it’s a difficult task, often requiring intensive participation from known-capable Expert Generalists. Years on the job, quizzes, and certifications are much easier tests to administer (although we are cynical about how they relate to delivering value).
A team full of Expert Generalists, but without particular skills for the central domains and platforms they are working on, will be less productive – at least until the Expert Generalists develop those skills. As we mentioned earlier, it’s important to have someone with those deep skills on the team, who can either be specialist in that domain or an Expert Generalist who has that as one of the legs in their “T”.
All in all, we’ve seen so many of our colleagues develop their Expert Generalist skill, without the name, and build upon it to be critical parts of successful technology and business initiatives. They are the people we have learned from, the people our clients go to with problems to solve and opportunities to exploit. Our hope with this article is that more people in our profession (and perhaps others) will start to recognize “Expert Generalist” as a first-class skill, and put more effort in describing its characteristics, how to assess it, and how to grow it. We believe that giving this skill proper recognition can do much to improve the practice of our profession.
Takeaways
Expert Generalists share several key traits
Curiosity
Collaborativeness
Customer-focus
Favoring fundamental knowledge
A blend of specialist and generalist skills
Sympathy for related domains
Teams should blend Expert Generalists with a few key specialists
Expert Generalist skills are enhanced by LLMs
Expert Generalists ensure complex tasks get done
We need to treat Expert Generalist as a first class skill
Evaluate people’s skill as an Expert Generalist in hiring and promotion
Develop training just as much as for specialist skills
A few years ago, my mum, who is in her 80s and not tech-savvy, almost got scammed. She received an email from what appeared to be her bank. It looked convincing, with a professional logo, clean formatting, and no obvious typos. The message said there was a suspicious charge on her account and presented a link asking her to “verify immediately.”
She wasn’t sure what to do. So she called me.
That hesitation saved her. The email was fake, and if she’d clicked on the link, she would’ve landed on a counterfeit login page, handing over her password details without knowing it.
That incident shook me. I design digital experiences for a living. And yet, someone I love almost got caught simply because a bad actor knew how to design well. That raised a question I haven’t stopped thinking about since: Can good UX protect people from online scams?
Quite apart from this incident, I see my Mum struggle with most apps on her phone. For example, navigating around her WhatsApp and YouTube apps seems to be very awkward for her. She is not used to accessing the standard app navigation at the bottom of the screen. What’s “intuitive” for many users is simply not understood by older, non-tech users.
Brief Overview Of How Scams Are Evolving Online
Online scams are becoming increasingly sophisticated, leveraging advanced technologies like artificial intelligence and deepfake videos to create more convincing yet fraudulent content. Scammers are also exploiting new digital platforms, including social media and messaging apps, to reach victims more directly and personally.
Phishing schemes have become more targeted, often using personal information taken from social media to craft customised attacks. Additionally, scammers are using crypto schemes and fake investment opportunities to lure those seeking quick financial gains, making online scams more convincing, diverse, and harder to detect.
The Rise In Fraud Targeting Older, Less Tech-savvy Users
In 2021, there were more than 90,000 older victims of fraud, according to the FBI. These cases resulted in US$1.7 billion in losses, a 74% increase compared with 2020. Even so, that may be a significant undercount since embarrassment or lack of awareness keeps some victims from reporting.
In Australia, the ACCC’s 2023 “Targeting Scams” report revealed that Australians aged 65 and over were the only age group to experience an increase in scam losses compared to the previous year. Their losses rose by 13.3% to $120 million, often following contact with scammers on social media platforms.
In the UK, nearly three in five (61%) people aged over 65 have been the target of fraud or a scam. On average, older people who have been scammed have lost nearly £4,000 each.
According to global consumer protection agencies, people over 60 are more likely to lose money to online scams than any other group. That’s a glaring sign: we need to rethink how we’re designing experiences for them.
They’re perceived as having more savings or assets.
They’re less likely to be digital natives, so they may not spot the red flags others do.
They tend to trust authority figures and brands, especially when messages appear “official.”
Scammers exploit trust. They impersonate banks, government agencies, health providers, and even family members. The one that scares me the most is the ability to use AI to mimic a loved one’s voice — anyone can be tricked by this.
Cognitive Load And Decision Fatigue In Older Users
Imagine navigating a confusing mobile app after a long day. Now imagine you’re in your 70s or 80s; your eyesight isn’t as sharp, your finger tapping isn’t as accurate, and every new screen feels like a puzzle.
As people age, they may experience slower processing speeds, reduced working memory, and lower tolerance for complexity. That means:
Multistep processes are harder to follow.
Unexpected changes in layout or behaviour can cause anxiety.
Vague language increases confusion.
Decision fatigue hits harder, too. If a user has already made five choices on an app, they may click the 6th button without fully understanding what it does, especially if it seems to be part of the flow.
Scammers rely on these factors. However, good UX can help to reduce it.
The Digital Literacy Gap And Common Pain Points
There’s a big difference between someone who grew up with the internet and someone who started using it in their 60s. Older users often struggle with:
Recognising safe vs. suspicious links;
Differentiating between ads and actual content;
Knowing how to verify sources;
Understanding terms like “multi-factor authentication” or “phishing”.
They may also be more likely to blame themselves when something goes wrong, leading to underreporting and repeat victimization.
Design can help to bridge some of that gap. But only if we build with their experience in mind.
The Role UX Designers Can Play In Preventing Harm
As UX designers, we focus on making things easy, intuitive, and accessible. But we can also shape how people understand risk.
Every choice, from wording to layout to colour, can affect how users interpret safety cues. When we design for the right cues, we help users avoid mistakes. When we get them wrong or ignore them altogether, we leave people vulnerable.
The good news? We have tools. We have influence. And in a world where digital scams are rising, we can use both to design for protection, not just productivity.
UX As The First Line Of Defence
The list below describes some UX design improvements that we can consider as designers:
1. Clear, Simple Design As A Defence Mechanism
Simple interfaces reduce user errors and scam risks.
Use linear flows, fewer input fields, and clear, consistent instructions.
Helps users feel confident and spot unusual activity.
2. Make Security Cues Obvious And Consistent
Users rely on visible indicators: padlocks, HTTPS, and verification badges.
Provide clear warnings for risky actions and unambiguous button labels.
3. Prioritize Clarity In Language
Use plain, direct language for critical actions (e.g., “Confirm $400 transfer”).
Avoid vague CTAs like “Continue” or playful labels like “Let’s go!”
Clear language reduces uncertainty, especially for older users.
4. Focus On Accessibility And Readability
Use minimum 16px fonts and high-contrast colour schemes.
Provide clear spacing and headings to improve scanning.
Accessibility benefits everyone, not just older users.
5. Use Friction To Protect, Not Hinder
Intentional friction (e.g., verification steps or warnings) can prevent mistakes.
Thoughtfully applied, it enhances safety without frustrating users.
6. Embed Contextual Education
Include just-in-time tips, tooltips, and passive alerts.
Help users understand risks within the flow, not after the fact.
What Can’t UX Fix?
Let’s be realistic: UX isn’t magic. We can’t stop phishing emails from landing in someone’s inbox. We can’t rewrite bad policies, and we can’t always prevent users from clicking on a well-disguised trap.
I personally think that even good UX may be limited in helping people like my mother, who will never be tech-savvy. To help those like her, ultimately, additional elements like support contact numbers, face-to-face courses on how to stay safe on your phone, and, of course, help from family members as required. These are all about human contact touch points, which can never be replaced by any kind of digital or AI support that may be available.
What we can do as designers is build systems that make hesitation feel natural. We can provide visual clarity, reduce ambiguity, and inject small moments of friction that nudge users to double-check before proceeding, especially in financial and banking apps and websites.
That hesitation might be the safeguard we need.
Other Key Tips To Help Seniors Avoid Online Scams
1. Be Skeptical Of Unsolicited Communications
Scammers often pose as trusted entities like banks, government agencies, or tech support to trick individuals into revealing personal information. Avoid clicking on links or downloading attachments from unknown sources, and never share personal details like your Medicare number, passwords, or banking information unless you’ve verified the request independently.
2. Use Strong, Unique Passwords And Enable Two-Factor Authentication
Create complex passwords that combine letters, numbers, and symbols, and avoid reusing passwords across different accounts. Whenever possible, enable two-factor authentication (2FA) to add an extra layer of security to your online accounts.
3. Stay Informed About Common Scams
Educate yourself on prevalent scams targeting seniors, such as phishing emails, romance scams, tech support fraud, and investment schemes. Regularly consult trusted resources like the NCOA and Age UK for updates on new scam tactics and prevention strategies.
4. Verify Before You Act
If you receive a request for money or personal information, especially if it’s urgent, take a moment to verify its legitimacy. Contact the organization directly using official contact information, not the details provided in the suspicious message. Be particularly cautious with unexpected requests from supposed family members or friends.
5. Report Suspected Scams Promptly
If you believe you’ve encountered a scam, report it to the appropriate authorities. Reporting helps protect others and contributes to broader efforts to combat fraud.
For more comprehensive information and resources, consider exploring the following:
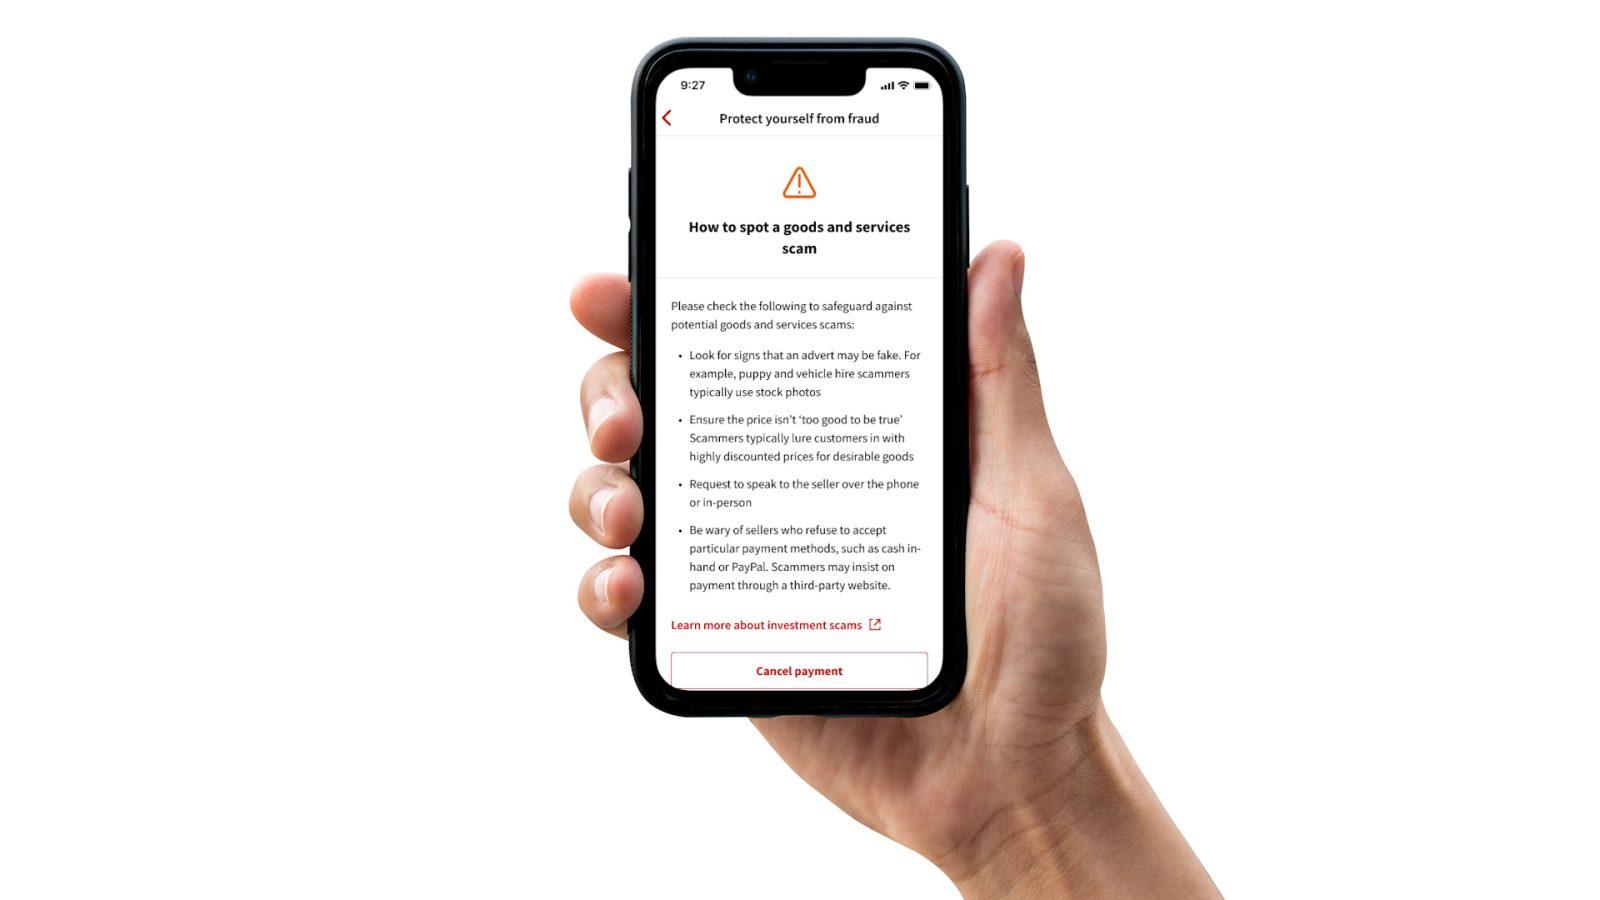
Examples Of Good Alert/Warning UX In Banking Platforms
I recall my mother not recognising a transaction in her banking app, and she thought that money was being taken from her account. It turns out that it was a legitimate transaction made in a local cafe, but the head office was located in a suburb she was not familiar with, which caused her to think it was fraudulent.
This kind of scenario could easily be addressed with a feature I have seen in the ING banking app (International Netherlands Group). You tap on the transaction to view more information about your transaction.
ING bank: You can now select a transaction to get more information on the business.
ING Banking App: click on the transaction to view more details. (Source: ING Help Hub)
Banking apps like NAB (National Australia Bank) now interrupt suspicious transfers with messages like, “Have you spoken to this person on the phone? Scammers often pose as trusted contacts.” NAB said that December was the biggest month in 2024 for abandoned payments, with customers scrapping $26 million worth of payments after receiving a payment alert.
Macquarie Bank has introduced additional prompts for bank transactions to confirm the user’s approval of all transactions.
Monzo Bank has added three security elements to reduce online fraud for banking transactions:
Verified Locations: Sending or moving large amounts of money from locations that the account holder has marked as safe. This helps block fraudsters from accessing funds if they’re not near these trusted places.
Trusted Approvers: For large transactions, a trusted contact must give the green light. This adds protection if their phone is stolen or if they want to safeguard someone who may be more vulnerable.
Secure QR Codes: Account holders can generate a special QR code and keep it stored in a safe place. They scan it when needed to unlock extra layers of security.
Email platforms like Gmail highlight spoofed addresses or impersonation attempts with yellow banners and caution icons.
These interventions are not aimed at stopping users, but they can give them one last chance to rethink their transactions. That’s powerful.
Finally, here’s an example of clear UX cues that streamline the experience and guide users through their journey with greater confidence and clarity.
Conclusion
Added security features in banking apps, like the examples above, aren’t just about preventing fraud; they’re examples of thoughtful UX design. These features are built to feel natural, not burdensome, helping users stay safe without getting overwhelmed. As UX professionals, we have a responsibility to design with protection in mind, anticipating threats and creating experiences that guide users away from risky actions. Good UX in financial products isn’t just seamless; it’s about security by design.
And in a world where digital deception is on the rise, protection is usability. Designers have the power and the responsibility to make interfaces that support safer choices, especially for older users, whose lives and life savings may depend on a single click.
Let’s stop thinking of security as a backend concern or someone else’s job. Let’s design systems that are scam-resistant, age-inclusive, and intentionally clear. And don’t forget to reach out with the additional human touch to help your older family members.
When it comes down to it, good UX isn’t just helpful — it can be life-changing.
It’s time for another round of vulnerabilities discovered in the wild. This time, it’s two local privilege escalation (LPE) vulnerabilities that affect SSH and libblockdev – both of which are found in most major Linux distributions.
The vulnerabilities in question are CVE-2025-6018 (which allows a hacker to impersonate a user via SSH) and CVE-2025-6019 (which is exploitable via the udisks service and allows a user to escalate access to root privileges).
Pumpkin Chang, a security researcher at DEVCORE who focuses on Linux kernel security, discusses these issues in depth in his blog. Chang explains D-Bus and Polkit and how these mechanisms are leveraged to perform certain operations by impersonating actual users.
Additionally, a report from Qualys’ senior manager, Saeed Abbasi, discusses both LPE flaws. Abbassi says, “These modern ‘local-to-root’ exploits have collapsed the gap between an ordinary logged-in user and a full system takeover.”
Abbasi continues, “By chaining legitimate services such as udisks loop-mounts and PAM/environment quirks, attackers who own any active GUI or SSH session can vault across polkit’s allow_active trust zone and emerge as root in seconds.” Finally, he adds, “Nothing exotic is required: each link is pre-installed on mainstream Linux distros and their server builds.”
The key here is “Nothing exotic is required.” In other words, these vulnerabilities don’t require any non-standard tools to exploit.
As far as mitigation is concerned, Abbassi states, “To mitigate this vulnerability, modify the polkit rule for ‘org.freedesktop.udisks2.modify-device’. Change the allow_active setting from yes to auth_admin.”
Per fornire le migliori esperienze, utilizziamo tecnologie come i cookie per memorizzare e/o accedere alle informazioni del dispositivo. Il consenso a queste tecnologie ci permetterà di elaborare dati come il comportamento di navigazione o ID unici su questo sito. Non acconsentire o ritirare il consenso può influire negativamente su alcune caratteristiche e funzioni.
Funzionale
Always active
L'archiviazione tecnica o l'accesso sono strettamente necessari al fine legittimo di consentire l'uso di un servizio specifico esplicitamente richiesto dall'abbonato o dall'utente, o al solo scopo di effettuare la trasmissione di una comunicazione su una rete di comunicazione elettronica.
Preferenze
L'archiviazione tecnica o l'accesso sono necessari per lo scopo legittimo di memorizzare le preferenze che non sono richieste dall'abbonato o dall'utente.
Statistiche
L'archiviazione tecnica o l'accesso che viene utilizzato esclusivamente per scopi statistici.L'archiviazione tecnica o l'accesso che viene utilizzato esclusivamente per scopi statistici anonimi. Senza un mandato di comparizione, una conformità volontaria da parte del vostro Fornitore di Servizi Internet, o ulteriori registrazioni da parte di terzi, le informazioni memorizzate o recuperate per questo scopo da sole non possono di solito essere utilizzate per l'identificazione.
Marketing
L'archiviazione tecnica o l'accesso sono necessari per creare profili di utenti per inviare pubblicità, o per tracciare l'utente su un sito web o su diversi siti web per scopi di marketing simili.